Note
Access to this page requires authorization. You can try signing in or changing directories.
Access to this page requires authorization. You can try changing directories.
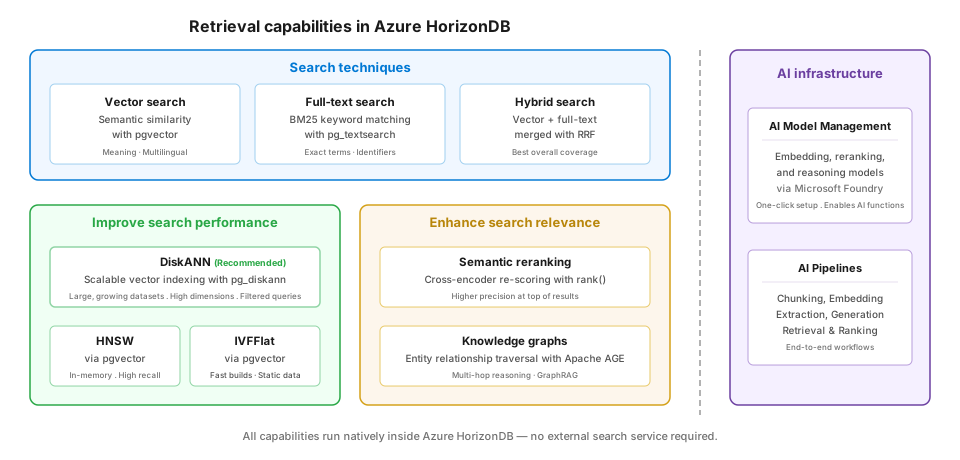
Modern applications demand search that goes beyond simple keyword matching. Users expect search to understand intent, handle synonyms, work across languages, and return the most relevant results - even when the query doesn't share exact words with the content.
This article introduces the core retrieval techniques available in Azure HorizonDB, explains when and why to use each one, and shows how they fit together into a complete search strategy. For implementation details, each section links to the corresponding deep-dive article.
Why traditional search isn't enough
Traditional database queries rely on exact matches: a WHERE clause or a LIKE pattern. These approaches break down when users search with natural language, use different terminology than what's stored, or ask questions that span multiple concepts. Consider these scenarios:
- A user searches for "lightweight laptop for travel" but the product description says "ultraportable notebook weighing under 1 kg."
- A support agent searches for "app crashes on startup" but the knowledge base article is titled "application initialization failure."
- A researcher queries "climate change effects on agriculture" across a multilingual document corpus.
In each case, exact-match queries return nothing, yet the relevant content exists. Semantic and hybrid search techniques bridge this gap. Vector search understands that "lightweight laptop" and "ultraportable notebook" mean the same thing, full-text search handles exact terms and identifiers with precision, and hybrid search combines both to cover the widest range of query types. Azure HorizonDB provides the building blocks to implement these patterns entirely within your database, optimized for high-performance and accuracy, eliminating the need for external search services.
Vector search
Vector search finds results based on semantic similarity rather than exact keyword matches. It works by converting text (or other content) into numerical representations called vector embeddings which are dense arrays of floating-point numbers that capture the meaning of the content. Texts with similar meanings produce vectors that are geometrically close together in high-dimensional space, even if they use entirely different words.
How it works
- Prepare and embed your data. Chunk large documents into meaningful segments, then use an embedding model (for example,
text-embedding-3-small) to convert each chunk into a vector. Store the vector alongside your relational data using thevectorextension in PostgreSQL. For guidance on chunking strategies and embedding pipelines, see Prepare data for AI app and agent development in Azure HorizonDB (Preview). - Embed the query. At query time, convert the user's search query into a vector using the same embedding model.
- Find nearest neighbors. The database computes the distance between the query vector and all stored vectors, returning the closest matches, which represent the most semantically similar results.
When to use it
Vector search excels at understanding meaning and intent. Use it when users search with natural language, when you need multilingual matching, or when queries and documents use different terminology for the same concepts. It's the foundation of Retrieval-Augmented Generation (RAG) applications.
Azure HorizonDB implementation
Azure HorizonDB supports vector search through the pgvector extension, with built-in embedding generation via the azure_ai extension's create_embeddings() function.
To learn more, see:
- Implement vector search in Azure HorizonDB using the pgvector extension (Preview)
- Prepare data for AI app and agent development in Azure HorizonDB (Preview)
Full-text search
Full-text search is keyword-based retrieval that finds documents containing specific terms. Unlike simple LIKE queries, full-text search tokenizes text, removes stop words, stems words to their root forms, and ranks results by relevance using algorithms like BM25.
How it works
- Analyze the text. The system breaks documents into tokens, normalizes the text (lowercases and stems words to their root forms), and removes common stop words. It stores the result in an inverted index that maps each term to the documents containing it.
- Parse the query. The user's search query goes through the same normalization process, so "running" matches "run" and "ran."
- Match and rank. The index identifies documents containing the query terms and ranks them by relevance - accounting for how often a term appears, how rare it is across the corpus, and document length.
When to use it
Full-text search is precise and fast. Use it when queries contain exact terms, identifiers, product codes, proper names, or technical jargon where semantic similarity isn't helpful. It also provides interpretable, auditable relevance scores.
Azure HorizonDB implementation
Azure HorizonDB offers full-text search through pg_textsearch, which provides BM25 ranking, fuzzy matching, phrase proximity search, and CJK language analyzer support.
To learn more, see Full-text search with pg_textsearch in Azure HorizonDB (Preview).
Hybrid search
Hybrid search combines vector search and full-text search, running both queries simultaneously and merging their results into a single ranked list. This approach captures both semantic meaning (from vector search) and keyword precision (from full-text search), consistently outperforming either technique alone.
How it works
- Run both searches in parallel. Execute a vector similarity query and a full-text query against the same dataset.
- Merge results with Reciprocal Rank Fusion (RRF). Because raw BM25 scores and cosine similarity scores exist on incompatible scales, RRF combines them by position rather than score. Each document receives a fused score based on its rank in each result list, and documents appearing near the top of multiple lists receive the highest combined scores.
- Return the unified ranking. The merged results balance semantic understanding with keyword precision.
When to use it
Hybrid search is the recommended approach for most production search applications. It handles the widest variety of query types from natural language questions to exact keyword lookups without requiring users to choose a search mode.
Azure HorizonDB implementation
Azure HorizonDB supports hybrid search by combining pgvector for vector similarity, pg_textsearch for BM25 keyword matching, and SQL-based RRF to merge results. You can optionally add Scalable vector indexing with DiskANN (Preview) for prefiltered hybrid queries.
To learn more, see Hybrid search in Azure HorizonDB (Preview).
Improve search performance
As your dataset grows, search performance becomes critical. Azure HorizonDB provides several vector indexing strategies to maintain fast query response times at scale.
Vector indexing
Without an index, vector search performs an exact nearest neighbor scan - comparing the query vector against every row. This approach guarantees perfect recall but becomes impractical for large datasets. Approximate Nearest Neighbor (ANN) indexes trade a small amount of recall for dramatically lower latency by searching only a relevant subset of the vector space.
Azure HorizonDB supports three vector index types:
| Index | Algorithm | Best for |
|---|---|---|
| IVFFlat | K-means clustering with probe-based search. | Large, relatively static datasets where fast build times matter. |
| HNSW | Hierarchical navigable small world graph. | General-purpose workloads with good speed-recall trade-offs. |
| DiskANN | Microsoft Research's graph-based algorithm, optimized for SSD-resident data. | Production workloads from thousands to billions of vectors, with in-place updates and advanced filtering. Recommended default for Azure HorizonDB. |
To learn more, see:
- Choose the right vector index for your workload in Azure HorizonDB (Preview)
- Optimize performance when using pgvector in Azure HorizonDB (Preview)
- Scalable vector indexing with DiskANN (Preview)
Enhance search relevance
Retrieval is only the first step. Even the best hybrid search can return results that are topically related but don't directly answer the user's question. Azure HorizonDB provides two techniques to enhance the relevance of your search results.
Semantic reranking
Semantic reranking is a second-stage scoring pass that takes the top results from an initial retrieval (vector, full-text, or hybrid) and rescores them using a more powerful language model. The two-stage pattern exists because cross-encoder models are highly accurate but too expensive to run against millions of candidates. By applying them to a small shortlist (typically the top 50-150 results), you get higher precision at the top of the ranking.
The azure_ai extension's rank() AI function brings semantic reranking directly into your SQL queries. AI Model Management (limited preview) provides Cohere-rerank-v4.0-fast as a ready-to-use reranker, and you can combine it with vector search for a complete retrieval-and-rerank pipeline.
To learn more, see Semantic reranking with the rank() function (Preview) and Implement durable AI pipelines in Azure HorizonDB (Preview)
Knowledge graphs and GraphRAG
Vector search retrieves content that's semantically similar to a query, but it can't follow relationships between entities. For questions like "What are all the subsidiaries of Company X and their financial risks?", vector search returns similar-sounding text. A knowledge graph traverses typed relationships like Company X → hasSubsidiary → Company Y → hasRisk → Regulatory Filing and assembles a structured, complete answer.
GraphRAG (Graph-based Retrieval-Augmented Generation) combines knowledge graphs with vector search to enhance RAG pipelines. By extracting entities and relationships from your data into a graph structure, then traversing that graph at query time, GraphRAG retrieves not just directly relevant content, but contextually connected information across entity boundaries.
Azure HorizonDB supports knowledge graphs through the Apache AGE graph extension, combined with the azure_ai extension's AI functions for automated entity and relationship extraction.
To learn more, see:
- Graph-RAG patterns with Azure HorizonDB (Preview)
- Tutorial: Build a knowledge graph from unstructured text using AI Functions and Apache AGE (Preview)
Build a complete retrieval pipeline
The retrieval techniques described in this article work best when combined. A typical production search pipeline in Azure HorizonDB follows this pattern:
- Prepare your data. Chunk large documents, clean text, and structure your content for retrieval. See Prepare data for AI app and agent development in Azure HorizonDB (Preview).
- Embed. Generate vector embeddings for searchable text fields using
create_embeddings(). - Index. Create a DiskANN index on your vector column and an
ftsindex for full-text search to ensure fast retrieval at scale. - Retrieve. Run hybrid search combining vector similarity and BM25 keyword matching, merged with Reciprocal Rank Fusion.
- Rerank. Pass the top results through semantic reranking with
rank()to surface the most relevant answers. - Enhance (optional). For complex, multi-hop queries, augment retrieval with knowledge graph traversal using GraphRAG patterns.
To learn how to build a retrieval-and-rerank pipeline, see Implement durable AI pipelines in Azure HorizonDB (Preview). For a hands-on example, see Tutorial: Build a semantic search application with Azure HorizonDB (Preview).