Note
Access to this page requires authorization. You can try signing in or changing directories.
Access to this page requires authorization. You can try changing directories.
Retrieval-augmented generation (RAG) is a technique for grounding a large language model's responses in your own content. Instead of relying only on what the model learned during training, a RAG pipeline:
- Converts your documents into vector embeddings
- Stores those embeddings in a searchable vector database
- At query time, retrieves the most relevant chunks for a user's question and passes them to an LLM, which generates an answer grounded in the retrieved content
The result is natural-language search over your own documents, with answers grounded in the retrieved content.
Enable Azure Files for RAG workloads
Organizations often store large document collections on Azure file shares. The tutorials in this section show how to layer a RAG pipeline on top of an existing Azure file share, so you can add natural-language search over your documents without changing how the share is provisioned or configured.
Every tutorial in this section follows the same workflow, which can scale from local experimentation to an automated production pipeline:
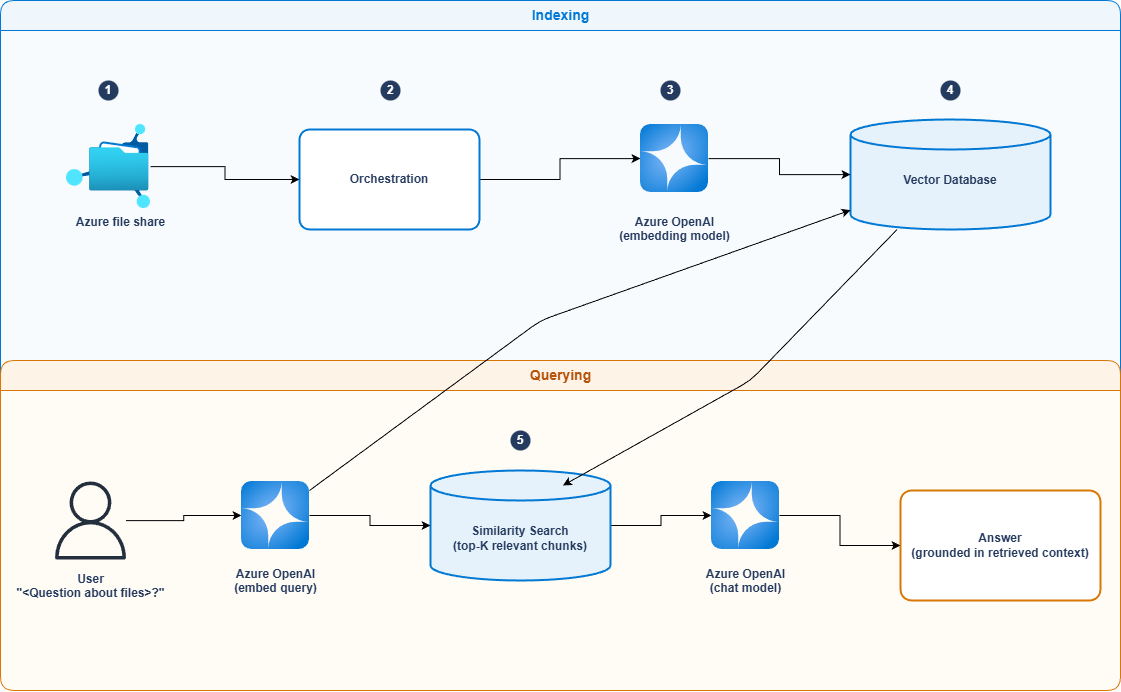
The workflow has two phases: **indexing**, which loads documents from an Azure file share, chunks them, embeds the chunks with an Azure OpenAI model, and stores the vectors in a vector database; and **querying**, which embeds a user's question, retrieves the top-K matching chunks from the vector database, and passes them with the question to an Azure OpenAI chat model to generate a grounded answer.
Indexing:
- Azure file share. Enumerate and download source documents. See Prepare Azure Files data for a reference implementation.
- Orchestration. Use a framework to parse each file into text with Azure Files metadata, then split it into overlapping chunks for embedding.
- Azure OpenAI embedding model. Send each chunk to an Azure OpenAI embedding deployment to produce a vector.
- Vector database. Upsert the vectors, along with their text and source metadata, into a vector database.
Querying:
- Grounded answer. Embed the user's question with the same embedding model, run a similarity search against the vector database for the top-K chunks, and pass the question and chunks to an Azure OpenAI chat model to generate a grounded answer.
Common RAG scenarios
The tutorials in this section focus on document-based question answering, but the same indexing and querying pattern applies to any workload that searches your own content by similarity. Azure Files can hold the source data for many of these use cases:
- Document question answering. Ask natural-language questions about contracts, policies, manuals, research papers, and support articles stored on your file share.
- Enterprise knowledge assistants. Combine internal wikis, onboarding docs, and runbooks on Azure Files to power chat assistants that answer with links to the source file.
- Fraud and anomaly detection. Embed transaction records or log entries and compare them to past patterns to flag ones that look unusual.
- Recommender systems. Turn user preferences, product descriptions, or media metadata into embeddings, then find related items by similarity.
- Code and configuration search. Index source files, deployment templates, or configuration archives on Azure Files to power "find similar" and refactoring tools.
- Compliance and eDiscovery. Find documents that are similar in meaning to a reference file across large archival shares, even when they don't share the same keywords.
In each case, Azure Files holds the source data, and the RAG pipeline indexes it into a vector database that the application queries.
Tutorials in this section
Start with the setup article to prepare your project directory and authenticate to Azure Files, then choose a framework and vector database:
| Pinecone | Weaviate | Qdrant | |
|---|---|---|---|
| LangChain | Tutorial | Tutorial | Tutorial |
| LlamaIndex | Tutorial | Tutorial | Tutorial |
| Haystack | Tutorial | Tutorial | Tutorial |