Hanya berlaku untuk: Portal Foundry (klasik). Artikel ini tidak tersedia untuk portal Foundry baru.
Pelajari selengkapnya tentang portal baru.
Nota
Tautan dalam artikel ini mungkin membuka konten dalam dokumentasi Microsoft Foundry baru alih-alih dokumentasi Foundry (klasik) yang Anda lihat sekarang.
Penyelesaian tersimpan memungkinkan Anda mengambil riwayat percakapan dari sesi penyelesaian obrolan untuk digunakan sebagai himpunan data untuk evaluasi dan penyempurnaan.
Dukungan penyimpanan hasil akhir
Ketersediaan model dan wilayah
Selama Anda menggunakan Chat Completions API untuk inferensi, Anda dapat memanfaatkan hasil penyelesaian yang telah disimpan. Ini didukung untuk semua model OpenAI Azure, dan di semua wilayah yang didukung (termasuk wilayah khusus global).
Untuk mengaktifkan penyelesaian tersimpan untuk penyebaran OpenAI Azure Anda, atur parameter store ke True.
metadata Gunakan parameter untuk memperkaya himpunan data penyelesaian tersimpan Anda dengan informasi tambahan.
import os
from openai import OpenAI
from azure.identity import DefaultAzureCredential, get_bearer_token_provider

token_provider = get_bearer_token_provider(
    DefaultAzureCredential(), "https://ai.azure.com/.default"
)

client = OpenAI(
  base_url="https://YOUR-RESOURCE-NAME.openai.azure.com/openai/v1/",
  api_key=token_provider,
)

completion = client.chat.completions.create(

    model="gpt-4o", # replace with model deployment name
    store= True,
    metadata =  {
    "user": "admin",
    "category": "docs-test",
  },
    messages=[
    {"role": "system", "content": "Provide a clear and concise summary of the technical content, highlighting key concepts and their relationships. Focus on the main ideas and practical implications."},
    {"role": "user", "content": "Ensemble methods combine multiple machine learning models to create a more robust and accurate predictor. Common techniques include bagging (training models on random subsets of data), boosting (sequentially training models to correct previous errors), and stacking (using a meta-model to combine base model predictions). Random Forests, a popular bagging method, create multiple decision trees using random feature subsets. Gradient Boosting builds trees sequentially, with each tree focusing on correcting the errors of previous trees. These methods often achieve better performance than single models by reducing overfitting and variance while capturing different aspects of the data."}
    ]
)

print(completion.choices[0].message)
Penting
Gunakan kunci API dengan hati-hati. Jangan sertakan kunci API langsung dalam kode Anda, dan jangan pernah mempostingnya secara publik. Jika Anda menggunakan kunci API, simpan dengan aman di Azure Key Vault. Untuk informasi selengkapnya tentang menggunakan kunci API dengan aman di aplikasi Anda, lihat kunci API dengan Azure Key Vault.
Untuk informasi selengkapnya tentang keamanan layanan AI, lihat Autentikasi permintaan ke layanan Azure AI.
import os
from openai import OpenAI

client = OpenAI(
    api_key=os.getenv("AZURE_OPENAI_API_KEY"),
    base_url="https://YOUR-RESOURCE-NAME.openai.azure.com/openai/v1/"
    )

completion = client.chat.completions.create(

    model="gpt-4o", # replace with model deployment name
    store= True,
    metadata =  {
    "user": "admin",
    "category": "docs-test",
  },
    messages=[
    {"role": "system", "content": "Provide a clear and concise summary of the technical content, highlighting key concepts and their relationships. Focus on the main ideas and practical implications."},
    {"role": "user", "content": "Ensemble methods combine multiple machine learning models to create a more robust and accurate predictor. Common techniques include bagging (training models on random subsets of data), boosting (sequentially training models to correct previous errors), and stacking (using a meta-model to combine base model predictions). Random Forests, a popular bagging method, create multiple decision trees using random feature subsets. Gradient Boosting builds trees sequentially, with each tree focusing on correcting the errors of previous trees. These methods often achieve better performance than single models by reducing overfitting and variance while capturing different aspects of the data."}
    ]
)

print(completion.choices[0].message)
Microsoft Entra ID
curl $AZURE_OPENAI_ENDPOINT/openai/v1/chat/completions \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $AZURE_OPENAI_AUTH_TOKEN" \
  -d '{
    "model": "gpt-4o",
    "store": true,
    "messages": [
      {
        "role": "system",
        "content": "You are a helpful assistant."
      },
      {
        "role": "user",
        "content": "Hello!"
      }
    ]
  }'
Kunci API
curl $AZURE_OPENAI_ENDPOINT/openai/v1/chat/completions \
  -H "Content-Type: application/json" \
  -H "api-key: $AZURE_OPENAI_API_KEY" \
  -d '{
    "model": "gpt-4o",
    "store": true,
    "messages": [
      {
        "role": "system",
        "content": "You are a helpful assistant."
      },
      {
        "role": "user",
        "content": "Hello!"
      }
    ]
  }'
{
  "id": "chatcmpl-B4eQ716S5wGUyFpGgX2MXnJEC5AW5",
  "choices": [
    {
      "finish_reason": "stop",
      "index": 0,
      "logprobs": null,
      "message": {
        "content": "Ensemble methods enhance machine learning performance by combining multiple models to create a more robust and accurate predictor. The key techniques include:\n\n1. **Bagging (Bootstrap Aggregating)**: Involves training multiple models on random subsets of the data to reduce variance and overfitting. A popular method within bagging is Random Forests, which build numerous decision trees using random subsets of features and data samples.\n\n2. **Boosting**: Focuses on sequentially training models, where each new model attempts to correct the errors made by previous ones. Gradient Boosting is a common boosting technique that builds trees sequentially, concentrating on the mistakes of earlier trees to improve accuracy.\n\n3. **Stacking**: Uses a meta-model to combine predictions from various base models, leveraging their strengths to enhance overall predictions.\n\nThese ensemble methods generally outperform individual models because they effectively handle overfitting, reduce variance, and capture diverse aspects of the data. In practical applications, they are valued for their ability to improve model accuracy and stability.",
        "refusal": null,
        "role": "assistant",
        "audio": null,
        "function_call": null,
        "tool_calls": null
      },
      "content_filter_results": {
        "hate": {
          "filtered": false,
          "severity": "safe"
        },
        "protected_material_code": {
          "filtered": false,
          "detected": false
        },
        "protected_material_text": {
          "filtered": false,
          "detected": false
        },
        "self_harm": {
          "filtered": false,
          "severity": "safe"
        },
        "sexual": {
          "filtered": false,
          "severity": "safe"
        },
        "violence": {
          "filtered": false,
          "severity": "safe"
        }
      }
    }
  ],
  "created": 1740448387,
  "model": "gpt-4o-2024-08-06",
  "object": "chat.completion",
  "service_tier": null,
  "system_fingerprint": "fp_b705f0c291",
  "usage": {
    "completion_tokens": 205,
    "prompt_tokens": 157,
    "total_tokens": 362,
    "completion_tokens_details": {
      "accepted_prediction_tokens": 0,
      "audio_tokens": 0,
      "reasoning_tokens": 0,
      "rejected_prediction_tokens": 0
    },
    "prompt_tokens_details": {
      "audio_tokens": 0,
      "cached_tokens": 0
    }
  },
  "prompt_filter_results": [
    {
      "prompt_index": 0,
      "content_filter_results": {
        "hate": {
          "filtered": false,
          "severity": "safe"
        },
        "jailbreak": {
          "filtered": false,
          "detected": false
        },
        "self_harm": {
          "filtered": false,
          "severity": "safe"
        },
        "sexual": {
          "filtered": false,
          "severity": "safe"
        },
        "violence": {
          "filtered": false,
          "severity": "safe"
        }
      }
    }
  ]
}
Setelah penyelesaian tersimpan diaktifkan untuk penyebaran Azure OpenAI, penyelesaian tersebut akan mulai muncul di portal Microsoft Foundry pada panel Penyelesaian Tersimpan.
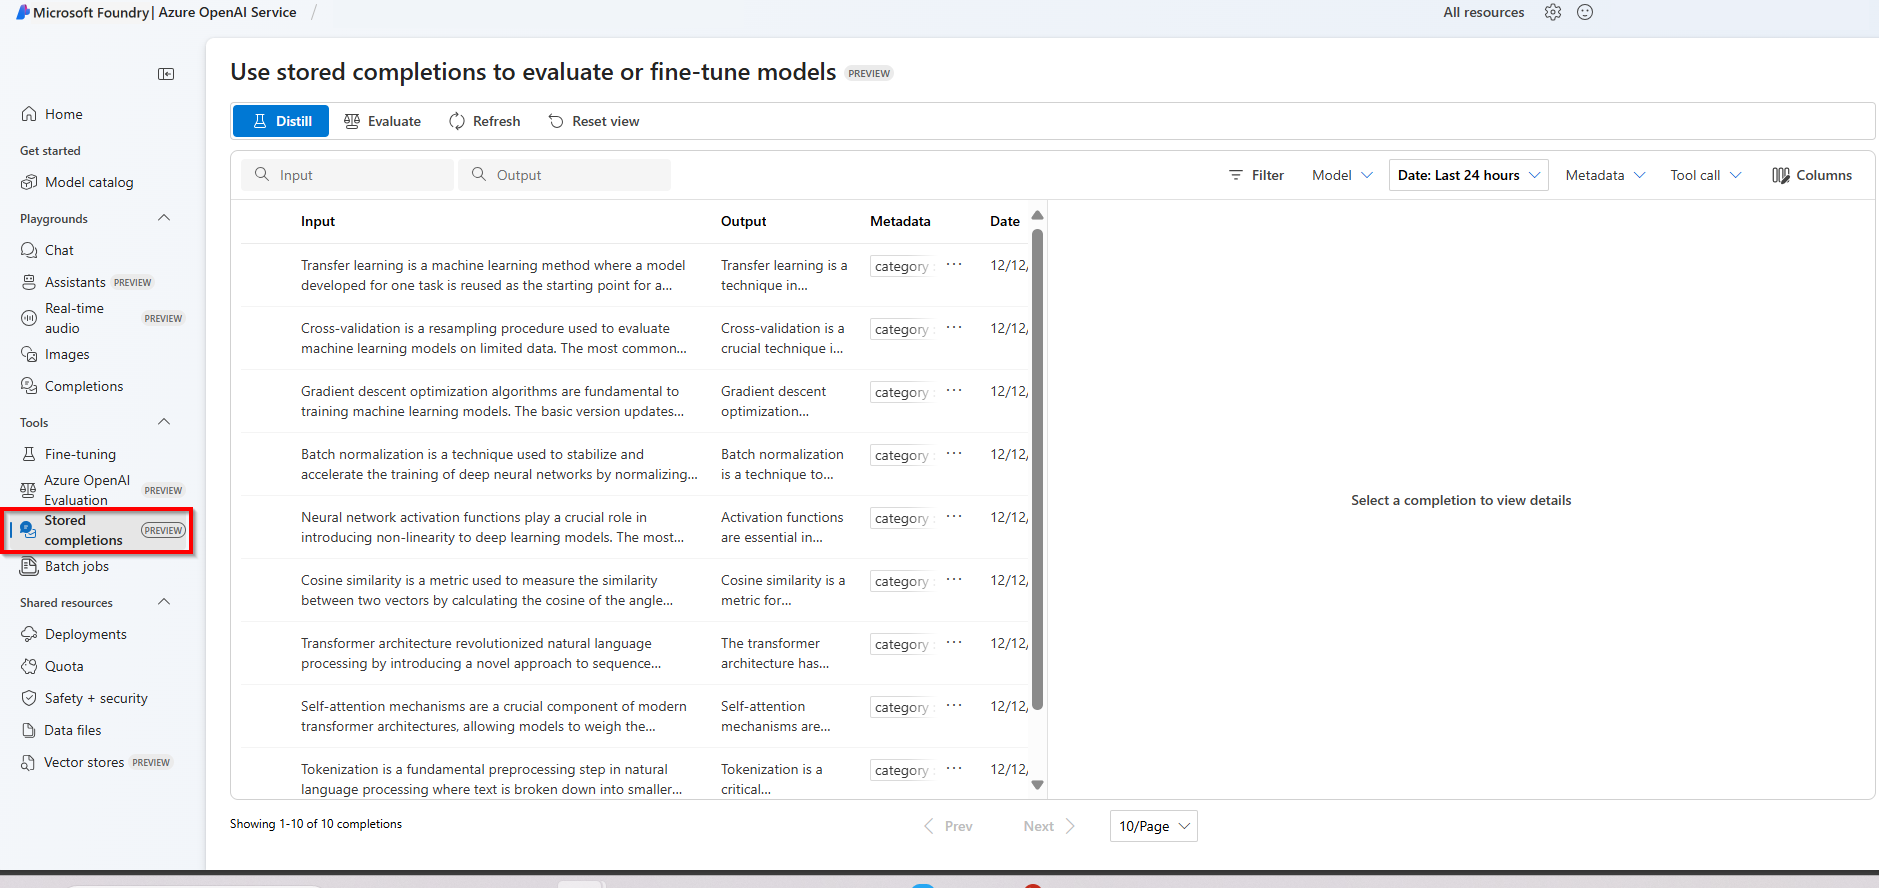
Distilasi
Penyulingan memungkinkan Anda mengubah hasil akhir yang telah disimpan menjadi kumpulan data untuk penyempurnaan. Kasus penggunaan umum adalah menggunakan hasil penyelesaian yang disimpan dengan model yang lebih besar dan lebih kuat untuk tugas tertentu dan kemudian menggunakan hasil penyelesaian yang disimpan untuk melatih model yang lebih kecil dengan contoh interaksi model yang berkualitas tinggi.
Penyulingan memerlukan minimal 10 kelengkapan yang tersimpan, meskipun disarankan untuk menyediakan ratusan hingga ribuan kelengkapan yang tersimpan agar memperoleh hasil terbaik.
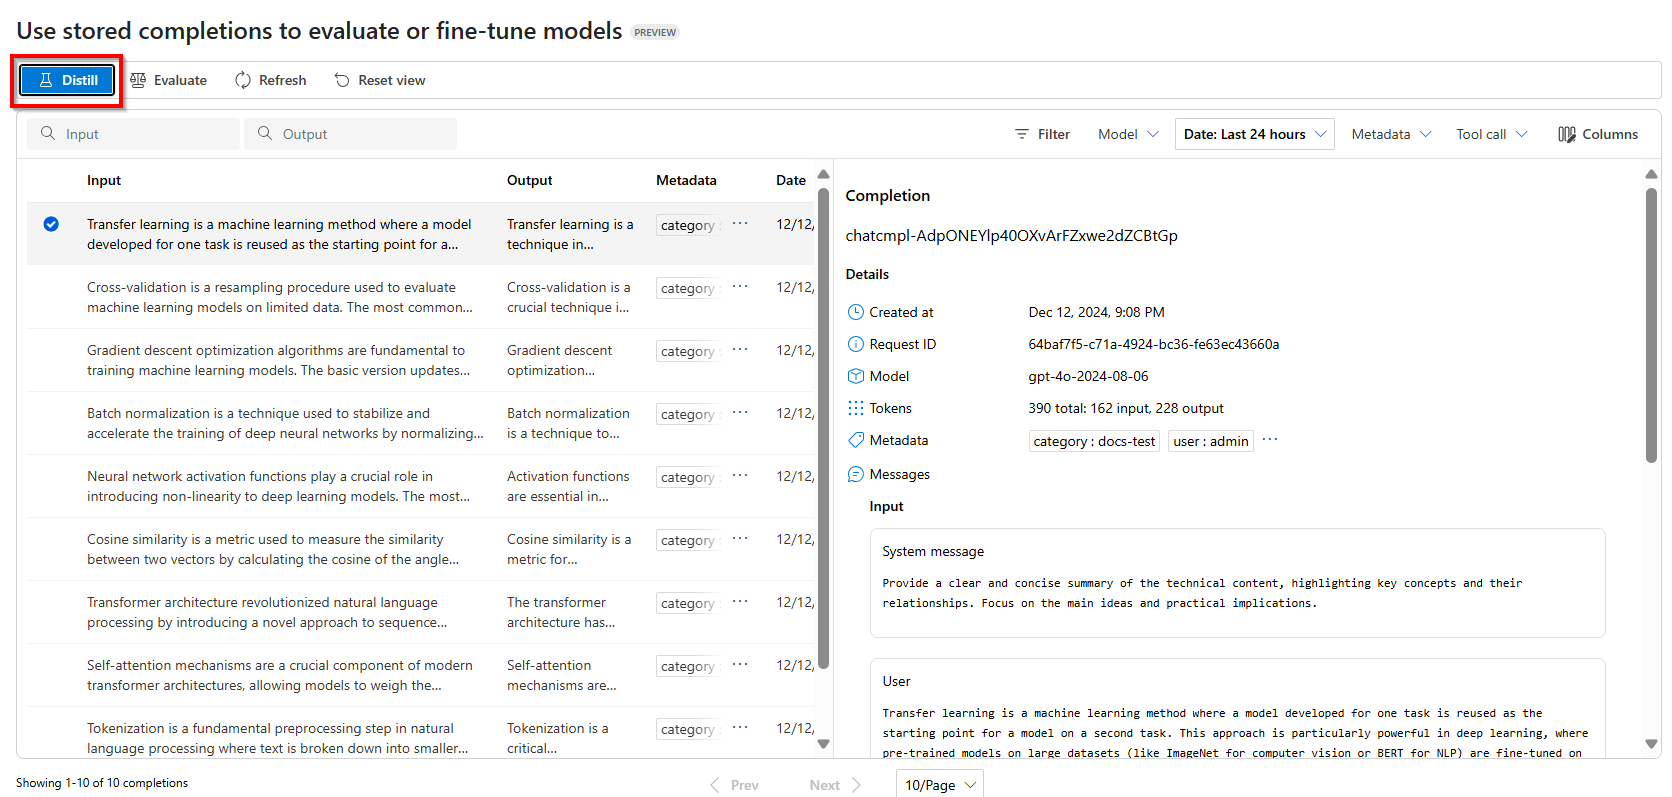
Dari panel Stored Completions di portal Foundry, gunakan opsi Filter untuk memilih penyelesaian yang ingin Anda gunakan untuk melatih model Anda.
Untuk memulai penyulingan, pilih Distill
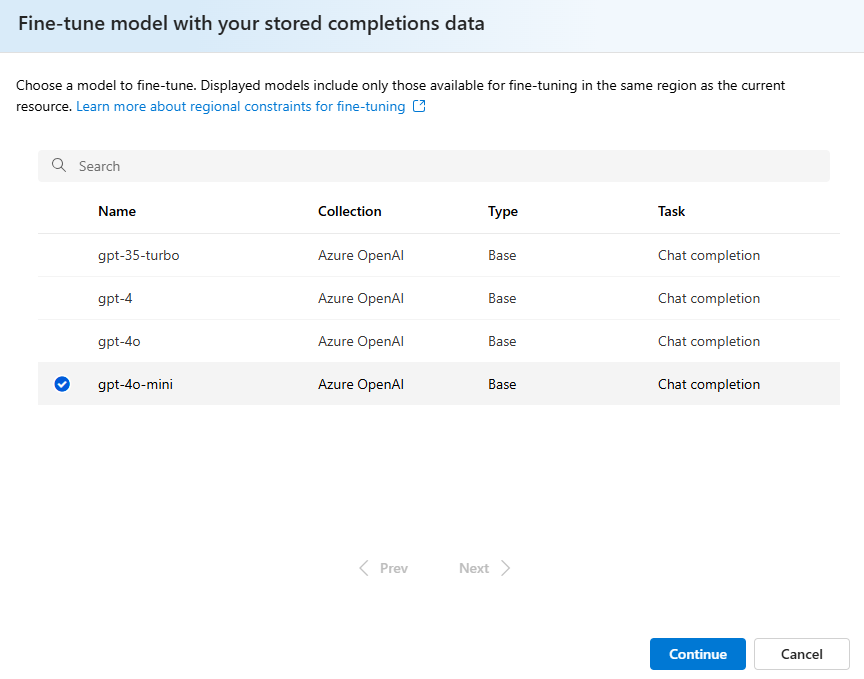
Pilih model mana yang ingin Anda sesuaikan dengan himpunan data penyelesaian yang disimpan.
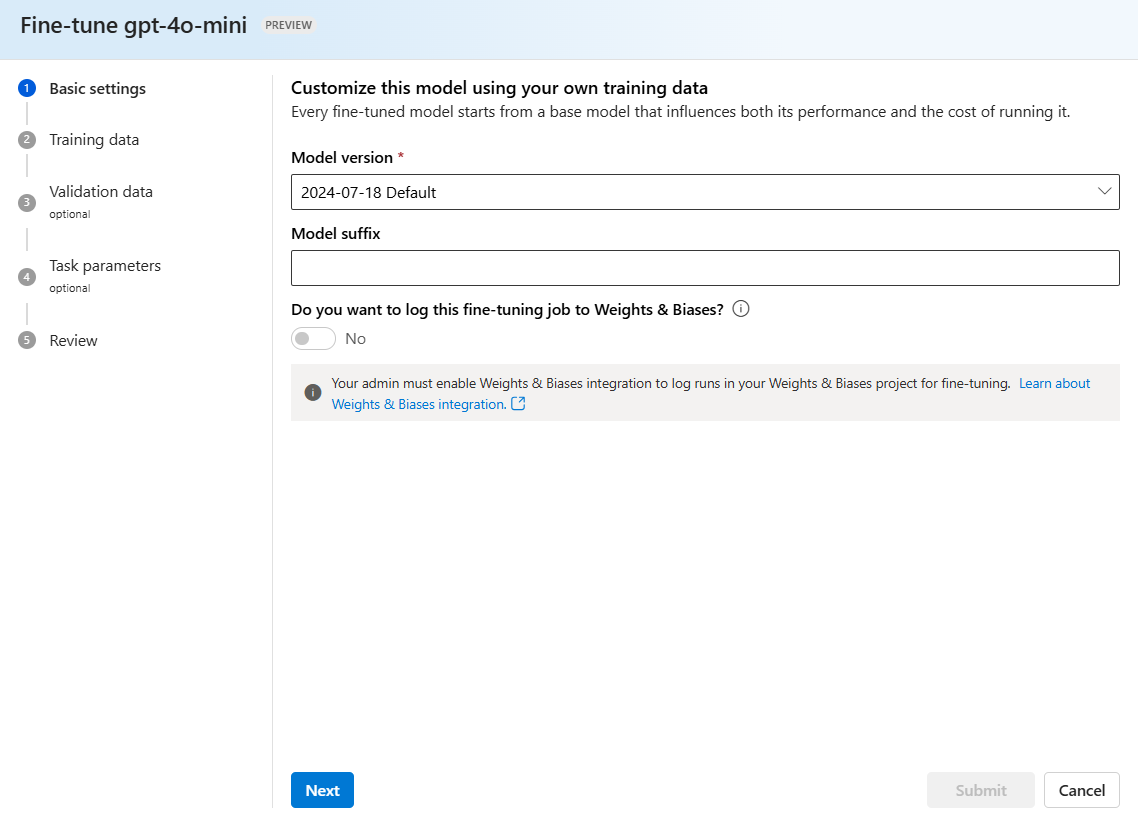
Konfirmasikan versi model mana yang ingin Anda sesuaikan:
File .jsonl dengan nama yang dihasilkan secara acak akan dibuat sebagai himpunan data pelatihan dari penyelesaian tersimpan Anda. Pilih file >Berikutnya.
Nota
File pelatihan distilasi selesai yang tersimpan tidak dapat diakses langsung dan tidak dapat diekspor atau diunduh.
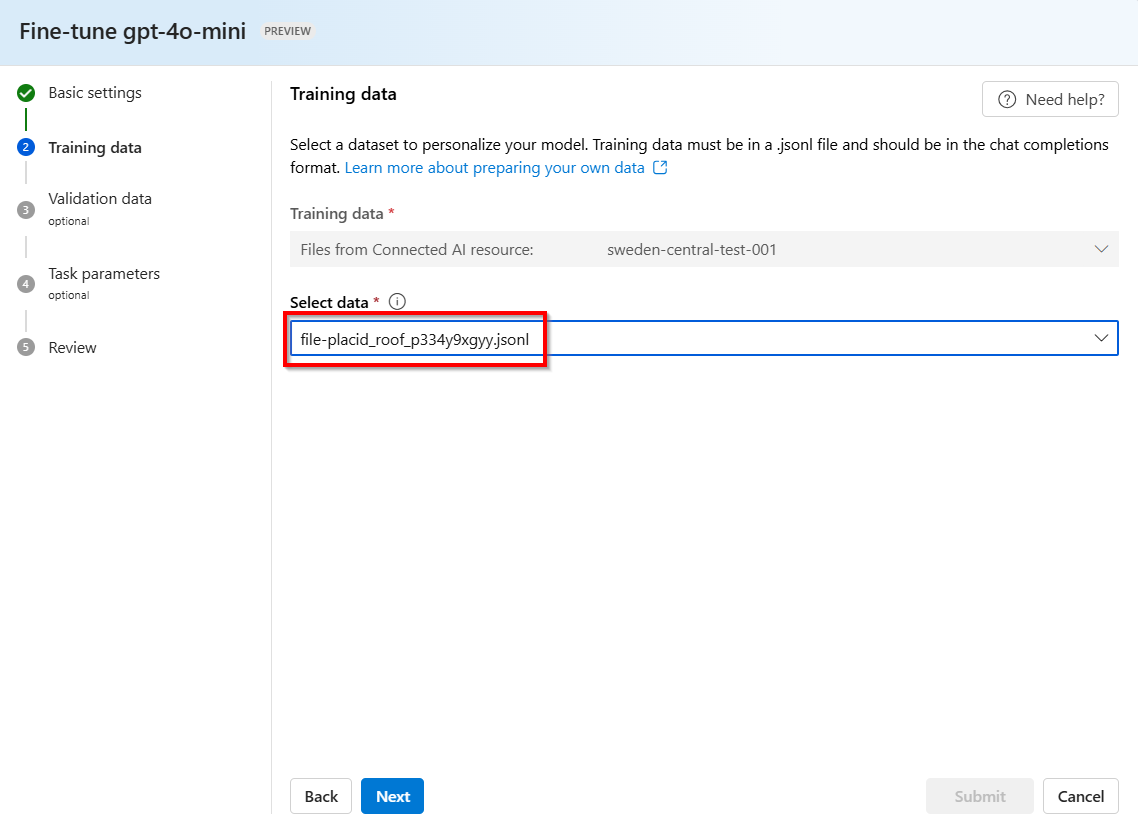
Langkah-langkah lainnya sesuai dengan langkah-langkah penyempurnaan OpenAI Azure umum. Untuk mempelajari lebih lanjut, lihat panduan memulai penyesuaian kami.
Penilaian
Evaluasi model bahasa besar adalah langkah penting dalam mengukur performanya di berbagai tugas dan dimensi. Ini sangat penting untuk model yang disempurnakan, di mana menilai perolehan performa (atau kerugian) dari pelatihan sangat penting. Evaluasi menyeluruh dapat membantu pemahaman Anda tentang bagaimana versi model yang berbeda dapat memengaruhi aplikasi atau skenario Anda.
Penyelesaian tersimpan dapat digunakan sebagai himpunan data untuk menjalankan evaluasi.
Dari panel Stored Completions di portal Foundry gunakan opsi Filter untuk memilih penyelesaian yang Ingin Anda jadikan bagian dari himpunan data evaluasi Anda.
Untuk mengonfigurasi evaluasi, pilih Evaluasi
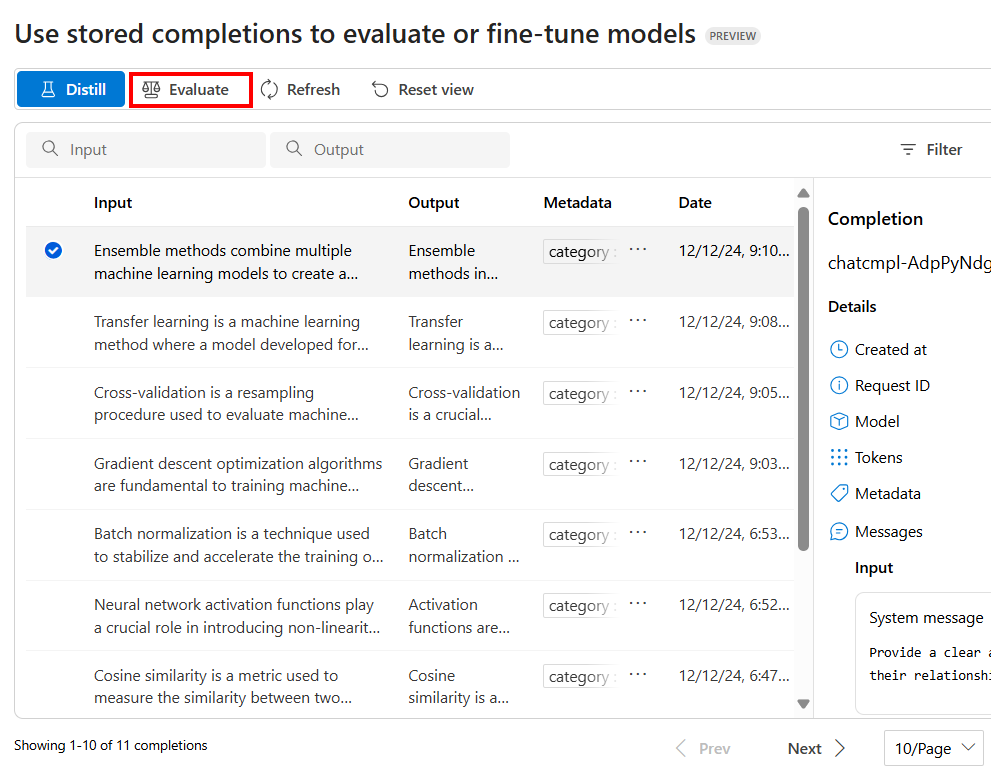
Ini meluncurkan panel Evaluasi dengan file .jsonl yang telah diisi sebelumnya, dengan nama yang dihasilkan secara acak, yang dibuat dari penyelesaian tersimpan Anda sebagai himpunan data evaluasi.
Nota
File data evaluasi penyelesaian tersimpan tidak dapat diakses secara langsung dan tidak dapat diekspor secara eksternal/diunduh.
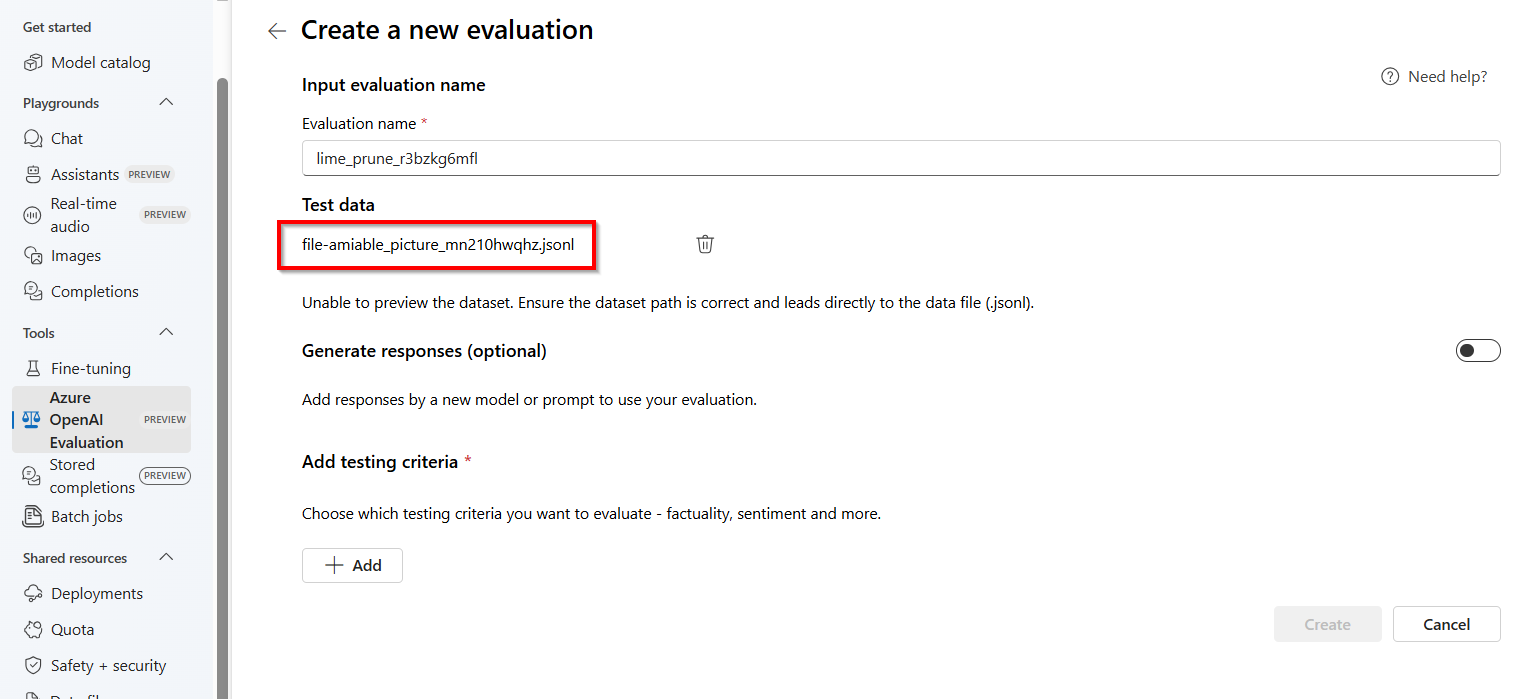
Untuk mempelajari selengkapnya tentang evaluasi, lihat memulai dengan evaluasi
API penyelesaian yang disimpan
Untuk mengakses perintah API komplet yang tersimpan, Anda mungkin perlu meningkatkan versi perpustakaan OpenAI Anda.
pip install --upgrade openai
Daftar penyelesaian yang tersimpan
Parameter tambahan:
-
metadata: Filter berdasarkan pasangan kunci/nilai dalam penyelesaian tersimpan
-
after: Pengidentifikasi untuk pesan selesai terakhir yang disimpan dari permintaan paginasi terakhir kali.
-
limit: Jumlah pesan penyelesaian tersimpan yang dapat diambil.
-
order: Urutan hasil menurut indeks (naik atau menurun).
from openai import OpenAI
from azure.identity import DefaultAzureCredential, get_bearer_token_provider

token_provider = get_bearer_token_provider(
    DefaultAzureCredential(), "https://ai.azure.com/.default"
)

client = OpenAI(
  base_url="https://YOUR-RESOURCE-NAME.openai.azure.com/openai/v1/",
  api_key=token_provider,
)

response = client.chat.completions.list()

print(response.model_dump_json(indent=2))
from openai import OpenAI

client = OpenAI(
  base_url="https://YOUR-RESOURCE-NAME.openai.azure.com/openai/v1/",
  api_key=os.getenv("AZURE_OPENAI_API_KEY"),
)

response = client.chat.completions.list()

print(response.model_dump_json(indent=2))
Microsoft Entra ID
curl https://YOUR-RESOURCE-NAME.openai.azure.com/openai/v1/chat/completions \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $AZURE_OPENAI_AUTH_TOKEN" \
Kunci API
curl https://YOUR-RESOURCE-NAME.openai.azure.com/openai/v1/chat/completions \
  -H "Content-Type: application/json" \
  -H "api-key: $AZURE_OPENAI_API_KEY" \
{
  "data": [
    {
      "id": "chatcmpl-A1bC2dE3fH4iJ5kL6mN7oP8qR9sT0u",
      "choices": [
        {
          "finish_reason": null,
          "index": 0,
          "logprobs": null,
          "message": {
            "content": "Ensemble methods enhance machine learning performance by combining multiple models to create a more robust and accurate predictor. The key techniques include:\n\n1. **Bagging (Bootstrap Aggregating):** This involves training models on random subsets of the data to reduce variance and prevent overfitting. Random Forests, a popular bagging method, build multiple decision trees using random feature subsets, leading to robust predictions.\n\n2. **Boosting:** This sequential approach trains models to correct the errors of their predecessors, thereby focusing on difficult-to-predict data points. Gradient Boosting is a common implementation that sequentially builds decision trees, each improving upon the prediction errors of the previous ones.\n\n3. **Stacking:** This technique uses a meta-model to combine the predictions of multiple base models, leveraging their diverse strengths to enhance overall prediction accuracy.\n\nThe practical implications of ensemble methods include achieving superior model performance compared to single models by capturing various data patterns and reducing overfitting and variance. These methods are widely used in applications where high accuracy and model reliability are critical.",
            "refusal": null,
            "role": "assistant",
            "audio": null,
            "function_call": null,
            "tool_calls": null
          }
        }
      ],
      "created": 1740447656,
      "model": "gpt-4o-2024-08-06",
      "object": null,
      "service_tier": null,
      "system_fingerprint": "fp_b705f0c291",
      "usage": {
        "completion_tokens": 208,
        "prompt_tokens": 157,
        "total_tokens": 365,
        "completion_tokens_details": null,
        "prompt_tokens_details": null
      },
      "request_id": "0000aaaa-11bb-cccc-dd22-eeeeee333333",
      "seed": -430976584126747957,
      "top_p": 1,
      "temperature": 1,
      "presence_penalty": 0,
      "frequency_penalty": 0,
      "metadata": {
        "user": "admin",
        "category": "docs-test"
      }
    }
  ],
  "has_more": false,
  "object": "list",
  "total": 1,
  "first_id": "chatcmpl-A1bC2dE3fH4iJ5kL6mN7oP8qR9sT0u",
  "last_id": "chatcmpl-A1bC2dE3fH4iJ5kL6mN7oP8qR9sT0u"
}
Mendapatkan penyelesaian tersimpan
Dapatkan penyelesaian tersimpan berdasarkan ID.
from openai import OpenAI
from azure.identity import DefaultAzureCredential, get_bearer_token_provider

token_provider = get_bearer_token_provider(
    DefaultAzureCredential(), "https://ai.azure.com/.default"
)

client = OpenAI(
  base_url="https://YOUR-RESOURCE-NAME.openai.azure.com/openai/v1/",
  api_key=token_provider
)

response = client.chat.completions.retrieve("chatcmpl-A1bC2dE3fH4iJ5kL6mN7oP8qR9sT0u")

print(response.model_dump_json(indent=2))
from openai import OpenAI

client = OpenAI(
  base_url="https://YOUR-RESOURCE-NAME.openai.azure.com/openai/v1/",
  api_key=os.getenv("AZURE_OPENAI_API_KEY"),

)

response = client.chat.completions.retrieve("chatcmpl-A1bC2dE3fH4iJ5kL6mN7oP8qR9sT0u")

print(response.model_dump_json(indent=2))
Microsoft Entra ID
curl https://YOUR-RESOURCE-NAME.openai.azure.com/openai/v1/chat/completions/chatcmpl-A1bC2dE3fH4iJ5kL6mN7oP8qR9sT0u \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $AZURE_OPENAI_AUTH_TOKEN" \
Kunci API
curl https://YOUR-RESOURCE-NAME.openai.azure.com/openai/v1/chat/completions/chatcmpl-A1bC2dE3fH4iJ5kL6mN7oP8qR9sT0u \
  -H "Content-Type: application/json" \
  -H "api-key: $AZURE_OPENAI_API_KEY" \
{
  "id": "chatcmpl-A1bC2dE3fH4iJ5kL6mN7oP8qR9sT0u",
  "choices": [
    {
      "finish_reason": null,
      "index": 0,
      "logprobs": null,
      "message": {
        "content": "Ensemble methods enhance machine learning performance by combining multiple models to create a more robust and accurate predictor. The key techniques include:\n\n1. **Bagging (Bootstrap Aggregating):** This involves training models on random subsets of the data to reduce variance and prevent overfitting. Random Forests, a popular bagging method, build multiple decision trees using random feature subsets, leading to robust predictions.\n\n2. **Boosting:** This sequential approach trains models to correct the errors of their predecessors, thereby focusing on difficult-to-predict data points. Gradient Boosting is a common implementation that sequentially builds decision trees, each improving upon the prediction errors of the previous ones.\n\n3. **Stacking:** This technique uses a meta-model to combine the predictions of multiple base models, leveraging their diverse strengths to enhance overall prediction accuracy.\n\nThe practical implications of ensemble methods include achieving superior model performance compared to single models by capturing various data patterns and reducing overfitting and variance. These methods are widely used in applications where high accuracy and model reliability are critical.",
        "refusal": null,
        "role": "assistant",
        "audio": null,
        "function_call": null,
        "tool_calls": null
      }
    }
  ],
  "created": 1740447656,
  "model": "gpt-4o-2024-08-06",
  "object": "chat.completion",
  "service_tier": null,
  "system_fingerprint": "fp_b705f0c291",
  "usage": {
    "completion_tokens": 208,
    "prompt_tokens": 157,
    "total_tokens": 365,
    "completion_tokens_details": null,
    "prompt_tokens_details": null
  },
  "request_id": "0000aaaa-11bb-cccc-dd22-eeeeee333333",
  "seed": -430976584126747957,
  "top_p": 1,
  "temperature": 1,
  "presence_penalty": 0,
  "frequency_penalty": 0,
  "metadata": {
    "user": "admin",
    "category": "docs-test"
  }
}
Mendapatkan pesan penyelesaian obrolan tersimpan
Parameter tambahan:
-
after: Pengidentifikasi untuk pesan selesai terakhir yang disimpan dari permintaan paginasi terakhir kali.
-
limit: Jumlah pesan penyelesaian tersimpan yang dapat diambil.
-
order: Urutan hasil menurut indeks (naik atau menurun).
from openai import OpenAI
from azure.identity import DefaultAzureCredential, get_bearer_token_provider

token_provider = get_bearer_token_provider(
    DefaultAzureCredential(), "https://ai.azure.com/.default"
)

client = OpenAI(
  base_url="https://YOUR-RESOURCE-NAME.openai.azure.com/openai/v1/",
  api_key=token_provider,
)

response = client.chat.completions.messages.list("chatcmpl-A1bC2dE3fH4iJ5kL6mN7oP8qR9sT0u", limit=2)

print(response.model_dump_json(indent=2))
from openai import OpenAI

client = OpenAI(
  base_url="https://YOUR-RESOURCE-NAME.openai.azure.com/openai/v1/",
  api_key=os.getenv("AZURE_OPENAI_API_KEY"),
)

response = client.chat.completions.messages.list("chatcmpl-A1bC2dE3fH4iJ5kL6mN7oP8qR9sT0u", limit=2)

print(response.model_dump_json(indent=2))
Microsoft Entra ID
curl https://YOUR-RESOURCE-NAME.openai.azure.com/openai/v1/chat/completions/chatcmpl-A1bC2dE3fH4iJ5kL6mN7oP8qR9sT0u/messages \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $AZURE_OPENAI_AUTH_TOKEN" \
Kunci API
curl https://YOUR-RESOURCE-NAME.openai.azure.com/openai/v1/chat/completions/chatcmpl-A1bC2dE3fH4iJ5kL6mN7oP8qR9sT0u/messages \
  -H "Content-Type: application/json" \
  -H "api-key: $AZURE_OPENAI_API_KEY" \
{
  "data": [
    {
      "content": "Provide a clear and concise summary of the technical content, highlighting key concepts and their relationships. Focus on the main ideas and practical implications.",
      "refusal": null,
      "role": "system",
      "audio": null,
      "function_call": null,
      "tool_calls": null,
      "id": "chatcmpl-A1bC2dE3fH4iJ5kL6mN7oP8qR9sT0u-0"
    },
    {
      "content": "Ensemble methods combine multiple machine learning models to create a more robust and accurate predictor. Common techniques include bagging (training models on random subsets of data), boosting (sequentially training models to correct previous errors), and stacking (using a meta-model to combine base model predictions). Random Forests, a popular bagging method, create multiple decision trees using random feature subsets. Gradient Boosting builds trees sequentially, with each tree focusing on correcting the errors of previous trees. These methods often achieve better performance than single models by reducing overfitting and variance while capturing different aspects of the data.",
      "refusal": null,
      "role": "user",
      "audio": null,
      "function_call": null,
      "tool_calls": null,
      "id": "chatcmpl-A1bC2dE3fH4iJ5kL6mN7oP8qR9sT0u-1"
    }
  ],
  "has_more": false,
  "object": "list",
  "total": 2,
  "first_id": "chatcmpl-A1bC2dE3fH4iJ5kL6mN7oP8qR9sT0u-0",
  "last_id": "chatcmpl-A1bC2dE3fH4iJ5kL6mN7oP8qR9sT0u-1"
}
Memperbarui hasil obrolan yang telah disimpan
Tambahkan pasangan kunci dan nilai metadata ke dalam penyelesaian yang sudah disimpan.
from openai import OpenAI
from azure.identity import DefaultAzureCredential, get_bearer_token_provider

token_provider = get_bearer_token_provider(
    DefaultAzureCredential(), "https://ai.azure.com/.default"
)

client = AzureOpenAI(
  base_url="https://YOUR-RESOURCE-NAME.openai.azure.com/openai/v1/",
  api_key=token_provider,
)

response = client.chat.completions.update(
    "chatcmpl-C2dE3fH4iJ5kL6mN7oP8qR9sT0uV1w",
    metadata={"fizz": "buzz"}
)

print(response.model_dump_json(indent=2))
from openai import OpenAI

client = OpenAI(
  base_url="https://YOUR-RESOURCE-NAME.openai.azure.com/openai/v1/",
  api_key=os.getenv("AZURE_OPENAI_API_KEY")
)

response = client.chat.completions.update(
    "chatcmpl-C2dE3fH4iJ5kL6mN7oP8qR9sT0uV1w",
    metadata={"fizz": "buzz"}
)

print(response.model_dump_json(indent=2))
Microsoft Entra ID
curl -X https://YOUR-RESOURCE-NAME.openai.azure.com/openai/v1/chat/completions/chatcmpl-A1bC2dE3fH4iJ5kL6mN7oP8qR9sT0u \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $AZURE_OPENAI_AUTH_TOKEN"
  -d '{
    "metadata": {
      "fizz": "buzz"
    }
  }'
Kunci API
curl -X https://YOUR-RESOURCE-NAME.openai.azure.com/openai/v1/chat/completions/chatcmpl-A1bC2dE3fH4iJ5kL6mN7oP8qR9sT0u \
  -H "Content-Type: application/json" \
  -H "api-key: $AZURE_OPENAI_API_KEY"
  -d '{
    "metadata": {
      "fizz": "buzz"
    }
  }'
  "id": "chatcmpl-A1bC2dE3fH4iJ5kL6mN7oP8qR9sT0u",
  "choices": [
    {
      "finish_reason": null,
      "index": 0,
      "logprobs": null,
      "message": {
        "content": "Ensemble methods enhance machine learning performance by combining multiple models to create a more robust and accurate predictor. The key techniques include:\n\n1. **Bagging (Bootstrap Aggregating):** This involves training models on random subsets of the data to reduce variance and prevent overfitting. Random Forests, a popular bagging method, build multiple decision trees using random feature subsets, leading to robust predictions.\n\n2. **Boosting:** This sequential approach trains models to correct the errors of their predecessors, thereby focusing on difficult-to-predict data points. Gradient Boosting is a common implementation that sequentially builds decision trees, each improving upon the prediction errors of the previous ones.\n\n3. **Stacking:** This technique uses a meta-model to combine the predictions of multiple base models, leveraging their diverse strengths to enhance overall prediction accuracy.\n\nThe practical implications of ensemble methods include achieving superior model performance compared to single models by capturing various data patterns and reducing overfitting and variance. These methods are widely used in applications where high accuracy and model reliability are critical.",
        "refusal": null,
        "role": "assistant",
        "audio": null,
        "function_call": null,
        "tool_calls": null
      }
    }
  ],
  "created": 1740447656,
  "model": "gpt-4o-2024-08-06",
  "object": "chat.completion",
  "service_tier": null,
  "system_fingerprint": "fp_b705f0c291",
  "usage": {
    "completion_tokens": 208,
    "prompt_tokens": 157,
    "total_tokens": 365,
    "completion_tokens_details": null,
    "prompt_tokens_details": null
  },
  "request_id": "0000aaaa-11bb-cccc-dd22-eeeeee333333",
  "seed": -430976584126747957,
  "top_p": 1,
  "temperature": 1,
  "presence_penalty": 0,
  "frequency_penalty": 0,
  "metadata": {
    "user": "admin",
    "category": "docs-test"
    "fizz": "buzz"
  }
}
Menghapus hasil akhir obrolan yang tersimpan
Hapus penyelesaian yang disimpan berdasarkan ID penyelesaian.
Microsoft Entra ID
from openai import OpenAI
from azure.identity import DefaultAzureCredential, get_bearer_token_provider

token_provider = get_bearer_token_provider(
    DefaultAzureCredential(), "https://ai.azure.com/.default"
)

client = OpenAI(
  base_url="https://YOUR-RESOURCE-NAME.openai.azure.com/openai/v1/",
  api_key=token_provider
)

response = client.chat.completions.delete("chatcmpl-A1bC2dE3fH4iJ5kL6mN7oP8qR9sT0u")

print(response.model_dump_json(indent=2))
from openai import OpenAI

client = OpenAI(
  base_url="https://YOUR-RESOURCE-NAME.openai.azure.com/openai/v1/",
  api_key=os.getenv("AZURE_OPENAI_API_KEY"),
)

response = client.chat.completions.delete("chatcmpl-A1bC2dE3fH4iJ5kL6mN7oP8qR9sT0u")

print(response.model_dump_json(indent=2))
curl -X DELETE -D - https://YOUR-RESOURCE-NAME.openai.azure.com/openai/v1/chat/completions/chatcmpl-A1bC2dE3fH4iJ5kL6mN7oP8qR9sT0u \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $AZURE_OPENAI_AUTH_TOKEN"
Kunci API
curl -X DELETE -D - https://YOUR-RESOURCE-NAME.openai.azure.com/openai/v1/chat/completions/chatcmpl-A1bC2dE3fH4iJ5kL6mN7oP8qR9sT0u \
  -H "Content-Type: application/json" \
  -H "api-key: $AZURE_OPENAI_API_KEY"
"id"• "chatcmp1-A1bC2dE3fH4iJ5kL6mN7oP8qR9sT0u",
"deleted": true,
"object": "chat. completion. deleted"
Troubleshooting
Apakah saya memerlukan izin khusus untuk menggunakan penyelesaian yang disimpan?
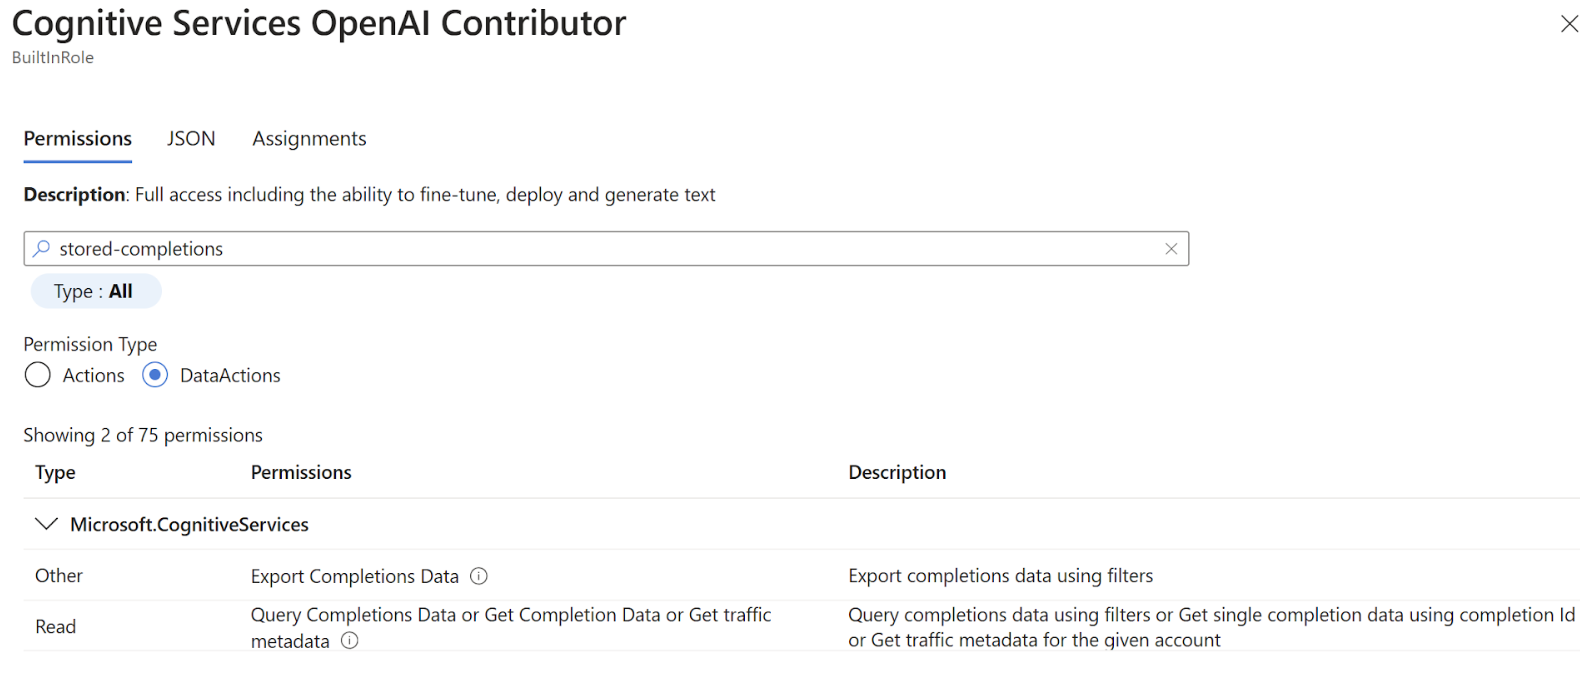
Akses penyelesaian tersimpan dikontrol melalui dua DataActions:
Microsoft.CognitiveServices/accounts/OpenAI/stored-completions/readMicrosoft.CognitiveServices/accounts/OpenAI/stored-completions/action
Secara default peran Foundry User memiliki akses ke kedua izin ini:
Penting
Peran Foundry RBAC baru-baru ini diubah namanya.
Pengguna Foundry, Pemilik Foundry, Pemilik Akun Foundry, dan Manajer Proyek Foundry sebelumnya bernama Pengguna Azure AI, Pemilik Azure AI, Pemilik Akun Azure AI, dan Manajer Proyek Azure AI. Anda mungkin masih melihat nama sebelumnya di beberapa tempat saat penggantian nama diluncurkan. ID peran dan izin inti tidak berubah oleh penggantian nama.
Bagaimana cara saya menghapus data yang tersimpan?
Data dapat dihapus dengan menghapus sumber daya OpenAI Azure terkait. Jika Anda hanya ingin menghapus data penyelesaian tersimpan, Anda harus membuka kasus dengan layanan pelanggan.
Berapa banyak data penyelesaian yang dapat saya simpan?
Anda dapat menyimpan data maksimum 10 GB.
Dapatkah saya mencegah penyelesaian tersimpan di proyek saya?
Pengguna sumber daya OpenAI Azure dapat menonaktifkan penyelesaian tersimpan dalam portal Azure. Dalam sumber daya OpenAI Azure, navigasikan ke panel Penyelesaian Tersimpan dalam tampilan Manajemen Sumber Daya. Alihkan kontrol Penyelesaian Tersimpan ke Dinonaktifkan dan klik Simpan.
Pengguna sumber daya Foundry harus membuka kasus dengan dukungan pelanggan untuk menonaktifkan Penyelesaian Tersimpan di tingkat langganan Azure.
TypeError: Completions.create() menerima argumen 'store' yang tidak terduga
Kesalahan ini terjadi saat Anda menjalankan versi lama pustaka klien OpenAI yang mendahului fitur penyelesaian tersimpan yang dirilis. Jalankan pip install openai --upgrade.
