요약은 사용자가 읽기에 너무 오래 걸리는 콘텐츠를 압축합니다. 이 서비스는 일반 텍스트, 대화 및 네이티브 문서라는 세 가지 유형의 장르에 대한 요약 솔루션을 제공합니다. 요약할 콘텐츠 형식과 일치하는 탭을 선택합니다.
텍스트 요약은 사용자가 읽기에 너무 오래 걸리는 콘텐츠를 줄입니다. 추출 및 추상 요약 모두 문서, 논문 또는 문서를 핵심 문장으로 압축합니다.
추출 요약은 원본 콘텐츠 내에서 가장 중요하거나 관련성 있는 정보를 집합적으로 나타내는 문장을 추출하여 요약을 생성합니다.
추상적 요약: 주요 아이디어를 캡처하는 문서에서 요약된 문장을 생성하여 요약을 생성합니다.
쿼리 중심 요약: 요약할 때 쿼리를 사용할 수 있습니다.
이러한 각 기능은 지정된 경우 관심 있는 특정 항목에 대해 요약할 수 있습니다.
이 서비스는 API에서 사용하는 AI 모델을 제공합니다. 분석을 위해 콘텐츠를 전송하기만 하면 됩니다.
더 쉽게 탐색할 수 있도록 각 서비스에 해당하는 섹션에 대한 링크는 다음과 같습니다.
Features
추출 요약 API는 자연어 처리 기술을 사용하여 구조화되지 않은 텍스트 문서에서 핵심 문장을 찾습니다. 이러한 문장은 문서의 주요 개념을 전체적으로 전달합니다.
추출 요약은 원래 문서에서 추출된 문장 및 해당 위치와 함께 시스템 응답의 일부로 순위 점수를 반환합니다. 순위 점수는 문장이 문서의 주요 개념과 얼마나 관련이 있는지를 나타냅니다. 모델은 각 문장에 대해 0~1(포함) 사이의 점수를 제공하고 요청당 점수가 가장 높은 문장을 반환합니다. 예를 들어, 3개 문장 요약을 요청하는 경우 서비스는 점수가 가장 높은 3개 문장을 반환합니다.
Foundry Tools의 Azure Language에 있는 또 다른 기능인 핵심 구문 추출은 주요 정보를 추출할 수 있습니다. 핵심 구 추출과 추출 요약 중에서 결정할 때 다음 요소를 고려합니다.
- 핵심 구 추출은 구를 반환하는 반면, 추출 요약은 문장을 반환합니다.
- 추출 요약은 순위 점수와 함께 문장을 반환하며 요청당 상위 순위 문장이 반환됩니다.
- 추출 요약은 다음 위치 정보도 반환합니다.
- 오프셋: 추출된 각 문장의 시작 위치입니다.
- 길이: 추출된 각 문장의 길이입니다.
데이터 처리 방법 결정(선택 사항)
데이터 제출
문서를 텍스트 문자열로 API에 제출합니다. API는 요청을 받으면 분석을 수행합니다. API는 비동기이므로 API 요청을 보내고 결과를 받는 사이에 지연이 있을 수 있습니다.
이 기능을 사용하면 요청이 수집된 시점부터 24시간 동안 API 결과를 사용할 수 있으며 응답은 이 가용성을 나타냅니다. 이 기간이 지나면 결과가 제거되고 더 이상 검색할 수 없습니다.
텍스트 요약 결과 가져오기
언어 감지에서 결과를 가져올 때 애플리케이션에 결과를 스트리밍하거나 로컬 시스템의 파일에 출력을 저장할 수 있습니다.
다음 예제에서는 요약을 위해 제출할 수 있는 콘텐츠를 보여줍니다. 콘텐츠는 Microsoft 블로그 문서 통합 AI에 대한 전체적인 표현에서 추출됩니다. 이 문서는 예제일 뿐입니다. API는 더 긴 입력 텍스트를 허용할 수 있습니다. 자세한 내용은 데이터 및 서비스 제한을참조하세요.
"Microsoft에서는 학습과 이해에 대해 보다 전체적이고 인간 중심적인 접근 방식을 취함으로써 기존 기술을 넘어 AI를 발전시키기 위한 노력을 기울이고 있습니다. Foundry Tools의 최고 기술 책임자로서 저는 놀라운 과학자 및 엔지니어 팀과 협력하여 이 탐구를 현실로 바꾸고 있습니다. 제 역할에서 저는 인간 인지의 세 가지 특성, 즉 단일 언어 텍스트(X), 청각 또는 시각 감각 신호(Y) 및 다국어(Z) 간의 관계를 보는 고유한 관점을 활용합니다. 세 가지가 모두 교차하는 지점에는 그림 1에 나와 있는 바와 같이 XYZ-코드라고 하는 매직이 있습니다. 인간보다 더 잘 말하고, 듣고, 보고, 이해할 수 있는 강력한 AI를 만드는 공동 표현입니다. XYZ-코드를 통해 장기적인 비전(도메인 간 전이 학습, 형식 및 언어 확장)을 수행할 수 있습니다. 목표는 오늘날 인간이 하는 것처럼 광범위한 다운스트림 AI 작업을 지원하기 위해 표현을 공동으로 학습할 수 있는 미리 학습된 모델을 보유하는 것입니다. 지난 5년 동안 우리는 대화형 음성 인식, 기계 번역, 대화형 질문 답변, 기계 읽기 이해 및 이미지 캡션 분야에서 벤치마크에서 인간의 성과를 달성했습니다. 이 다섯 가지 돌파구는 AI 기능의 도약을 위한 우리의 더 야심찬 포부에 대한 강력한 신호가 되었으며, 인간이 배우고 이해하는 방식에 더 가까운 다중 감각 및 다국어 학습을 달성하기 위한 방향을 제시했습니다. 저는 다운스트림 AI 작업에서 외부 기술 자료를 기반으로 한 경우에는 공동 XYZ- 코드가 이러한 열망의 기본 구성 요소라고 생각합니다."
텍스트 요약 API 요청은 API 백 엔드에 대한 작업을 만들어 요청을 수신하면 처리됩니다. 작업이 성공하면 API의 출력이 반환됩니다. 출력은 24시간 동안 검색에 사용할 수 있습니다. 이 시간이 지나면 출력이 제거됩니다. 다국어 지원 및 emoji 지원으로 인해 응답에 텍스트 오프셋이 포함될 수 있습니다. 자세한 내용은 오프셋을 처리하는 방법을참조하세요.
앞의 예제를 사용하는 경우 API는 다음과 같은 요약된 문장을 반환할 수 있습니다.
추출 요약:
- "Microsoft 학습과 이해에 보다 전체적이고 인간 중심의 접근 방식을 취하여 기존 기술을 넘어 AI를 발전시키기 위한 탐구를 하고 있습니다."
- "XYZ-코드를 통해 장기적인 비전(도메인 간 전이 학습, 형식 및 언어 확장)을 수행할 수 있습니다."
- "목표는 오늘날 인간이 하는 것처럼 광범위한 다운스트림 AI 작업을 지원하기 위해 표현을 공동으로 학습할 수 있는 미리 학습된 모델을 보유하는 것입니다."
추상 요약:
- "Microsoft는 학습 및 이해에 대해 보다 총체적이고 인간 중심적인 방식을 취하고 있습니다. XYZ-코드를 통해 장기적인 비전(도메인 간 전이 학습, 형식 및 언어 확장)을 수행할 수 있습니다. 지난 5년 동안 우리는 주요 벤치마크에서 인간의 성과를 달성했습니다."
텍스트 추출 요약을 사용하여 문서, 논문 또는 문서의 요약을 가져올 수 있습니다. 예를 보려면 빠른 시작 문서을 참조하세요.
sentenceCount 매개변수를 사용하여 반환할 문장 수를 지정하며, 기본값은 3입니다. 범위는 1~20 사이입니다.
매개 변수를 sortby 사용하여 추출된 문장이 반환 Offset 되는 순서를 지정하거나 Rank기본값으로 Offset 지정합니다.
| 매개 변수 값 |
Description |
| Rank |
서비스에서 결정한 대로 입력 문서와의 관련성에 따라 문장을 정렬합니다. |
| Offset |
입력 문서에 문장이 나타나는 원래 순서를 유지합니다. |
텍스트 추상 요약 시도
다음 예제에서는 텍스트 추상화 요약을 시작하는 방법을 보여줍니다.
- 다음 명령을 텍스트 편집기에 복사합니다. BASH 예에서는
\ 줄 연속 문자를 사용합니다. 콘솔 또는 터미널에서 다른 줄 연속 문자를 사용하는 경우 해당 문자를 대신 사용하세요.
curl -i -X POST https://<your-language-resource-endpoint>/language/analyze-text/jobs?api-version=2023-04-01 \
-H "Content-Type: application/json" \
-H "Ocp-Apim-Subscription-Key: <your-language-resource-key>" \
-d \
'
{
  "displayName": "Text Abstractive Summarization Task Example",
  "analysisInput": {
    "documents": [
      {
        "id": "1",
        "language": "en",
        "text": "At Microsoft, we have been on a quest to advance AI beyond existing techniques, by taking a more holistic, human-centric approach to learning and understanding. As Chief Technology Officer of Foundry Tools, I have been working with a team of amazing scientists and engineers to turn this quest into a reality. In my role, I enjoy a unique perspective in viewing the relationship among three attributes of human cognition: monolingual text (X), audio or visual sensory signals, (Y) and multilingual (Z). At the intersection of all three, there's magic—what we call XYZ-code as illustrated in Figure 1—a joint representation to create more powerful AI that can speak, hear, see, and understand humans better. We believe XYZ-code enables us to fulfill our long-term vision: cross-domain transfer learning, spanning modalities and languages. The goal is to have pretrained models that can jointly learn representations to support a broad range of downstream AI tasks, much in the way humans do today. Over the past five years, we have achieved human performance on benchmarks in conversational speech recognition, machine translation, conversational question answering, machine reading comprehension, and image captioning. These five breakthroughs provided us with strong signals toward our more ambitious aspiration to produce a leap in AI capabilities, achieving multi-sensory and multilingual learning that is closer in line with how humans learn and understand. I believe the joint XYZ-code is a foundational component of this aspiration, if grounded with external knowledge sources in the downstream AI tasks."
      }
    ]
  },
  "tasks": [
    {
      "kind": "AbstractiveSummarization",
      "taskName": "Text Abstractive Summarization Task 1",
    }
  ]
}
'
필요한 경우 명령에서 다음 내용을 변경합니다.
-
your-language-resource-key 값을 키로 바꿉니다.
- 요청 URL
your-language-resource-endpoint의 첫 번째 부분을 고유한 엔드포인트 URL로 바꿉니다.
명령 프롬프트 창(예: BASH)을 엽니다.
텍스트 편집기에서 명령 프롬프트 창으로 명령을 붙여넣은 후 명령을 실행합니다.
응답 헤더에서 operation-location을 가져옵니다. 값은 다음 URL과 유사합니다.
https://<your-language-resource-endpoint>/language/analyze-text/jobs/12345678-1234-1234-1234-12345678?api-version=2022-10-01-preview
- 요청 결과를 가져오려면 다음 cURL 명령을 사용합니다.
<my-job-id>을(를) 이전 operation-location 응답 헤더에서 받은 숫자 ID 값으로 반드시 교체해야 합니다.
curl -X GET https://<your-language-resource-endpoint>/language/analyze-text/jobs/<my-job-id>?api-version=2022-10-01-preview \
-H "Content-Type: application/json" \
-H "Ocp-Apim-Subscription-Key: <your-language-resource-key>"
추상 텍스트 요약 예제 JSON 응답
{
    "jobId": "cd6418fe-db86-4350-aec1-f0d7c91442a6",
    "lastUpdateDateTime": "2022-09-08T16:45:14Z",
    "createdDateTime": "2022-09-08T16:44:53Z",
    "expirationDateTime": "2022-09-09T16:44:53Z",
    "status": "succeeded",
    "errors": [],
    "displayName": "Text Abstractive Summarization Task Example",
    "tasks": {
        "completed": 1,
        "failed": 0,
        "inProgress": 0,
        "total": 1,
        "items": [
            {
                "kind": "AbstractiveSummarizationLROResults",
                "taskName": "Text Abstractive Summarization Task 1",
                "lastUpdateDateTime": "2022-09-08T16:45:14.0717206Z",
                "status": "succeeded",
                "results": {
                    "documents": [
                        {
                            "summaries": [
                                {
                                    "text": "Microsoft is taking a more holistic, human-centric approach to AI. We've developed a joint representation to create more powerful AI that can speak, hear, see, and understand humans better. We've achieved human performance on benchmarks in conversational speech recognition, machine translation, ...... and image captions.",
                                    "contexts": [
                                        {
                                            "offset": 0,
                                            "length": 247
                                        }
                                    ]
                                }
                            ],
                            "id": "1"
                        }
                    ],
                    "errors": [],
                    "modelVersion": "latest"
                }
            }
        ]
    }
}
| 매개 변수 |
Description |
-X POST <endpoint> |
API에 액세스하기 위한 엔드포인트를 지정합니다. |
-H Content-Type: application/json |
JSON 데이터를 보내기 위한 콘텐츠 형식입니다. |
-H "Ocp-Apim-Subscription-Key:<key> |
API에 액세스하기 위한 키를 지정합니다. |
-d <documents> |
보낼 문서가 포함된 JSON입니다. |
다음 cURL 명령은 BASH 셸에서 실행됩니다. 사용자 고유의 리소스 이름, 리소스 키 및 JSON 값을 사용하여 이 명령을 편집합니다.
쿼리 기반 요약
쿼리 기반 텍스트 요약 API는 기존 텍스트 요약 API의 확장입니다.
가장 큰 차이점은 요청 본문(querytasks>parameters> 아래)의 새 query 필드입니다.
Tip
쿼리 기반 요약에는 사용 중인 쿼리 기반 요약 유형에 따라 길이 컨트롤의 사용률이 몇 가지 구별됩니다.
- 쿼리 기반 추출 요약은 길이를 지정하여 길이 제어를 지원합니다
sentenceCount.
- 쿼리 기반 추상적 요약은 길이 제어를 지원하지 않습니다.
예제 요청은 다음과 같습니다.
curl -i -X POST https://<your-language-resource-endpoint>/language/analyze-text/jobs?api-version=2023-11-15-preview \
-H "Content-Type: application/json" \
-H "Ocp-Apim-Subscription-Key: <your-language-resource-key>" \
-d \
'
{
  "displayName": "Text Extractive Summarization Task Example",
  "analysisInput": {
    "documents": [
      {
        "id": "1",
        "language": "en",
        "text": "At Microsoft, we have been on a quest to advance AI beyond existing techniques, by taking a more holistic, human-centric approach to learning and understanding. As Chief Technology Officer of Foundry Tools, I have been working with a team of amazing scientists and engineers to turn this quest into a reality. In my role, I enjoy a unique perspective in viewing the relationship among three attributes of human cognition: monolingual text (X), audio or visual sensory signals, (Y) and multilingual (Z). At the intersection of all three, there's magic—what we call XYZ-code as illustrated in Figure 1—a joint representation to create more powerful AI that can speak, hear, see, and understand humans better. We believe XYZ-code enables us to fulfill our long-term vision: cross-domain transfer learning, spanning modalities and languages. The goal is to have pretrained models that can jointly learn representations to support a broad range of downstream AI tasks, much in the way humans do today. Over the past five years, we have achieved human performance on benchmarks in conversational speech recognition, machine translation, conversational question answering, machine reading comprehension, and image captioning. These five breakthroughs provided us with strong signals toward our more ambitious aspiration to produce a leap in AI capabilities, achieving multi-sensory and multilingual learning that is closer in line with how humans learn and understand. I believe the joint XYZ-code is a foundational component of this aspiration, if grounded with external knowledge sources in the downstream AI tasks."
      }
    ]
  },
"tasks": [
    {
      "kind": "AbstractiveSummarization",
      "taskName": "Query-based Abstractive Summarization",
      "parameters": {
          "query": "XYZ-code",
          "summaryLength": "short"
      }
    },    {
      "kind": "ExtractiveSummarization",
      "taskName": "Query_based Extractive Summarization",
      "parameters": {
          "query": "XYZ-code"
      }
    }
  ]
}
'
요약 길이 컨트롤
추출 요약에서 summaryLength 매개 변수 사용
summaryLength를 지정하지 않으면 모델이 요약 길이를 결정합니다.
summaryLength 매개 변수의 경우 다음 세 가지 값이 허용됩니다.
-
oneSentence: 약 80개의 토큰을 사용하여 대부분 하나의 문장에 대한 요약을 생성합니다.
-
short: 약 120개의 토큰을 사용하여 대부분 2~3개의 문장에 대한 요약을 생성합니다.
-
medium: 약 170개의 토큰을 사용하여 대부분 4~6개의 문장에 대한 요약을 생성합니다.
-
long: 토큰이 약 210개인 7개 이상의 문장에 대한 요약을 생성합니다.
예제 요청은 다음과 같습니다.
curl -i -X POST https://<your-language-resource-endpoint>/language/analyze-text/jobs?api-version=2023-04-01 \
-H "Content-Type: application/json" \
-H "Ocp-Apim-Subscription-Key: <your-language-resource-key>" \
-d \
'
{
  "displayName": "Text Abstractive Summarization Task Example",
  "analysisInput": {
    "documents": [
      {
        "id": "1",
        "language": "en",
        "text": "At Microsoft, we have been on a quest to advance AI beyond existing techniques, by taking a more holistic, human-centric approach to learning and understanding. As Chief Technology Officer of Foundry Tools, I have been working with a team of amazing scientists and engineers to turn this quest into a reality. In my role, I enjoy a unique perspective in viewing the relationship among three attributes of human cognition: monolingual text (X), audio or visual sensory signals, (Y) and multilingual (Z). At the intersection of all three, there's magic—what we call XYZ-code as illustrated in Figure 1—a joint representation to create more powerful AI that can speak, hear, see, and understand humans better. We believe XYZ-code enables us to fulfill our long-term vision: cross-domain transfer learning, spanning modalities and languages. The goal is to have pretrained models that can jointly learn representations to support a broad range of downstream AI tasks, much in the way humans do today. Over the past five years, we have achieved human performance on benchmarks in conversational speech recognition, machine translation, conversational question answering, machine reading comprehension, and image captioning. These five breakthroughs provided us with strong signals toward our more ambitious aspiration to produce a leap in AI capabilities, achieving multi-sensory and multilingual learning that is closer in line with how humans learn and understand. I believe the joint XYZ-code is a foundational component of this aspiration, if grounded with external knowledge sources in the downstream AI tasks."
      }
    ]
  },
  "tasks": [
    {
      "kind": "AbstractiveSummarization",
      "taskName": "Length controlled Abstractive Summarization",
          "parameters": {
          "summaryLength": "short"
      }
    }
  ]
}
'
매개 변수의 sentenceCount 경우 1에서 20까지의 값을 입력하여 원하는 출력 문장 수를 나타냅니다.
예제 요청은 다음과 같습니다.
curl -i -X POST https://<your-language-resource-endpoint>/language/analyze-text/jobs?api-version=2023-11-15-preview \
-H "Content-Type: application/json" \
-H "Ocp-Apim-Subscription-Key: <your-language-resource-key>" \
-d \
'
{
  "displayName": "Text Extractive Summarization Task Example",
  "analysisInput": {
    "documents": [
      {
        "id": "1",
        "language": "en",
        "text": "At Microsoft, we have been on a quest to advance AI beyond existing techniques, by taking a more holistic, human-centric approach to learning and understanding. As Chief Technology Officer of Foundry Tools, I have been working with a team of amazing scientists and engineers to turn this quest into a reality. In my role, I enjoy a unique perspective in viewing the relationship among three attributes of human cognition: monolingual text (X), audio or visual sensory signals, (Y) and multilingual (Z). At the intersection of all three, there's magic—what we call XYZ-code as illustrated in Figure 1—a joint representation to create more powerful AI that can speak, hear, see, and understand humans better. We believe XYZ-code enables us to fulfill our long-term vision: cross-domain transfer learning, spanning modalities and languages. The goal is to have pretrained models that can jointly learn representations to support a broad range of downstream AI tasks, much in the way humans do today. Over the past five years, we have achieved human performance on benchmarks in conversational speech recognition, machine translation, conversational question answering, machine reading comprehension, and image captioning. These five breakthroughs provided us with strong signals toward our more ambitious aspiration to produce a leap in AI capabilities, achieving multi-sensory and multilingual learning that is closer in line with how humans learn and understand. I believe the joint XYZ-code is a foundational component of this aspiration, if grounded with external knowledge sources in the downstream AI tasks."
      }
    ]
  },
"tasks": [
    {
      "kind": "ExtractiveSummarization",
      "taskName": "Length controlled Extractive Summarization",
      "parameters": {
          "sentenceCount": "5"
      }
    }
  ]
}
'
서비스 및 데이터 제한
분 및 초 단위로 보낼 수 있는 요청의 크기와 수에 대한 자세한 내용은 서비스 제한 문서를 참조하세요.
Important
미리 보기 지역인 스웨덴 중부에서는 GPT 모델을 기준으로 계속 진화하고 있는 최신 LLM 미세 조정 기술을 선보입니다. 스웨덴 중부 지역의 언어 리소스를 사용해 보실 수 있습니다. 환영합니다.
대화 요약은 다음을 통해서만 사용할 수 있습니다.
대화 요약 양상
장 제목 및 설명(일반 대화) 은 대화를 챕터 제목으로 요약하고 대화 내용 요약을 제공합니다. 이 요약 양상은 여러 당사자와의 대화에서 작동합니다.
문제 및 해결 방법(콜 센터 중심) 은 고객과 고객 서비스 에이전트 간의 텍스트 채팅 로그를 요약합니다. 이 기능은 두 당사자 간에 발생하는 이러한 로그에 있는 문제 및 해결을 모두 제공합니다.
내러티브 는 대화의 이야기를 요약합니다.
긴 모임 또는 대화를 간결한 한 단락 요약으로 요약하여 간략한 개요를 제공합니다.
후속 작업은 회의 중에 발생하는 실행 항목과 작업을 요약합니다.
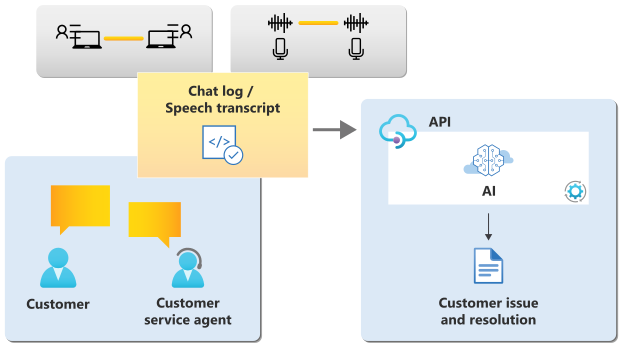
이 서비스는 API에서 사용하는 AI 모델을 제공합니다. 분석을 위해 콘텐츠를 전송하기만 하면 됩니다.
더 쉽게 탐색할 수 있도록 각 서비스에 해당하는 섹션에 대한 링크는 다음과 같습니다.
Features
대화 요약 API는 자연어 처리 기술을 사용하여 요청당 더 짧은 요약으로 대화를 요약합니다. 대화 요약은 두 당사자 대화에서 논의된 문제 및 해결을 요약하거나 긴 대화를 챕터로 요약하고 각 챕터에 대한 짧은 설명을 요약할 수 있습니다.
텍스트 요약이라는 foundry 도구의 Azure Language의 또 다른 기능은 문서를 간결한 요약으로 요약하는 데 더 적합합니다. 텍스트 요약과 대화 요약 중에서 결정할 때는 다음 사항을 고려합니다.
- 입력 형식: 대화 요약은 화자와 발화를 포함하는 채팅 텍스트와 음성 기록 모두에서 작동할 수 있습니다. 텍스트 요약은 간단한 텍스트 또는 Word, PDF 또는 PowerPoint 형식을 사용하여 작동합니다.
- 요약 목적: 예를 들어
conversation issue and resolution summarization 고객과 고객 서비스 에이전트 간의 채팅에 대한 이유와 해결을 반환합니다.
데이터 제출
문서를 텍스트 문자열로 API에 제출합니다. API는 요청을 받으면 분석을 수행합니다. API는 비동기이므로 API 요청을 보내고 결과를 받는 사이에 지연이 있을 수 있습니다. 분 및 초 단위로 보낼 수 있는 요청의 크기와 수에 대한 자세한 내용은 다음 데이터 제한을 참조하세요.
이 기능을 사용하는 경우 요청이 수집된 시간부터 24시간 동안 API 결과를 사용할 수 있으며 응답에 표시됩니다. 이 기간이 지나면 결과가 제거되고 더 이상 검색할 수 없습니다.
대화 요약에 데이터를 제출할 때 대기 시간을 단축하기 위해 요청당 하나의 채팅 로그를 보내는 것이 좋습니다.
텍스트 채팅에서 요약 가져오기
대화 문제 및 해결 요약을 사용하여 필요에 따라 요약을 가져올 수 있습니다. 텍스트 채팅을 사용하는 예제를 보려면 빠른 시작 문서를 참조하세요.
음성 전사에서 요약 가져오기
conversation issue and resolution summarization 또한 Speech 서비스의 음성을 텍스트로 변환하는 기능을 사용하여 음성 대본에서 요약을 가져올 수 있습니다. 다음 예제에서는 API 요청에 포함할 수 있는 짧은 대화를 보여 줍니다.
"conversations":[
   {
      "id":"abcdefgh-1234-1234-1234-1234abcdefgh",
      "language":"en",
      "modality":"transcript",
      "conversationItems":[
         {
            "modality":"transcript",
            "participantId":"speaker",
            "id":"12345678-abcd-efgh-1234-abcd123456",
            "content":{
               "text":"Hi.",
               "lexical":"hi",
               "itn":"hi",
               "maskedItn":"hi",
               "audioTimings":[
                  {
                     "word":"hi",
                     "offset":4500000,
                     "duration":2800000
                  }
               ]
            }
         }
      ]
   }
]
챕터 제목 가져오기
대화 챕터 제목 요약을 사용하면 입력 대화에서 챕터 제목을 가져올 수 있습니다. 안내된 예제 시나리오는 다음과 같습니다.
- 다음 명령을 텍스트 편집기에 복사합니다. BASH 예에서는
\ 줄 연속 문자를 사용합니다. 콘솔 또는 터미널에서 다른 줄 연속 문자를 사용하는 경우 해당 문자를 사용하세요.
curl -i -X POST https://<your-language-resource-endpoint>/language/analyze-conversations/jobs?api-version=2023-11-15-preview \
-H "Content-Type: application/json" \
-H "Ocp-Apim-Subscription-Key: <your-language-resource-key>" \
-d \
'
{
  "displayName": "Conversation Task Example",
  "analysisInput": {
    "conversations": [
      {
        "conversationItems": [
          {
            "text": "Hello, you're chatting with Rene. How may I help you?",
            "id": "1",
            "role": "Agent",
            "participantId": "Agent_1"
          },
          {
            "text": "Hi, I tried to set up wifi connection for Smart Brew 300 espresso machine, but it didn't work.",
            "id": "2",
            "role": "Customer",
            "participantId": "Customer_1"
          },
          {
            "text": "I'm sorry to hear that. Let's see what we can do to fix this issue. Could you please try the following steps for me? First, could you push the wifi connection button, hold for 3 seconds, then let me know if the power light is slowly blinking on and off every second?",
            "id": "3",
            "role": "Agent",
            "participantId": "Agent_1"
          },
          {
            "text": "Yes, I pushed the wifi connection button, and now the power light is slowly blinking.",
            "id": "4",
            "role": "Customer",
            "participantId": "Customer_1"
          },
          {
            "text": "Great. Thank you! Now, please check in your Contoso Coffee app. Does it prompt to ask you to connect with the machine? ",
            "id": "5",
            "role": "Agent",
            "participantId": "Agent_1"
          },
          {
            "text": "No. Nothing happened.",
            "id": "6",
            "role": "Customer",
            "participantId": "Customer_1"
          },
          {
            "text": "I'm very sorry to hear that. Let me see if there's another way to fix the issue. Please hold on for a minute.",
            "id": "7",
            "role": "Agent",
            "participantId": "Agent_1"
          }
        ],
        "modality": "text",
        "id": "conversation1",
        "language": "en"
      }
    ]
  },
  "tasks": [
    {
      "taskName": "Conversation Task 1",
      "kind": "ConversationalSummarizationTask",
      "parameters": {
        "summaryAspects": [
          "chapterTitle"
        ]
      }
    }
  ]
}
'
필요한 경우 명령에서 다음 내용을 변경합니다.
-
your-value-language-key 값을 키로 바꿉니다.
- 요청 URL
your-language-resource-endpoint의 첫 번째 부분을 고유한 엔드포인트 URL로 바꿉니다.
명령 프롬프트 창(예: BASH)을 엽니다.
텍스트 편집기에서 명령 프롬프트 창으로 명령을 붙여넣은 후 명령을 실행합니다.
응답 헤더에서 operation-location을 가져옵니다. 값은 다음 URL과 유사합니다.
https://<your-language-resource-endpoint>/language/analyze-conversations/jobs/12345678-1234-1234-1234-12345678?api-version=2023-11-15-preview
- 요청 결과를 가져오려면 다음 cURL 명령을 사용합니다.
<my-job-id>를 이전 operation-location 응답 헤더에서 받은 GUID 값으로 바꿉니다.
curl -X GET https://<your-language-resource-endpoint>/language/analyze-conversations/jobs/<my-job-id>?api-version=2023-11-15-preview \
-H "Content-Type: application/json" \
-H "Ocp-Apim-Subscription-Key: <your-language-resource-key>"
챕터 제목 요약 JSON 응답 예:
{
    "jobId": "b01af3b7-1870-460a-9e36-09af28d360a1",
    "lastUpdatedDateTime": "2023-11-15T18:24:26Z",
    "createdDateTime": "2023-11-15T18:24:23Z",
    "expirationDateTime": "2023-11-16T18:24:23Z",
    "status": "succeeded",
    "errors": [],
    "displayName": "Conversation Task Example",
    "tasks": {
        "completed": 1,
        "failed": 0,
        "inProgress": 0,
        "total": 1,
        "items": [
            {
                "kind": "conversationalSummarizationResults",
                "taskName": "Conversation Task 1",
                "lastUpdateDateTime": "2023-11-15T18:24:26.3433677Z",
                "status": "succeeded",
                "results": {
                    "conversations": [
                        {
                            "summaries": [
                                {
                                    "aspect": "chapterTitle",
                                    "text": "\"Discussing the Problem of Smart Blend 300 Espresso Machine's Wi-Fi Connectivity\"",
                                    "contexts": [
                                        {
                                            "conversationItemId": "1",
                                            "offset": 0,
                                            "length": 53
                                        },
                                        {
                                            "conversationItemId": "2",
                                            "offset": 0,
                                            "length": 94
                                        },
                                        {
                                            "conversationItemId": "3",
                                            "offset": 0,
                                            "length": 266
                                        },
                                        {
                                            "conversationItemId": "4",
                                            "offset": 0,
                                            "length": 85
                                        },
                                        {
                                            "conversationItemId": "5",
                                            "offset": 0,
                                            "length": 119
                                        },
                                        {
                                            "conversationItemId": "6",
                                            "offset": 0,
                                            "length": 21
                                        },
                                        {
                                            "conversationItemId": "7",
                                            "offset": 0,
                                            "length": 109
                                        }
                                    ]
                                }
                            ],
                            "id": "conversation1",
                            "warnings": []
                        }
                    ],
                    "errors": [],
                    "modelVersion": "latest"
                }
            }
        ]
    }
}
긴 대화의 경우 모델은 이를 여러 응집력 있는 부분으로 분할하고 각 세그먼트를 요약할 수 있습니다. 또한 요약을 생성한 입력 대화의 범위를 알려 주는 각 요약에 대한 긴 contexts 필드도 있습니다.
설명 요약 가져오기
대화 요약을 사용하면 입력 대화에서 설명 요약을 가져올 수도 있습니다. 다음과 같은 예제 시나리오가 제공됩니다.
- 다음 명령을 텍스트 편집기에 복사합니다. BASH 예에서는
\ 줄 연속 문자를 사용합니다. 콘솔 또는 터미널에서 다른 줄 연속 문자를 사용하는 경우 해당 문자를 사용하세요.
curl -i -X POST https://<your-language-resource-endpoint>/language/analyze-conversations/jobs?api-version=2023-11-15-preview \
-H "Content-Type: application/json" \
-H "Ocp-Apim-Subscription-Key: <your-language-resource-key>" \
-d \
'
{
  "displayName": "Conversation Task Example",
  "analysisInput": {
    "conversations": [
      {
        "conversationItems": [
          {
            "text": "Hello, you're chatting with Rene. How may I help you?",
            "id": "1",
            "role": "Agent",
            "participantId": "Agent_1"
          },
          {
            "text": "Hi, I tried to set up wifi connection for Smart Brew 300 espresso machine, but it didn't work.",
            "id": "2",
            "role": "Customer",
            "participantId": "Customer_1"
          },
          {
            "text": "I'm sorry to hear that. Let's see what we can do to fix this issue. Could you please try the following steps for me? First, could you push the wifi connection button, hold for 3 seconds, then let me know if the power light is slowly blinking on and off every second?",
            "id": "3",
            "role": "Agent",
            "participantId": "Agent_1"
          },
          {
            "text": "Yes, I pushed the wifi connection button, and now the power light is slowly blinking.",
            "id": "4",
            "role": "Customer",
            "participantId": "Customer_1"
          },
          {
            "text": "Great. Thank you! Now, please check in your Contoso Coffee app. Does it prompt to ask you to connect with the machine? ",
            "id": "5",
            "role": "Agent",
            "participantId": "Agent_1"
          },
          {
            "text": "No. Nothing happened.",
            "id": "6",
            "role": "Customer",
            "participantId": "Customer_1"
          },
          {
            "text": "I'm very sorry to hear that. Let me see if there's another way to fix the issue. Please hold on for a minute.",
            "id": "7",
            "role": "Agent",
            "participantId": "Agent_1"
          }
        ],
        "modality": "text",
        "id": "conversation1",
        "language": "en"
      }
    ]
  },
  "tasks": [
    {
      "taskName": "Conversation Task 1",
      "kind": "ConversationalSummarizationTask",
      "parameters": {
        "summaryAspects": [
          "narrative"
        ]
      }
    }
  ]
}
'
필요한 경우 명령에서 다음 내용을 변경합니다.
-
your-language-resource-key 값을 키로 바꿉니다.
- 요청 URL
your-language-resource-endpoint의 첫 번째 부분을 고유한 엔드포인트 URL로 바꿉니다.
명령 프롬프트 창(예: BASH)을 엽니다.
텍스트 편집기에서 명령 프롬프트 창으로 명령을 붙여넣은 후 명령을 실행합니다.
응답 헤더에서 operation-location을 가져옵니다. 값은 다음 URL과 유사합니다.
https://<your-language-resource-endpoint>/language/analyze-conversations/jobs/12345678-1234-1234-1234-12345678?api-version=2023-11-15-preview
- 요청 결과를 가져오려면 다음 cURL 명령을 사용합니다.
<my-job-id>를 이전 operation-location 응답 헤더에서 받은 GUID 값으로 바꿉니다.
curl -X GET https://<your-language-resource-endpoint>/language/analyze-conversations/jobs/<my-job-id>?api-version=2023-11-15-preview \
-H "Content-Type: application/json" \
-H "Ocp-Apim-Subscription-Key: <your-language-resource-key>"
설명 요약 JSON 응답 예:
{
  "jobId": "d874a98c-bf31-4ac5-8b94-5c236f786754",
  "lastUpdatedDateTime": "2022-09-29T17:36:42Z",
  "createdDateTime": "2022-09-29T17:36:39Z",
  "expirationDateTime": "2022-09-30T17:36:39Z",
  "status": "succeeded",
  "errors": [],
  "displayName": "Conversation Task Example",
  "tasks": {
    "completed": 1,
    "failed": 0,
    "inProgress": 0,
    "total": 1,
    "items": [
      {
        "kind": "conversationalSummarizationResults",
        "taskName": "Conversation Task 1",
        "lastUpdateDateTime": "2022-09-29T17:36:42.895694Z",
        "status": "succeeded",
        "results": {
          "conversations": [
            {
              "summaries": [
                {
                  "aspect": "narrative",
                  "text": "Agent_1 helps customer to set up wifi connection for Smart Brew 300 espresso machine.",
                  "contexts": [
                    { "conversationItemId": "1", "offset": 0, "length": 53 },
                    { "conversationItemId": "2", "offset": 0, "length": 94 },
                    { "conversationItemId": "3", "offset": 0, "length": 266 },
                    { "conversationItemId": "4", "offset": 0, "length": 85 },
                    { "conversationItemId": "5", "offset": 0, "length": 119 },
                    { "conversationItemId": "6", "offset": 0, "length": 21 },
                    { "conversationItemId": "7", "offset": 0, "length": 109 }
                  ]
                }
              ],
              "id": "conversation1",
              "warnings": []
            }
          ],
          "errors": [],
          "modelVersion": "latest"
        }
      }
    ]
  }
}
긴 대화의 경우 모델은 이를 여러 응집력 있는 부분으로 분할하고 각 세그먼트를 요약할 수 있습니다. 또한 요약을 생성한 입력 대화의 범위를 알려 주는 각 요약에 대한 긴 contexts 필드도 있습니다.
요약 및 후속 작업 요약 가져오기
대화 요약을 사용하면 입력 대화에서 요약 및 후속 작업을 가져올 수도 있습니다. 다음과 같은 예제 시나리오가 제공됩니다.
- 다음 명령을 텍스트 편집기에 복사합니다. BASH 예에서는
\ 줄 연속 문자를 사용합니다. 콘솔 또는 터미널에서 다른 줄 연속 문자를 사용하는 경우 해당 문자를 사용하세요.
curl -i -X POST https://<your-language-resource-endpoint>/language/analyze-conversations/jobs?api-version=2023-11-15-preview \
-H "Content-Type: application/json" \
-H "Ocp-Apim-Subscription-Key: <your-language-resource-key>" \
-d \
'
{
  "displayName": "Conversation Task Example",
  "analysisInput": {
    "conversations": [
      {
        "conversationItems": [
          {
            "text": "Hello, you're chatting with Rene. How may I help you?",
            "id": "1",
            "role": "Agent",
            "participantId": "Agent_1"
          },
          {
            "text": "Hi, I tried to set up wifi connection for Smart Brew 300 espresso machine, but it didn't work.",
            "id": "2",
            "role": "Customer",
            "participantId": "Customer_1"
          },
          {
            "text": "I'm sorry to hear that. Let's see what we can do to fix this issue. Could you please try the following steps for me? First, could you push the wifi connection button, hold for 3 seconds, then let me know if the power light is slowly blinking on and off every second?",
            "id": "3",
            "role": "Agent",
            "participantId": "Agent_1"
          },
          {
            "text": "Yes, I pushed the wifi connection button, and now the power light is slowly blinking.",
            "id": "4",
            "role": "Customer",
            "participantId": "Customer_1"
          },
          {
            "text": "Great. Thank you! Now, please check in your Contoso Coffee app. Does it prompt to ask you to connect with the machine? ",
            "id": "5",
            "role": "Agent",
            "participantId": "Agent_1"
          },
          {
            "text": "No. Nothing happened.",
            "id": "6",
            "role": "Customer",
            "participantId": "Customer_1"
          },
          {
            "text": "I'm very sorry to hear that. Let me see if there's another way to fix the issue. Please hold on for a minute.",
            "id": "7",
            "role": "Agent",
            "participantId": "Agent_1"
          }
        ],
        "modality": "text",
        "id": "conversation1",
        "language": "en"
      }
    ]
  },
  "tasks": [
    {
      "taskName": "Conversation Task 1",
      "kind": "ConversationalSummarizationTask",
      "parameters": {
        "summaryAspects": [
          "recap",
          "follow-up tasks"
        ]
      }
    }
  ]
}
'
필요한 경우 명령에서 다음 내용을 변경합니다.
-
your-language-resource-key 값을 키로 바꿉니다.
- 요청 URL
your-language-resource-endpoint의 첫 번째 부분을 고유한 엔드포인트 URL로 바꿉니다.
명령 프롬프트 창(예: BASH)을 엽니다.
텍스트 편집기에서 명령 프롬프트 창으로 명령을 붙여넣은 후 명령을 실행합니다.
응답 헤더에서 operation-location을 가져옵니다. 값은 다음 URL과 유사합니다.
https://<your-language-resource-endpoint>/language/analyze-conversations/jobs/12345678-1234-1234-1234-12345678?api-version=2023-11-15-preview
- 요청 결과를 가져오려면 다음 cURL 명령을 사용합니다.
<my-job-id>를 이전 operation-location 응답 헤더에서 받은 GUID 값으로 바꿉니다.
curl -X GET https://<your-language-resource-endpoint>/language/analyze-conversations/jobs/<my-job-id>?api-version=2023-11-15-preview \
-H "Content-Type: application/json" \
-H "Ocp-Apim-Subscription-Key: <your-language-resource-key>"
요약 및 후속 요약 JSON 응답 예제:
{
    "jobId": "e585d097-c19a-466e-8f99-a9646e55b1f5",
    "lastUpdatedDateTime": "2023-11-15T18:19:56Z",
    "createdDateTime": "2023-11-15T18:19:53Z",
    "expirationDateTime": "2023-11-16T18:19:53Z",
    "status": "succeeded",
    "errors": [],
    "displayName": "Conversation Task Example",
    "tasks": {
        "completed": 1,
        "failed": 0,
        "inProgress": 0,
        "total": 1,
        "items": [
            {
                "kind": "conversationalSummarizationResults",
                "taskName": "Conversation Task 1",
                "lastUpdateDateTime": "2023-11-15T18:19:56.1801785Z",
                "status": "succeeded",
                "results": {
                    "conversations": [
                        {
                            "summaries": [
                                {
                                    "aspect": "recap",
                                    "text": "The customer contacted the service agent, Rene, regarding an issue with setting up a wifi connection for their Smart Brew 300 espresso machine. The agent guided the customer through several steps, including pushing the wifi connection button and checking if the power light was blinking. However, the customer reported that no prompts were received in the Contoso Coffee app to connect with the machine. The agent then decided to look for another solution.",
                                    "contexts": [
                                        {
                                            "conversationItemId": "1",
                                            "offset": 0,
                                            "length": 53
                                        },
                                        {
                                            "conversationItemId": "2",
                                            "offset": 0,
                                            "length": 94
                                        },
                                        {
                                            "conversationItemId": "3",
                                            "offset": 0,
                                            "length": 266
                                        },
                                        {
                                            "conversationItemId": "4",
                                            "offset": 0,
                                            "length": 85
                                        },
                                        {
                                            "conversationItemId": "5",
                                            "offset": 0,
                                            "length": 119
                                        },
                                        {
                                            "conversationItemId": "6",
                                            "offset": 0,
                                            "length": 21
                                        },
                                        {
                                            "conversationItemId": "7",
                                            "offset": 0,
                                            "length": 109
                                        }
                                    ]
                                },
                                {
                                    "aspect": "Follow-Up Tasks",
                                    "text": "@Agent_1 will ask the customer to push the wifi connection button, hold for 3 seconds, then check if the power light is slowly blinking on and off every second."
                                },
                                {
                                    "aspect": "Follow-Up Tasks",
                                    "text": "@Agent_1 will ask the customer to check in the Contoso Coffee app if it prompts to connect with the machine."
                                },
                                {
                                    "aspect": "Follow-Up Tasks",
                                    "text": "@Agent_1 will investigate another way to fix the issue."
                                }
                            ],
                            "id": "conversation1",
                            "warnings": []
                        }
                    ],
                    "errors": [],
                    "modelVersion": "latest"
                }
            }
        ]
    }
}
긴 대화의 경우 모델은 이를 여러 응집력 있는 부분으로 분할하고 각 세그먼트를 요약할 수 있습니다. 또한 요약을 생성한 입력 대화의 범위를 알려 주는 각 요약에 대한 긴 contexts 필드도 있습니다.
대화 문제 및 해결 요약 결과 가져오기
다음 텍스트는 대화 문제 및 해결 요약을 위해 제출할 수 있는 콘텐츠의 예입니다. 그것은 단지 예입니다. API는 더 긴 입력 텍스트를 허용할 수 있습니다. 자세한 내용은 데이터 제한을참조하세요.
에이전트: "안녕하세요, 무엇을 도와드릴까요?"
고객: "Contoso 구독을 업그레이드하려면 어떻게 해야 하나요? 하루 종일 시도했습니다."
에이전트: "업그레이드 단추를 누른 다음, 로그인하고 지침을 따릅니다."
요약은 API 백 엔드에 대한 작업을 만들어 요청이 수신될 때 수행됩니다. 작업이 성공하면 API의 출력이 반환됩니다. 출력은 24시간 동안 검색에 사용할 수 있습니다. 이 시간이 지나면 출력이 제거됩니다. 다국어 지원 및 emoji 지원으로 인해 응답에 텍스트 오프셋이 포함될 수 있습니다. 자세한 내용은 오프셋을 처리하는 방법을참조하세요.
이전 예제에서 API는 요약된 문장 출력을 반환할 수 있습니다.
| 요약된 텍스트 |
Aspect |
| "고객은 구독을 업그레이드하려고 합니다. 고객은 방법을 모릅니다." |
문제 |
| "고객은 업그레이드 단추를 누르고 로그인해야 합니다." |
해결 방법 |
Important
- Foundry Tools의 Azure 언어 공개 미리 보기 릴리스는 현재 개발 중인 기능에 대한 초기 액세스를 제공합니다.
- 기능, 접근 방식 및 프로세스는 사용자 피드백에 따라 GA(일반 공급) 전에 변경 될 수 있습니다.
언어는 텍스트 기반 데이터에 NLP(자연어 처리) 기능을 적용하는 클라우드 기반 서비스입니다. 문서 요약은 자연어 처리를 사용하여 문서에 대한 추출(두드러진 문장 추출) 또는 추상적(상황별 단어 추출) 요약을 생성합니다.
AbstractiveSummarization API와 ExtractiveSummarization API는 모두 네이티브 문서 처리를 지원합니다. 네이티브 문서는 Microsoft Word(docx) 또는 이식 가능한 문서 파일(pdf)과 같은 원본 문서를 만드는 데 사용되는 파일 형식을 나타냅니다. 네이티브 문서 지원을 사용하면 언어 리소스 기능을 사용하기 전에 텍스트 전처리가 필요하지 않습니다. 네이티브 문서 지원 기능을 사용하면 HTTP POST 요청 본문을 사용하여 데이터 및 HTTP GET 요청 쿼리 문자열을 사용하여 상태 결과를 검색하는 API 요청을 비동기적으로 보낼 수 있습니다. 처리된 문서는 Azure Blob Storage 대상 컨테이너에 있습니다.
애플리케이션은 네이티브 파일 형식을 사용하여 네이티브 문서를 만들거나 저장하거나 엽니다. 현재 PII 및 문서 요약 기능은 다음과 같은 네이티브 문서 형식을 지원합니다.
| 파일 형식 |
파일 확장자 |
Description |
| Text |
.txt |
서식이 지정되지 않은 텍스트 문서입니다. |
| Adobe PDF |
.pdf |
이식 가능한 문서 파일 형식의 문서입니다. |
| 마이크로소프트 워드 |
.docx |
Microsoft Word 문서 파일입니다. |
지원되는 파일 형식
| Type |
지원 및 제한 사항 |
|
PDF |
완전히 스캔된 PDF는 지원되지 않습니다. |
|
이미지 내의 텍스트 |
텍스트가 포함된 디지털 이미지는 지원되지 않습니다. |
|
디지털 테이블 |
스캔한 문서의 테이블은 지원되지 않습니다. |
문서 크기
| Attribute |
입력 제한 |
|
요청당 총 문서 수 |
≤ 20 |
|
요청당 총 콘텐츠 크기 |
≤ 10MB |
HTTP 요청을 사용하여 네이티브 문서 포함
시작해 보겠습니다.
이 프로젝트의 경우 cURL 명령줄 도구를 사용하여 REST API를 호출합니다.
메모
cURL 패키지는 대부분의 Windows 10 및 Windows 11 및 대부분의 macOS 및 Linux 배포판에 미리 설치됩니다. 다음 명령을 사용하여 패키지 버전을 확인할 수 있습니다. Windows: curl.exe -V macOS curl -V Linux: curl --version
활성 Azure 계정. 계정이 없는 경우 체험 계정을 만들 수 있습니다.
Azure Blob Storage 계정. 또한 원본 및 대상 파일에 대한 Azure Blob Storage 계정에서 컨테이너를 만들어야 합니다.
-
원본 컨테이너. 이 컨테이너는 분석을 위해 네이티브 파일을 업로드하는 위치입니다(필수).
-
대상 컨테이너. 이 컨테이너는 분석된 파일이 저장되는 위치입니다(필수).
단일 서비스 언어 리소스(다중 서비스 Microsoft Foundry 리소스가 아님)
Azure 언어 리소스 프로젝트 및 인스턴스 세부 정보 필드를 다음과 같이 완성하십시오:
구독. 사용 가능한 Azure 구독 중 하나를 선택합니다.
리소스 그룹. 새 리소스 그룹을 만들거나 동일한 수명 주기, 사용 권한 및 정책을 공유하는 기존 리소스 그룹에 리소스를 추가할 수 있습니다.
리소스 지역. 비즈니스 또는 애플리케이션에 특정 지역이 필요하지 않은 경우 전역 을 선택합니다. 인증에 시스템 할당 관리 ID를 사용하려는 경우 미국 서부와 같은 지리적 지역을 선택합니다.
이름. 리소스에 대해 선택한 이름을 입력합니다. 선택한 이름은 Azure 내에서 고유해야 합니다.
가격 책정 계층. 무료 가격 책정 계층(Free F0)을 사용하여 서비스를 사용해 볼 수 있으며 나중에 프로덕션용 유료 계층으로 업그레이드할 수 있습니다.
검토 + 생성를 선택합니다.
서비스 약관을 검토하고 만들기 를 선택하여 리소스를 배포합니다.
리소스를 성공적으로 배포한 후 리소스로 이동을 선택합니다.
키 및 언어 엔드포인트 검색
Azure 언어에 대한 요청에는 액세스를 인증하려면 읽기 전용 키 및 사용자 지정 엔드포인트가 필요합니다.
새 리소스를 만든 경우 배포한 후 리소스로 이동을 선택합니다. 기존 언어 리소스가 있는 경우 리소스 페이지로 직접 이동합니다.
왼쪽 레일의 리소스 관리에서 키 및 엔드포인트를 선택합니다.
key 및 Language instance endpoint 복사하여 코드 샘플에 붙여넣어 Azure 언어에 대한 요청을 인증할 수 있습니다. API 호출을 수행하는 데는 키가 하나만 필요합니다.
Azure Blob Storage 컨테이너 만들기
컨테이너를 생성하십시오Azure Blob Storage 계정에서 원본 및 대상 파일을 위해.
-
원본 컨테이너. 이 컨테이너는 분석을 위해 네이티브 파일을 업로드하는 위치입니다(필수).
-
대상 컨테이너. 이 컨테이너는 분석된 파일이 저장되는 위치입니다(필수).
인증
Blob을 만들거나 읽거나 삭제하려면 언어 리소스에 스토리지 계정에 대한 액세스 권한이 부여되어야 합니다. 스토리지 데이터에 대한 액세스 권한을 부여하는 데 사용할 수 있는 두 가지 기본 방법이 있습니다.
SAS(공유 액세스 서명) 토큰입니다. 사용자 위임 SAS 토큰은 Microsoft Entra 자격 증명으로 보호됩니다. SAS 토큰은 Azure 스토리지 계정의 리소스에 대한 안전하고 위임된 액세스를 제공합니다.
RBAC(관리 ID 역할 기반 액세스 제어). Azure 리소스에 대한 관리 ID는 Microsoft Entra ID 및 Azure 관리되는 리소스에 대한 특정 권한을 만드는 서비스 주체입니다.
이 프로젝트의 경우 SAS(공유 액세스 서명) 토큰이 쿼리 문자열로 추가된 source location 및 target location URL에 대한 액세스를 인증하도록 합니다. 각 토큰은 특정 Blob(파일)에 할당됩니다.

-
원본 컨테이너 또는 Blob은 읽기 및 목록 액세스를 지정해야 합니다.
-
대상 컨테이너 또는 Blob은 쓰기 및 목록 액세스를 지정해야 합니다.
추출 요약 API는 자연어 처리 기술을 사용하여 구조화되지 않은 텍스트 문서에서 핵심 문장을 찾습니다. 이러한 문장은 문서의 주요 개념을 전체적으로 전달합니다.
추출 요약은 추출된 문장, 원본 문서 내 위치와 함께 순위 점수를 시스템 응답의 일부로 반환합니다. 순위 점수는 문장과 문서의 기본 아이디어 간 관련성을 나타내는 표시기입니다. 모델은 각 문장에 대해 0~1(포함) 사이의 점수를 제공하고 요청당 점수가 가장 높은 문장을 반환합니다. 예를 들어, 3개 문장 요약을 요청하는 경우 서비스는 점수가 가장 높은 3개 문장을 반환합니다.
언어에는 핵심 정보를 추출할 수 있는 핵심 구 추출 기능이 있습니다. 핵심 구 추출과 추출 요약 중에서 결정하려면 다음과 같은 유용한 고려 사항이 있습니다.
- 핵심 구 추출은 구를 반환하는 반면, 추출 요약은 문장을 반환합니다.
- 추출 요약은 순위 점수와 함께 문장을 반환하며 요청당 상위 순위 문장이 반환됩니다.
- 추출 요약은 다음 위치 정보도 반환합니다.
- 오프셋: 추출된 각 문장의 시작 위치입니다.
- 길이: 추출된 각 문장의 길이입니다.
데이터 처리 방법 결정(선택 사항)
데이터 제출
문서를 텍스트 문자열로 API에 제출합니다. 요청을 받으면 분석이 수행됩니다. API는 비동기이므로 API 요청을 보내고 결과를 받는 사이에 지연이 있을 수 있습니다.
이 기능을 사용하는 경우 요청이 수집된 시간부터 24시간 동안 API 결과를 사용할 수 있으며 응답에 표시됩니다. 이 기간이 지나면 결과가 제거되고 더 이상 검색할 수 없습니다.
텍스트 요약 결과 가져오기
언어 감지에서 결과를 가져올 때 애플리케이션에 결과를 스트리밍하거나 로컬 시스템의 파일에 출력을 저장할 수 있습니다.
다음은 Microsoft 블로그 문서 통합 AI에 대한 전체적인 표현을 사용하여 추출된 요약을 위해 제출할 수 있는 콘텐츠의 예입니다. 이 문서는 예제일 뿐입니다. API는 더 긴 입력 텍스트를 허용할 수 있습니다. 자세한 내용은 데이터 및 서비스 제한을참조하세요.
"Microsoft에서는 학습과 이해에 대해 보다 전체적이고 인간 중심적인 접근 방식을 취함으로써 기존 기술을 넘어 AI를 발전시키기 위한 노력을 기울이고 있습니다. Foundry Tools의 최고 기술 책임자로서 저는 놀라운 과학자 및 엔지니어 팀과 협력하여 이 탐구를 현실로 바꾸고 있습니다. 제 역할에서 저는 인간 인지의 세 가지 특성, 즉 단일 언어 텍스트(X), 청각 또는 시각 감각 신호(Y) 및 다국어(Z) 간의 관계를 보는 고유한 관점을 활용합니다. 세 가지가 모두 교차하는 지점에는 그림 1에 나와 있는 바와 같이 XYZ-코드라고 하는 매직이 있습니다. 인간보다 더 잘 말하고, 듣고, 보고, 이해할 수 있는 강력한 AI를 만드는 공동 표현입니다. XYZ-코드를 통해 장기적인 비전(도메인 간 전이 학습, 형식 및 언어 확장)을 수행할 수 있습니다. 목표는 오늘날 인간이 하는 것처럼 광범위한 다운스트림 AI 작업을 지원하기 위해 표현을 공동으로 학습할 수 있는 미리 학습된 모델을 보유하는 것입니다. 지난 5년 동안 우리는 대화형 음성 인식, 기계 번역, 대화형 질문 답변, 기계 읽기 이해 및 이미지 캡션 분야에서 벤치마크에서 인간의 성과를 달성했습니다. 이러한 5가지 혁신은 인간이 학습하고 이해하는 방식에 더 가까운 다감각적이고 다국어 학습을 달성하기 위한 AI 기능의 도약을 이루고자 하는 원대한 열망에 대한 강력한 신호를 제공했습니다. 저는 다운스트림 AI 작업에서 외부 기술 자료를 기반으로 한 경우에는 공동 XYZ- 코드가 이러한 열망의 기본 구성 요소라고 생각합니다."
텍스트 요약 API 요청은 API 백 엔드에 대한 작업을 만들어 요청을 수신하면 처리됩니다. 작업이 성공하면 API의 출력이 반환됩니다. 출력은 24시간 동안 검색에 사용할 수 있습니다. 이 시간이 지나면 출력이 제거됩니다. 다국어 지원 및 emoji 지원으로 인해 응답에 텍스트 오프셋이 포함될 수 있습니다. 자세한 내용은 오프셋을 처리하는 방법을참조하세요.
앞의 예제를 사용하는 경우 API는 다음과 같은 요약된 문장을 반환할 수 있습니다.
추출 요약:
- "Microsoft에서는 학습과 이해에 대해 보다 전체적이고 인간 중심적인 접근 방식을 취함으로써 기존 기술을 넘어 AI를 발전시키기 위한 노력을 기울이고 있습니다."
- "XYZ-코드를 통해 장기적인 비전(도메인 간 전이 학습, 형식 및 언어 확장)을 수행할 수 있습니다."
- "목표는 오늘날 인간이 하는 것처럼 광범위한 다운스트림 AI 작업을 지원하기 위해 표현을 공동으로 학습할 수 있는 미리 학습된 모델을 보유하는 것입니다."
추상 요약:
- "Microsoft는 학습 및 이해에 대해 보다 총체적이고 인간 중심적인 방식을 취하고 있습니다. XYZ-코드를 통해 장기적인 비전(도메인 간 전이 학습, 형식 및 언어 확장)을 수행할 수 있습니다. 지난 5년 동안 우리는 주요 성과 지표에서 인간 수준의 성과를 달성했습니다.
텍스트 추출 요약을 사용하여 문서, 논문 또는 문서의 요약을 가져올 수 있습니다. 예를 보려면 빠른 시작 문서을 참조하세요.
sentenceCount 매개 변수를 사용하여 반환될 문장 수를 안내할 수 있으며 기본값은 3입니다. 범위는 1~20 사이입니다.
또한 sortby 매개 변수를 추출한 문장이 반환되는 순서(Offset 또는 Rank)를 지정할 수 있으며 기본값은 Offset입니다.
| 매개 변수 값 |
Description |
| Rank |
서비스에서 결정한 대로 입력 문서와의 관련성에 따라 문장을 정렬합니다. |
| Offset |
입력 문서에 문장이 나타나는 원래 순서를 유지합니다. |
텍스트 추상 요약 시도
다음 예에서는 텍스트 추상 요약을 시작하게 합니다.
- 다음 명령을 텍스트 편집기에 복사합니다. BASH 예에서는
\ 줄 연속 문자를 사용합니다. 콘솔 또는 터미널에서 다른 줄 연속 문자를 사용하는 경우 해당 문자를 대신 사용하세요.
curl -i -X POST https://<your-language-resource-endpoint>/language/analyze-text/jobs?api-version=2023-04-01 \
-H "Content-Type: application/json" \
-H "Ocp-Apim-Subscription-Key: <your-language-resource-key>" \
-d \
'
{
  "displayName": "Text Abstractive Summarization Task Example",
  "analysisInput": {
    "documents": [
      {
        "id": "1",
        "language": "en",
        "text": "At Microsoft, we have been on a quest to advance AI beyond existing techniques, by taking a more holistic, human-centric approach to learning and understanding. As Chief Technology Officer of Foundry Tools, I have been working with a team of amazing scientists and engineers to turn this quest into a reality. In my role, I enjoy a unique perspective in viewing the relationship among three attributes of human cognition: monolingual text (X), audio or visual sensory signals, (Y) and multilingual (Z). At the intersection of all three, there's magic—what we call XYZ-code as illustrated in Figure 1—a joint representation to create more powerful AI that can speak, hear, see, and understand humans better. We believe XYZ-code enables us to fulfill our long-term vision: cross-domain transfer learning, spanning modalities and languages. The goal is to have pretrained models that can jointly learn representations to support a broad range of downstream AI tasks, much in the way humans do today. Over the past five years, we have achieved human performance on benchmarks in conversational speech recognition, machine translation, conversational question answering, machine reading comprehension, and image captioning. These five breakthroughs provided us with strong signals toward our more ambitious aspiration to produce a leap in AI capabilities, achieving multi-sensory and multilingual learning that is closer in line with how humans learn and understand. I believe the joint XYZ-code is a foundational component of this aspiration, if grounded with external knowledge sources in the downstream AI tasks."
      }
    ]
  },
  "tasks": [
    {
      "kind": "AbstractiveSummarization",
      "taskName": "Text Abstractive Summarization Task 1",
    }
  ]
}
'
필요한 경우 명령에서 다음 내용을 변경합니다.
-
your-language-resource-key 값을 키로 바꿉니다.
- 요청 URL
your-language-resource-endpoint의 첫 번째 부분을 고유한 엔드포인트 URL로 바꿉니다.
명령 프롬프트 창(예: BASH)을 엽니다.
텍스트 편집기에서 명령 프롬프트 창으로 명령을 붙여넣은 후 명령을 실행합니다.
응답 헤더에서 operation-location을 가져옵니다. 값은 다음 URL과 유사합니다.
https://<your-language-resource-endpoint>/language/analyze-text/jobs/12345678-1234-1234-1234-12345678?api-version=2022-10-01-preview
- 요청 결과를 가져오려면 다음 cURL 명령을 사용합니다.
<my-job-id>을(를) 이전 operation-location 응답 헤더에서 받은 숫자 ID 값으로 반드시 교체해야 합니다.
curl -X GET https://<your-language-resource-endpoint>/language/analyze-text/jobs/<my-job-id>?api-version=2022-10-01-preview \
-H "Content-Type: application/json" \
-H "Ocp-Apim-Subscription-Key: <your-language-resource-key>"
추상 텍스트 요약 예제 JSON 응답
{
    "jobId": "cd6418fe-db86-4350-aec1-f0d7c91442a6",
    "lastUpdateDateTime": "2022-09-08T16:45:14Z",
    "createdDateTime": "2022-09-08T16:44:53Z",
    "expirationDateTime": "2022-09-09T16:44:53Z",
    "status": "succeeded",
    "errors": [],
    "displayName": "Text Abstractive Summarization Task Example",
    "tasks": {
        "completed": 1,
        "failed": 0,
        "inProgress": 0,
        "total": 1,
        "items": [
            {
                "kind": "AbstractiveSummarizationLROResults",
                "taskName": "Text Abstractive Summarization Task 1",
                "lastUpdateDateTime": "2022-09-08T16:45:14.0717206Z",
                "status": "succeeded",
                "results": {
                    "documents": [
                        {
                            "summaries": [
                                {
                                    "text": "Microsoft is taking a more holistic, human-centric approach to AI. We've developed a joint representation to create more powerful AI that can speak, hear, see, and understand humans better. We've achieved human performance on benchmarks in conversational speech recognition, machine translation, ...... and image captions.",
                                    "contexts": [
                                        {
                                            "offset": 0,
                                            "length": 247
                                        }
                                    ]
                                }
                            ],
                            "id": "1"
                        }
                    ],
                    "errors": [],
                    "modelVersion": "latest"
                }
            }
        ]
    }
}
| 매개변수 |
Description |
-X POST <endpoint> |
API에 액세스하기 위한 언어 리소스 엔드포인트를 지정합니다. |
--header Content-Type: application/json |
JSON 데이터를 보내기 위한 콘텐츠 형식입니다. |
--header "Ocp-Apim-Subscription-Key:<key> |
API에 액세스하기 위한 Azure 언어 리소스 키를 지정합니다. |
-data |
요청과 함께 전달하려는 데이터가 포함된 JSON 파일입니다. |
다음 cURL 명령은 BASH 셸에서 실행됩니다. 사용자 고유의 리소스 이름, 리소스 키 및 JSON 값을 사용하여 이 명령을 편집합니다.
Personally Identifiable Information (PII) 또는 Document Summarization 코드 샘플 프로젝트를 선택하여 원본 문서를 분석해 보세요.
요약 샘플 문서
이 프로젝트의 경우 원본 컨테이너에 업로드된 원본 문서가 필요합니다. 이 빠른 시작에 대한 Microsoft Word 샘플 문서 또는 Adobe PDF를 다운로드할 수 있습니다. 원본 언어는 영어입니다.
POST 요청 빌드
기본 설정 편집기 또는 IDE를 사용하여 이름이 지정된 native-document앱에 대한 새 디렉터리를 만듭니다.
native-document 디렉터리에 document-summarization.json이라는 새 json 파일을 만듭니다.
문서 요약 요청 샘플을 복사하여 document-summarization.json 파일에 붙여넣습니다.
{your-source-container-SAS-URL} 및 {your-target-container-SAS-URL} Azure Portal Storage 계정 컨테이너 인스턴스의 값으로 대체합니다.
요청 샘플
  {
  "tasks": [
    {
      "kind": "ExtractiveSummarization",
      "parameters": {
        "sentenceCount": 6
      }
    }
  ],
  "analysisInput": {
    "documents": [
      {
        "source": {
          "location": "{your-source-blob-SAS-URL}"
        },
        "targets": {
          "location": "{your-target-container-SAS-URL}"
        }
      }
    ]
  }
}
POST 요청 실행
POST 요청을 실행하기 전에 {your-language-resource-endpoint} 및 {your-key}를 Azure Portal 언어 리소스 인스턴스의 엔드포인트 값으로 바꿉니다.
Important
완료되면 코드에서 키를 제거하고 공개적으로 게시하지 마세요. 프로덕션의 경우 Azure Key Vault와 같은 자격 증명을 안전하게 저장하고 액세스하는 방법을 사용합니다. 자세한 내용은 Foundry 도구 보안을참조하세요.
PowerShell
cmd /c curl "{your-language-resource-endpoint}/language/analyze-documents/jobs?api-version=2024-11-15-preview" -i -X POST --header "Content-Type: application/json" --header "Ocp-Apim-Subscription-Key: {your-key}" --data "@document-summarization.json"
명령 프롬프트/터미널
curl -v -X POST "{your-language-resource-endpoint}/language/analyze-documents/jobs?api-version=2024-11-15-preview" --header "Content-Type: application/json" --header "Ocp-Apim-Subscription-Key: {your-key}" --data "@document-summarization.json"
샘플 응답:
HTTP/1.1 202 Accepted
Content-Length: 0
operation-location: https://{your-language-resource-endpoint}/language/analyze-documents/jobs/f1cc29ff-9738-42ea-afa5-98d2d3cabf94?api-version=2024-11-15-preview
apim-request-id: e7d6fa0c-0efd-416a-8b1e-1cd9287f5f81
x-ms-region: West US 2
Date: Thu, 25 Jan 2024 15:12:32 GMT
POST 응답(jobId)
읽기 전용 Operation-Location 헤더를 포함하는 202(성공) 응답을 받습니다. 이 헤더의 값에는 GET 요청을 사용하여 비동기 작업의 상태를 가져오고 결과를 검색하기 위해 쿼리할 수 있는 jobId가 포함되어 있습니다.

분석 결과 가져오기(GET 요청)
POST 요청이 성공하면 POST 요청에 반환된 작업 위치 헤더를 폴링하여 처리된 데이터를 봅니다.
GET 요청의 구조는 다음과 같습니다.
GET {cognitive-service-endpoint}/language/analyze-documents/jobs/{jobId}?api-version=2024-11-15-preview
명령을 실행하기 전에 다음과 같이 변경합니다.
요청 가져오기
cmd /c curl "{your-language-resource-endpoint}/language/analyze-documents/jobs/{jobId}?api-version=2024-11-15-preview" -i -X GET --header "Content-Type: application/json" --header "Ocp-Apim-Subscription-Key: {your-key}"
curl -v -X GET "{your-language-resource-endpoint}/language/analyze-documents/jobs/{jobId}?api-version=2024-11-15-preview" --header "Content-Type: application/json" --header "Ocp-Apim-Subscription-Key: {your-key}"
응답 검사
JSON 출력을 사용하여 200(성공) 응답을 받습니다.
상태 필드는 작업의 결과를 나타냅니다. 작업이 완료되지 않은 경우 상태 값은 "실행 중" 또는 "notStarted"이며 수동으로 또는 스크립트를 통해 API를 다시 호출해야 합니다. 호출 간에 1초 이상의 간격을 사용하는 것이 좋습니다.
샘플 응답
{
  "jobId": "f1cc29ff-9738-42ea-afa5-98d2d3cabf94",
  "lastUpdatedDateTime": "2024-01-24T13:17:58Z",
  "createdDateTime": "2024-01-24T13:17:47Z",
  "expirationDateTime": "2024-01-25T13:17:47Z",
  "status": "succeeded",
  "errors": [],
  "tasks": {
    "completed": 1,
    "failed": 0,
    "inProgress": 0,
    "total": 1,
    "items": [
      {
        "kind": "ExtractiveSummarizationLROResults",
        "lastUpdateDateTime": "2024-01-24T13:17:58.33934Z",
        "status": "succeeded",
        "results": {
          "documents": [
            {
              "id": "doc_0",
              "source": {
                "kind": "AzureBlob",
                "location": "https://myaccount.blob.core.windows.net/sample-input/input.pdf"
              },
              "targets": [
                {
                  "kind": "AzureBlob",
                  "location": "https://myaccount.blob.core.windows.net/sample-output/df6611a3-fe74-44f8-b8d4-58ac7491cb13/ExtractiveSummarization-0001/input.result.json"
                }
              ],
              "warnings": []
            }
          ],
          "errors": [],
          "modelVersion": "2023-02-01-preview"
        }
      }
    ]
  }
}
성공적으로 완료되면 다음을 수행합니다.
- 분석된 문서는 대상 컨테이너에서 찾을 수 있습니다.
- 성공적인 POST 메서드는 서비스에서 일괄 처리 요청을 생성했음을 나타내는 응답 코드를 반환
202 Accepted 합니다.
- POST 요청은 후속 GET 요청에 사용되는 값을 제공하는 응답 헤더
Operation-Location 도 반환했습니다.
자원을 정리하세요
Azure AI 리소스를 정리하고 제거하려면 개별 리소스 또는 전체 리소스 그룹을 삭제할 수 있습니다. 리소스 그룹을 삭제하면 포함된 모든 리소스도 삭제됩니다.