請參考以下快速入門,或取得具備瀏覽器語音介面的完整網頁應用程式:
在本文中,您將學習如何在 Microsoft Foundry 入口網站 中,使用 Voice Live 搭配生成式 AI 和 Foundry 工具中的 Azure 語音。
您會建立並執行應用程式,藉此將內含生成式 AI 模型的 Voice Live 直接使用於即時語音代理程式。
使用模型直接允許為每個會話指定自定義指示(提示),為動態或實驗使用案例提供更多彈性。
當您想要更精細地控制會話參數,或需要經常調整提示或設定,而不需在入口網站中更新代理程式時,最好使用模型。
模型型會話的程式代碼在某些方面比較簡單,因為它不需要管理代理程式標識碼或代理程式特定的設定。
直接模型使用適用於不需要代理程式層級抽象或內建邏輯的案例。
若想改用 Voice Live API 搭配代理,請參閱 Voice Live API 代理快速入門。
先決條件
- 一個 Azure 訂閱。 免費創建一個。
- 一個鑄造廠的專案。 如果你需要建立專案,請參考 Create a Microsoft Foundry 專案。 欲了解更多區域可用性資訊,請參閱 Voice Live 總覽文件。
小提示
要使用 Voice Live,你不需要用 Microsoft Foundry 資源部署音訊模型。 Voice Live 是完全管理的,模型會自動為您部署。 欲了解更多模型可用性資訊,請參閱 Voice Live 總覽文件。
試試 Voice Live 在語音互動平台上
要試玩 Voice Live 示範,請遵循以下步驟:
- 前往 Voice Live 功能頁面 ,選擇 在 Playground 中開啟。
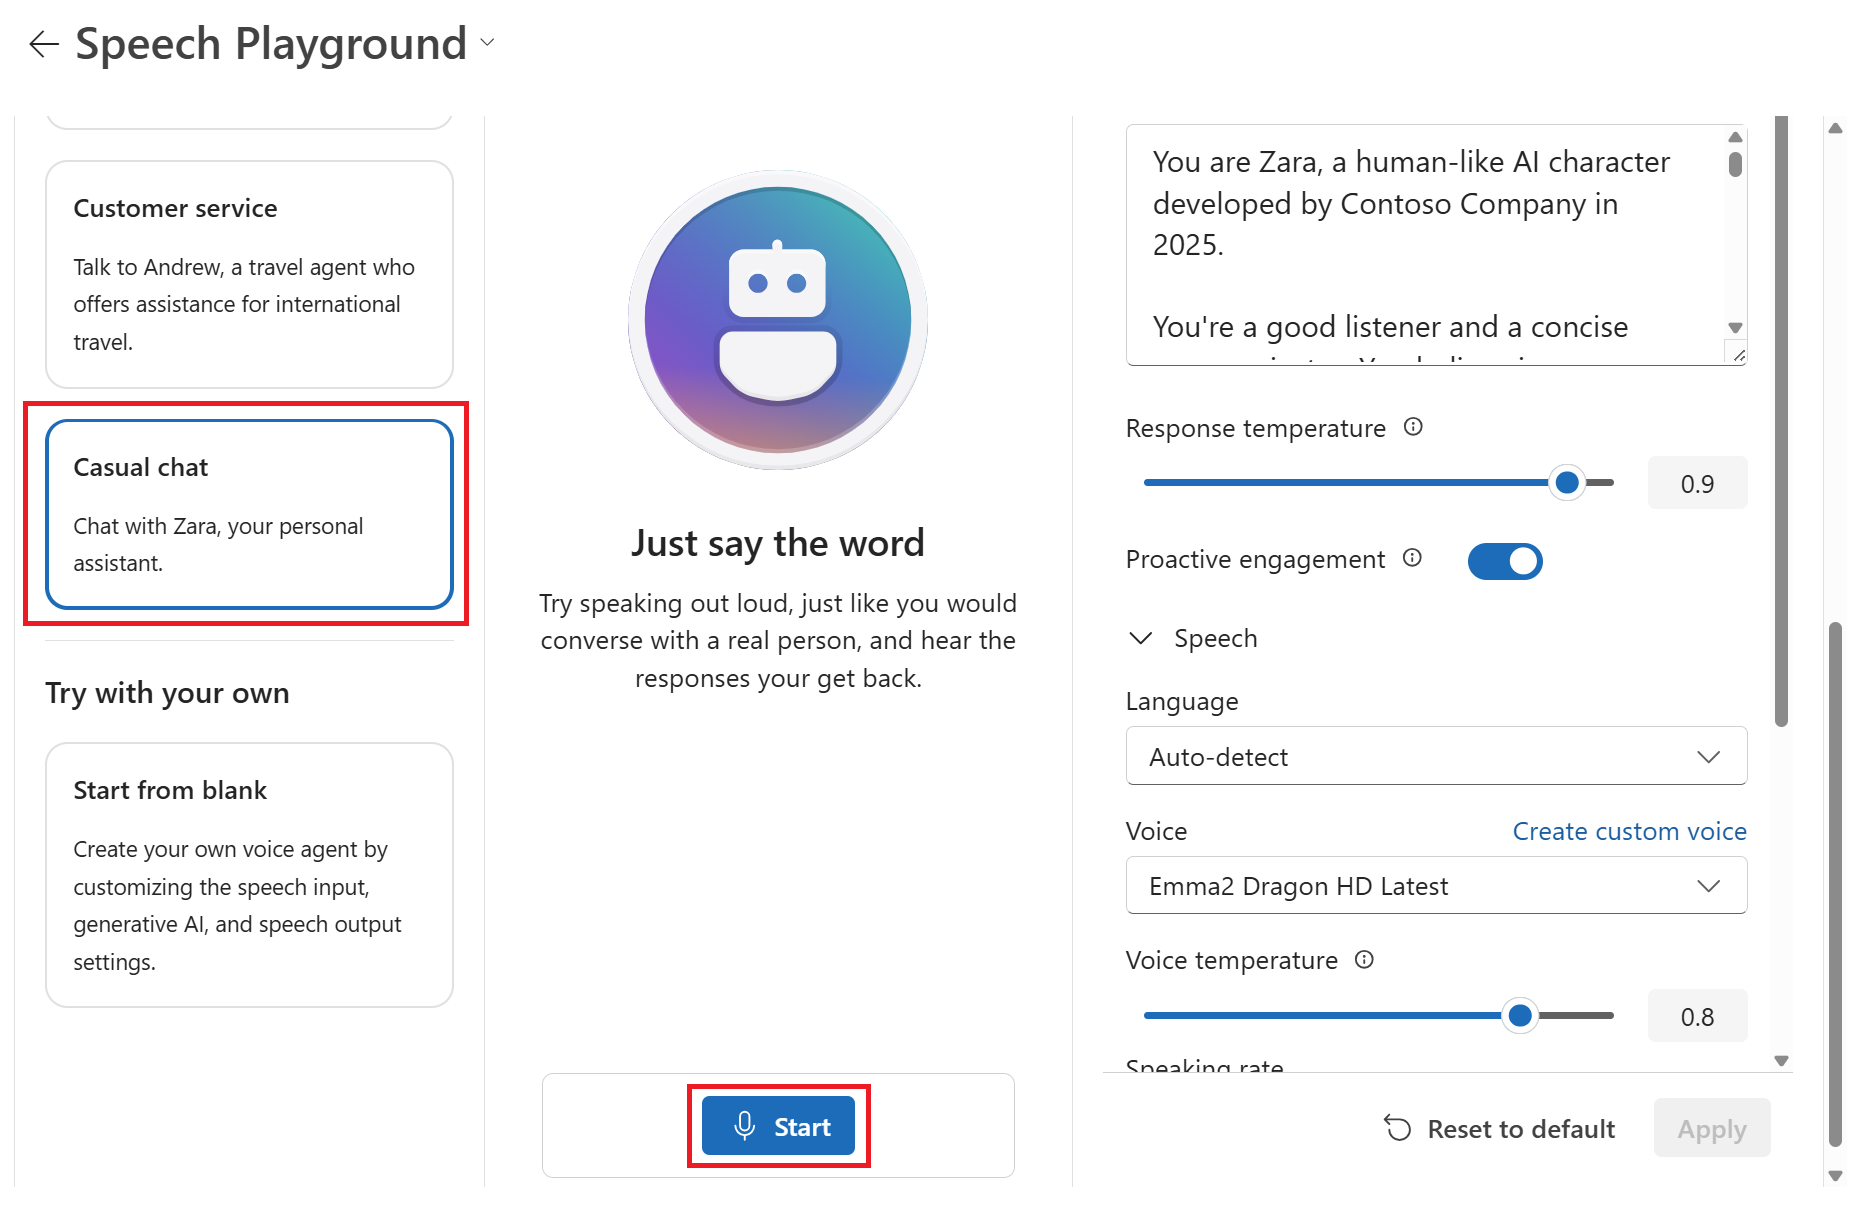
- 使用下拉式功能表選取案例和語音。 選擇性地設定語音代理行為的其他參數。 例如, 主動互動 切換讓客服在對話中先開口。
- 當您準備好時,請選取 [ 開始 ] 以開始使用裝置的麥克風和喇叭與語音代理程式聊天。
- 選取 [結束 ] 以結束聊天會話。
其他 Foundry(新增)功能
以下語音功能可在 Foundry(新)入口網站中提供:


在本文中,你將學習如何使用 Voice Live 和 Microsoft Foundry 模型,採用 VoiceLive SDK for Python。
您會建立並執行應用程式,藉此將內含生成式 AI 模型的 Voice Live 直接使用於即時語音代理程式。
使用模型直接允許為每個會話指定自定義指示(提示),為動態或實驗使用案例提供更多彈性。
當您想要更精細地控制會話參數,或需要經常調整提示或設定,而不需在入口網站中更新代理程式時,最好使用模型。
模型型會話的程式代碼在某些方面比較簡單,因為它不需要管理代理程式標識碼或代理程式特定的設定。
直接模型使用適用於不需要代理程式層級抽象或內建邏輯的案例。
若想改用 Voice Live API 搭配代理,請參閱 Voice Live API 代理快速入門。
先決條件
- 一個 Azure 訂閱。 免費創建一個。
- Python 3.10 或更新版本。 如果你還沒安裝合適的 Python 版本,可以依照 VS Code Python Tutorial 的說明,最簡單地在作業系統上安裝 Python。
- Microsoft Foundry 資源 在支援區域之一建立。 如需區域可用性的詳細資訊,請參閱 區域支援。
小提示
要使用 Voice Live,你不需要用 Microsoft Foundry 資源部署音訊模型。 Voice Live 是完全管理的,模型會自動為您部署。 欲了解更多模型可用性資訊,請參閱 Voice Live 總覽文件。
Microsoft Entra ID 先決條件
建議使用 Microsoft Entra ID 進行無鑰匙認證,您需要:
- 安裝Azure CLI,用於與 Microsoft Entra ID 的無金鑰認證。
- 將
Cognitive Services User角色指派給您的使用者帳戶。 你可以在Azure入口網站的 存取控制(IAM)>新增角色分配下分配角色。
設定
建立新的資料夾
voice-live-quickstart,並使用下列命令移至快速入門資料夾:mkdir voice-live-quickstart && cd voice-live-quickstart建立虛擬環境。 如果你已經安裝了 Python 3.10 或更高版本,可以使用以下指令建立虛擬環境:
啟用 Python 環境意味著當你從命令列執行
python或pip時,接著你會使用應用程式.venv資料夾中的 Python 直譯器。 您可以使用deactivate命令來結束 Python 虛擬環境,並可以稍後視需要重新啟用它。小提示
我們建議你建立並啟用一個新的 Python 環境,用來安裝本教學所需的套件。 請勿將套件安裝到您的全域 Python 安裝中。 安裝 python 套件時,你應該一定要使用虛擬或 conda 環境,否則可能會破壞你的全域 Python 安裝。
建立名為 requirements.txt的檔案。 將下列套件新增至檔案:
azure-ai-voicelive[aiohttp]
pyaudio
python-dotenv
azure-identity
安裝套件:
pip install -r requirements.txt
擷取資源資訊
在您要執行程式代碼的資料夾中,建立名為 .env 的新檔案。
在 檔案中 .env ,新增下列環境變數以進行驗證:
AZURE_VOICELIVE_ENDPOINT=<your_endpoint>
AZURE_VOICELIVE_MODEL=<your_model>
AZURE_VOICELIVE_API_VERSION=2026-04-10
AZURE_VOICELIVE_API_KEY=<your_api_key> # Only required if using API key authentication
將預設值取代為您的實際端點、模型、API 版本和 API 金鑰。
| 變數名稱 | 價值觀 |
|---|---|
AZURE_VOICELIVE_ENDPOINT |
此值可在Azure入口檢視資源時,Keys 與 Endpoint 區塊中找到。 |
AZURE_VOICELIVE_MODEL |
您想要使用的模型。 例如,gpt-4o 或 gpt-realtime-mini。 如需模型可用性的詳細資訊,請參閱 語音即時 API 概觀檔。 |
AZURE_VOICELIVE_API_VERSION |
您想要使用的 API 版本。 例如: 2026-04-10 。 |
開始交談
這個快速入門的範例程式碼使用 Microsoft Entra ID 或 API 金鑰進行驗證。 您可以將指令碼引數設定為您的 API 金鑰或存取權杖。
使用下列程式代碼,建立
voice-live-quickstart.py檔案。# ------------------------------------------------------------------------- # Copyright (c) Microsoft Corporation. All rights reserved. # Licensed under the MIT License. # ------------------------------------------------------------------------- from __future__ import annotations import os import sys import argparse import asyncio import base64 from datetime import datetime import logging import queue import signal from typing import Union, Optional, TYPE_CHECKING, cast from azure.core.credentials import AzureKeyCredential from azure.core.credentials_async import AsyncTokenCredential from azure.identity.aio import AzureCliCredential, DefaultAzureCredential from azure.ai.voicelive.aio import connect from azure.ai.voicelive.models import ( AudioEchoCancellation, AudioNoiseReduction, AzureStandardVoice, InputAudioFormat, Modality, OutputAudioFormat, RequestSession, ServerEventType, ServerVad ) from dotenv import load_dotenv import pyaudio if TYPE_CHECKING: # Only needed for type checking; avoids runtime import issues from azure.ai.voicelive.aio import VoiceLiveConnection ## Change to the directory where this script is located os.chdir(os.path.dirname(os.path.abspath(__file__))) # Environment variable loading load_dotenv('./.env', override=True) # Set up logging ## Add folder for logging if not os.path.exists('logs'): os.makedirs('logs') ## Add timestamp for logfiles timestamp = datetime.now().strftime("%Y-%m-%d_%H-%M-%S") ## Set up logging logging.basicConfig( filename=f'logs/{timestamp}_voicelive.log', filemode="w", format='%(asctime)s:%(name)s:%(levelname)s:%(message)s', level=logging.INFO ) logger = logging.getLogger(__name__) class AudioProcessor: """ Handles real-time audio capture and playback for the voice assistant. Threading Architecture: - Main thread: Event loop and UI - Capture thread: PyAudio input stream reading - Send thread: Async audio data transmission to VoiceLive - Playback thread: PyAudio output stream writing """ loop: asyncio.AbstractEventLoop class AudioPlaybackPacket: """Represents a packet that can be sent to the audio playback queue.""" def __init__(self, seq_num: int, data: Optional[bytes]): self.seq_num = seq_num self.data = data def __init__(self, connection): self.connection = connection self.audio = pyaudio.PyAudio() # Audio configuration - PCM16, 24kHz, mono as specified self.format = pyaudio.paInt16 self.channels = 1 self.rate = 24000 self.chunk_size = 1200 # 50ms # Capture and playback state self.input_stream = None self.playback_queue: queue.Queue[AudioProcessor.AudioPlaybackPacket] = queue.Queue() self.playback_base = 0 self.next_seq_num = 0 self.output_stream: Optional[pyaudio.Stream] = None logger.info("AudioProcessor initialized with 24kHz PCM16 mono audio") def start_capture(self): """Start capturing audio from microphone.""" def _capture_callback( in_data, # data _frame_count, # number of frames _time_info, # dictionary _status_flags): """Audio capture thread - runs in background.""" audio_base64 = base64.b64encode(in_data).decode("utf-8") asyncio.run_coroutine_threadsafe( self.connection.input_audio_buffer.append(audio=audio_base64), self.loop ) return (None, pyaudio.paContinue) if self.input_stream: return # Store the current event loop for use in threads self.loop = asyncio.get_event_loop() try: self.input_stream = self.audio.open( format=self.format, channels=self.channels, rate=self.rate, input=True, frames_per_buffer=self.chunk_size, stream_callback=_capture_callback, ) logger.info("Started audio capture") except Exception: logger.exception("Failed to start audio capture") raise def start_playback(self): """Initialize audio playback system.""" if self.output_stream: return remaining = bytes() def _playback_callback( _in_data, frame_count, # number of frames _time_info, _status_flags): nonlocal remaining frame_count *= pyaudio.get_sample_size(pyaudio.paInt16) out = remaining[:frame_count] remaining = remaining[frame_count:] while len(out) < frame_count: try: packet = self.playback_queue.get_nowait() except queue.Empty: out = out + bytes(frame_count - len(out)) continue except Exception: logger.exception("Error in audio playback") raise if not packet or not packet.data: # None packet indicates end of stream logger.info("End of playback queue.") break if packet.seq_num < self.playback_base: # skip requested # ignore skipped packet and clear remaining if len(remaining) > 0: remaining = bytes() continue num_to_take = frame_count - len(out) out = out + packet.data[:num_to_take] remaining = packet.data[num_to_take:] if len(out) >= frame_count: return (out, pyaudio.paContinue) else: return (out, pyaudio.paComplete) try: self.output_stream = self.audio.open( format=self.format, channels=self.channels, rate=self.rate, output=True, frames_per_buffer=self.chunk_size, stream_callback=_playback_callback ) logger.info("Audio playback system ready") except Exception: logger.exception("Failed to initialize audio playback") raise def _get_and_increase_seq_num(self): seq = self.next_seq_num self.next_seq_num += 1 return seq def queue_audio(self, audio_data: Optional[bytes]) -> None: """Queue audio data for playback.""" self.playback_queue.put( AudioProcessor.AudioPlaybackPacket( seq_num=self._get_and_increase_seq_num(), data=audio_data)) def skip_pending_audio(self): """Skip current audio in playback queue.""" self.playback_base = self._get_and_increase_seq_num() def shutdown(self): """Clean up audio resources.""" if self.input_stream: self.input_stream.stop_stream() self.input_stream.close() self.input_stream = None logger.info("Stopped audio capture") # Inform thread to complete if self.output_stream: self.skip_pending_audio() self.queue_audio(None) self.output_stream.stop_stream() self.output_stream.close() self.output_stream = None logger.info("Stopped audio playback") if self.audio: self.audio.terminate() logger.info("Audio processor cleaned up") class BasicVoiceAssistant: """Basic voice assistant implementing the VoiceLive SDK patterns.""" def __init__( self, endpoint: str, credential: Union[AzureKeyCredential, AsyncTokenCredential], model: str, voice: str, instructions: str, ): self.endpoint = endpoint self.credential = credential self.model = model self.voice = voice self.instructions = instructions self.connection: Optional["VoiceLiveConnection"] = None self.audio_processor: Optional[AudioProcessor] = None self.session_ready = False self._active_response = False self._response_api_done = False async def start(self): """Start the voice assistant session.""" try: logger.info("Connecting to VoiceLive API with model %s", self.model) # Connect to VoiceLive WebSocket API async with connect( endpoint=self.endpoint, credential=self.credential, model=self.model, ) as connection: conn = connection self.connection = conn # Initialize audio processor ap = AudioProcessor(conn) self.audio_processor = ap # Configure session for voice conversation await self._setup_session() # Start audio systems ap.start_playback() logger.info("Voice assistant ready! Start speaking...") print("\n" + "=" * 60) print("🎤 VOICE ASSISTANT READY") print("Start speaking to begin conversation") print("Press Ctrl+C to exit") print("=" * 60 + "\n") # Process events await self._process_events() finally: if self.audio_processor: self.audio_processor.shutdown() async def _setup_session(self): """Configure the VoiceLive session for audio conversation.""" logger.info("Setting up voice conversation session...") # Create voice configuration voice_config: Union[AzureStandardVoice, str] if self.voice.startswith("en-US-") or self.voice.startswith("en-CA-") or "-" in self.voice: # Azure voice voice_config = AzureStandardVoice(name=self.voice) else: # OpenAI voice (alloy, echo, fable, onyx, nova, shimmer) voice_config = self.voice # Create turn detection configuration turn_detection_config = ServerVad( threshold=0.5, prefix_padding_ms=400, silence_duration_ms=500) # Create session configuration session_config = RequestSession( modalities=[Modality.TEXT, Modality.AUDIO], instructions=self.instructions, voice=voice_config, input_audio_format=InputAudioFormat.PCM16, output_audio_format=OutputAudioFormat.PCM16, turn_detection=turn_detection_config, input_audio_echo_cancellation=AudioEchoCancellation(), input_audio_noise_reduction=AudioNoiseReduction(type="azure_deep_noise_suppression"), ) conn = self.connection assert conn is not None, "Connection must be established before setting up session" await conn.session.update(session=session_config) logger.info("Session configuration sent") async def _process_events(self): """Process events from the VoiceLive connection.""" try: conn = self.connection assert conn is not None, "Connection must be established before processing events" async for event in conn: await self._handle_event(event) except Exception: logger.exception("Error processing events") raise async def _handle_event(self, event): """Handle different types of events from VoiceLive.""" logger.debug("Received event: %s", event.type) ap = self.audio_processor conn = self.connection assert ap is not None, "AudioProcessor must be initialized" assert conn is not None, "Connection must be established" if event.type == ServerEventType.SESSION_UPDATED: logger.info("Session ready: %s", event.session.id) self.session_ready = True # Start audio capture once session is ready ap.start_capture() elif event.type == ServerEventType.INPUT_AUDIO_BUFFER_SPEECH_STARTED: logger.info("User started speaking - stopping playback") print("🎤 Listening...") ap.skip_pending_audio() elif event.type == ServerEventType.INPUT_AUDIO_BUFFER_SPEECH_STOPPED: logger.info("🎤 User stopped speaking") print("🤔 Processing...") elif event.type == ServerEventType.RESPONSE_CREATED: logger.info("🤖 Assistant response created") self._active_response = True self._response_api_done = False elif event.type == ServerEventType.RESPONSE_AUDIO_DELTA: logger.debug("Received audio delta") ap.queue_audio(event.delta) elif event.type == ServerEventType.RESPONSE_AUDIO_DONE: logger.info("🤖 Assistant finished speaking") print("🎤 Ready for next input...") elif event.type == ServerEventType.RESPONSE_DONE: logger.info("✅ Response complete") self._active_response = False self._response_api_done = True elif event.type == ServerEventType.ERROR: msg = event.error.message if "Cancellation failed: no active response" in msg: logger.debug("Benign cancellation error: %s", msg) else: logger.error("❌ VoiceLive error: %s", msg) print(f"Error: {msg}") elif event.type == ServerEventType.CONVERSATION_ITEM_CREATED: logger.debug("Conversation item created: %s", event.item.id) else: logger.debug("Unhandled event type: %s", event.type) def parse_arguments(): """Parse command line arguments.""" parser = argparse.ArgumentParser( description="Basic Voice Assistant using Azure VoiceLive SDK", formatter_class=argparse.ArgumentDefaultsHelpFormatter, ) parser.add_argument( "--api-key", help="Azure VoiceLive API key. If not provided, will use AZURE_VOICELIVE_API_KEY environment variable.", type=str, default=os.environ.get("AZURE_VOICELIVE_API_KEY"), ) parser.add_argument( "--endpoint", help="Azure VoiceLive endpoint", type=str, default=os.environ.get("AZURE_VOICELIVE_ENDPOINT", "https://your-resource-name.services.ai.azure.com/"), ) parser.add_argument( "--model", help="VoiceLive model to use", type=str, default=os.environ.get("AZURE_VOICELIVE_MODEL", "gpt-realtime"), ) parser.add_argument( "--voice", help="Voice to use for the assistant. E.g. alloy, echo, fable, en-US-AvaNeural, en-US-GuyNeural", type=str, default=os.environ.get("AZURE_VOICELIVE_VOICE", "en-US-Ava:DragonHDLatestNeural"), ) parser.add_argument( "--instructions", help="System instructions for the AI assistant", type=str, default=os.environ.get( "AZURE_VOICELIVE_INSTRUCTIONS", "You are a helpful AI assistant. Respond naturally and conversationally. " "Keep your responses concise but engaging.", ), ) parser.add_argument( "--use-token-credential", help="Use Azure token credential instead of API key", action="store_true", default=False ) parser.add_argument("--verbose", help="Enable verbose logging", action="store_true") return parser.parse_args() def main(): """Main function.""" args = parse_arguments() # Set logging level if args.verbose: logging.getLogger().setLevel(logging.DEBUG) # Validate credentials if not args.api_key and not args.use_token_credential: print("❌ Error: No authentication provided") print("Please provide an API key using --api-key or set AZURE_VOICELIVE_API_KEY environment variable,") print("or use --use-token-credential for Azure authentication.") sys.exit(1) # Create client with appropriate credential credential: Union[AzureKeyCredential, AsyncTokenCredential] if args.use_token_credential: credential = AzureCliCredential() # or DefaultAzureCredential() if needed logger.info("Using Azure token credential") else: credential = AzureKeyCredential(args.api_key) logger.info("Using API key credential") # Create and start voice assistant assistant = BasicVoiceAssistant( endpoint=args.endpoint, credential=credential, model=args.model, voice=args.voice, instructions=args.instructions, ) # Setup signal handlers for graceful shutdown def signal_handler(_sig, _frame): logger.info("Received shutdown signal") raise KeyboardInterrupt() signal.signal(signal.SIGINT, signal_handler) signal.signal(signal.SIGTERM, signal_handler) # Start the assistant try: asyncio.run(assistant.start()) except KeyboardInterrupt: print("\n👋 Voice assistant shut down. Goodbye!") except Exception as e: print("Fatal Error: ", e) if __name__ == "__main__": # Check audio system try: p = pyaudio.PyAudio() # Check for input devices input_devices = [ i for i in range(p.get_device_count()) if cast(Union[int, float], p.get_device_info_by_index(i).get("maxInputChannels", 0) or 0) > 0 ] # Check for output devices output_devices = [ i for i in range(p.get_device_count()) if cast(Union[int, float], p.get_device_info_by_index(i).get("maxOutputChannels", 0) or 0) > 0 ] p.terminate() if not input_devices: print("❌ No audio input devices found. Please check your microphone.") sys.exit(1) if not output_devices: print("❌ No audio output devices found. Please check your speakers.") sys.exit(1) except Exception as e: print(f"❌ Audio system check failed: {e}") sys.exit(1) print("🎙️ Basic Voice Assistant with Azure VoiceLive SDK") print("=" * 50) # Run the assistant main()請使用以下指令登入 Azure:
az login執行 Python 檔案。
python voice-live-quickstart.py --use-token-credential語音即時 API 會以模型的初始響應開始傳回音訊。 您可以藉由說話來中斷模型。 輸入“Ctrl+C”退出對話。
輸出
腳本的輸出會列印至主控台。 您會看到指出系統狀態的訊息。 音訊會透過喇叭或耳機播放。
============================================================
🎤 VOICE ASSISTANT READY
Start speaking to begin conversation
Press Ctrl+C to exit
============================================================

🎤 Listening...
🤔 Processing...
🎤 Ready for next input...
🎤 Listening...
🤔 Processing...
🎤 Ready for next input...
🎤 Listening...
🤔 Processing...
🎤 Ready for next input...
🎤 Listening...
🤔 Processing...
🎤 Listening...
🎤 Ready for next input...
🤔 Processing...
🎤 Ready for next input...
您執行的文稿會在資料夾中建立名為 <timestamp>_voicelive.log 的 logs 記錄檔。
預設記錄層級會設定為 INFO ,但您可以使用命令列參數 --verbose 執行快速入門,或變更程式碼中的記錄設定,以變更它,如下所示:
logging.basicConfig(
    filename=f'logs/{timestamp}_voicelive.log',
    filemode="w",
    format='%(asctime)s:%(name)s:%(levelname)s:%(message)s',
    level=logging.INFO
)
記錄檔包含語音即時 API 連線的相關信息,包括要求和響應數據。 您可以檢視記錄檔,以查看交談的詳細數據。
2025-10-02 14:47:37,901:__main__:INFO:Using Azure token credential
2025-10-02 14:47:37,901:__main__:INFO:Connecting to VoiceLive API with model gpt-realtime
2025-10-02 14:47:37,901:azure.core.pipeline.policies.http_logging_policy:INFO:Request URL: 'https://login.microsoftonline.com/organizations/v2.0/.well-known/openid-configuration'
Request method: 'GET'
Request headers:
    'User-Agent': 'azsdk-python-identity/1.22.0 Python/3.11.9 (Windows-10-10.0.26200-SP0)'
No body was attached to the request
2025-10-02 14:47:38,057:azure.core.pipeline.policies.http_logging_policy:INFO:Response status: 200
Response headers:
    'Date': 'Thu, 02 Oct 2025 21:47:37 GMT'
    'Content-Type': 'application/json; charset=utf-8'
    'Content-Length': '1641'
    'Connection': 'keep-alive'
    'Cache-Control': 'max-age=86400, private'
    'Strict-Transport-Security': 'REDACTED'
    'X-Content-Type-Options': 'REDACTED'
    'Access-Control-Allow-Origin': 'REDACTED'
    'Access-Control-Allow-Methods': 'REDACTED'
    'P3P': 'REDACTED'
    'x-ms-request-id': 'f81adfa1-8aa3-4ab6-a7b8-908f411e0d00'
    'x-ms-ests-server': 'REDACTED'
    'x-ms-srs': 'REDACTED'
    'Content-Security-Policy-Report-Only': 'REDACTED'
    'Cross-Origin-Opener-Policy-Report-Only': 'REDACTED'
    'Reporting-Endpoints': 'REDACTED'
    'X-XSS-Protection': 'REDACTED'
    'Set-Cookie': 'REDACTED'
    'X-Cache': 'REDACTED'
2025-10-02 14:47:42,105:azure.core.pipeline.policies.http_logging_policy:INFO:Request URL: 'https://login.microsoftonline.com/organizations/oauth2/v2.0/token'
Request method: 'POST'
Request headers:
    'Accept': 'application/json'
    'x-client-sku': 'REDACTED'
    'x-client-ver': 'REDACTED'
    'x-client-os': 'REDACTED'
    'x-ms-lib-capability': 'REDACTED'
    'client-request-id': 'REDACTED'
    'x-client-current-telemetry': 'REDACTED'
    'x-client-last-telemetry': 'REDACTED'
    'X-AnchorMailbox': 'REDACTED'
    'User-Agent': 'azsdk-python-identity/1.22.0 Python/3.11.9 (Windows-10-10.0.26200-SP0)'
A body is sent with the request
2025-10-02 14:47:42,466:azure.core.pipeline.policies.http_logging_policy:INFO:Response status: 200
Response headers:
    'Date': 'Thu, 02 Oct 2025 21:47:42 GMT'
    'Content-Type': 'application/json; charset=utf-8'
    'Content-Length': '6587'
    'Connection': 'keep-alive'
    'Cache-Control': 'no-store, no-cache'
    'Pragma': 'no-cache'
    'Expires': '-1'
    'Strict-Transport-Security': 'REDACTED'
    'X-Content-Type-Options': 'REDACTED'
    'P3P': 'REDACTED'
    'client-request-id': 'REDACTED'
    'x-ms-request-id': '2e82e728-22c0-4568-b3ed-f00ec79a2500'
    'x-ms-ests-server': 'REDACTED'
    'x-ms-clitelem': 'REDACTED'
    'x-ms-srs': 'REDACTED'
    'Content-Security-Policy-Report-Only': 'REDACTED'
    'Cross-Origin-Opener-Policy-Report-Only': 'REDACTED'
    'Reporting-Endpoints': 'REDACTED'
    'X-XSS-Protection': 'REDACTED'
    'Set-Cookie': 'REDACTED'
    'X-Cache': 'REDACTED'
2025-10-02 14:47:42,467:azure.identity._internal.interactive:INFO:InteractiveBrowserCredential.get_token succeeded
2025-10-02 14:47:42,884:__main__:INFO:AudioProcessor initialized with 24kHz PCM16 mono audio
2025-10-02 14:47:42,884:__main__:INFO:Setting up voice conversation session...
2025-10-02 14:47:42,887:__main__:INFO:Session configuration sent
2025-10-02 14:47:42,943:__main__:INFO:Audio playback system ready
2025-10-02 14:47:42,943:__main__:INFO:Voice assistant ready! Start speaking...
2025-10-02 14:47:42,975:__main__:INFO:Session ready: sess_CMLRGjWnakODcHn583fXf
2025-10-02 14:47:42,994:__main__:INFO:Started audio capture
2025-10-02 14:47:47,513:__main__:INFO:\U0001f3a4 User started speaking - stopping playback
2025-10-02 14:47:47,593:__main__:INFO:Stopped audio playback
2025-10-02 14:47:51,757:__main__:INFO:\U0001f3a4 User stopped speaking
2025-10-02 14:47:51,813:__main__:INFO:Audio playback system ready
2025-10-02 14:47:51,816:__main__:INFO:\U0001f916 Assistant response created
2025-10-02 14:47:58,009:__main__:INFO:\U0001f916 Assistant finished speaking
2025-10-02 14:47:58,009:__main__:INFO:\u2705 Response complete
2025-10-02 14:48:07,309:__main__:INFO:Received shutdown signal
在本文中,您將學習如何使用 VoiceLive SDK for C# 搭配 Microsoft Foundry 模型進行語音直播。
您會建立並執行應用程式,藉此將內含生成式 AI 模型的 Voice Live 直接使用於即時語音代理程式。
使用模型直接允許為每個會話指定自定義指示(提示),為動態或實驗使用案例提供更多彈性。
當您想要更精細地控制會話參數,或需要經常調整提示或設定,而不需在入口網站中更新代理程式時,最好使用模型。
模型型會話的程式代碼在某些方面比較簡單,因為它不需要管理代理程式標識碼或代理程式特定的設定。
直接模型使用適用於不需要代理程式層級抽象或內建邏輯的案例。
若想改用 Voice Live API 搭配代理,請參閱 Voice Live API 代理快速入門。
先決條件
- 一個 Azure 訂閱。 免費創建一個。
- Microsoft Foundry 資源 在支援區域之一建立。 欲了解更多區域可用性資訊,請參閱 Voice Live 總覽文件。
- .NET SDK 版本 6.0 或更新版本。
開始語音對話
請遵循下列步驟來建立主控台應用程式並安裝語音 SDK。
在您要新專案的資料夾中開啟命令提示字元視窗。 執行此指令即可建立帶有 .NET CLI 的主控台應用程式。
dotnet new console此指令會在專案目錄中建立 Program.cs 檔案。
在你的新專案中使用 .NET CLI 安裝 Voice Live SDK、Azure Identity 和 Naudio。
dotnet add package Azure.AI.VoiceLive
dotnet add package Azure.Identity
dotnet add package NAudio
dotnet add package System.CommandLine --version 2.0.0-beta4.22272.1
dotnet add package Microsoft.Extensions.Configuration.Json
dotnet add package Microsoft.Extensions.Configuration.EnvironmentVariables
dotnet add package Microsoft.Extensions.Logging.Console
在您要執行程式代碼的資料夾中,建立名為
appsettings.json的新檔案。 在該檔案中,新增下列 JSON 內容:{ "VoiceLive": { "ApiKey": "your-api-key-here", "Endpoint": "https://your-resource-name.services.ai.azure.com/", "Model": "gpt-realtime", "Voice": "en-US-Ava:DragonHDLatestNeural", "Instructions": "You are a helpful AI assistant. Respond naturally and conversationally. Keep your responses concise but engaging." }, "Logging": { "LogLevel": { "Default": "Information", "Azure.AI.VoiceLive": "Debug" } } }這個快速入門的範例程式碼使用 Microsoft Entra ID 或 API 金鑰進行驗證。 您可以將指令碼引數設定為您的 API 金鑰或存取權杖。 我們建議使用 Microsoft Entra ID 認證,而不是設定
ApiKey值,然後用--use-token-credential參數執行快速啟動。將
ApiKey值(可選)替換為你的 Foundry API 鍵,並將Endpoint值替換為你的資源端點。 您也可以視需要變更 [模型]、[語音] 和 [指示] 值。在檔案
csharp.csproj中新增下列資訊以連接 appsettings.json:<ItemGroup> <None Update="appsettings.json"> <CopyToOutputDirectory>PreserveNewest</CopyToOutputDirectory> </None> </ItemGroup>以下列程式碼取代
Program.cs的內容。 此程式碼使用其中一個內建模型建立基本語音代理程式。// Copyright (c) Microsoft Corporation. All rights reserved. // Licensed under the MIT License. using System; using System.CommandLine; using System.Threading; using System.Threading.Tasks; using System.Threading.Channels; using System.Collections.Generic; using Azure.AI.VoiceLive; using Azure.Core; using Azure.Core.Pipeline; using Azure.Identity; using Microsoft.Extensions.Configuration; using Microsoft.Extensions.Logging; using NAudio.Wave; namespace Azure.AI.VoiceLive.Samples { /// <summary> /// FILE: Program.cs (Consolidated) /// </summary> /// <remarks> /// DESCRIPTION: /// This consolidated sample demonstrates the fundamental capabilities of the VoiceLive SDK by creating /// a basic voice assistant that can engage in natural conversation with proper interruption /// handling. This serves as the foundational example that showcases the core value /// proposition of unified speech-to-speech interaction. /// /// All necessary code has been consolidated into this single file for easy distribution and execution. /// /// USAGE: /// dotnet run /// /// Set the environment variables with your own values before running the sample: /// 1) AZURE_VOICELIVE_API_KEY - The Azure VoiceLive API key /// 2) AZURE_VOICELIVE_ENDPOINT - The Azure VoiceLive endpoint /// /// Or update appsettings.json with your values. /// /// REQUIREMENTS: /// - Azure.AI.VoiceLive /// - Azure.Identity /// - NAudio (for audio capture and playback) /// - Microsoft.Extensions.Configuration /// - System.CommandLine /// - System.Threading.Channels /// </remarks> public class Program { /// <summary> /// Main entry point for the Voice Assistant sample. /// </summary> /// <param name="args"></param> /// <returns></returns> public static async Task<int> Main(string[] args) { // Create command line interface var rootCommand = CreateRootCommand(); return await rootCommand.InvokeAsync(args).ConfigureAwait(false); } private static RootCommand CreateRootCommand() { var rootCommand = new RootCommand("Basic Voice Assistant using Azure VoiceLive SDK"); var apiKeyOption = new Option<string?>( "--api-key", "Azure VoiceLive API key. If not provided, will use AZURE_VOICELIVE_API_KEY environment variable."); var endpointOption = new Option<string>( "--endpoint", () => "wss://api.voicelive.com/v1", "Azure VoiceLive endpoint"); var modelOption = new Option<string>( "--model", () => "gpt-4o", "VoiceLive model to use"); var voiceOption = new Option<string>( "--voice", () => "en-US-AvaNeural", "Voice to use for the assistant"); var instructionsOption = new Option<string>( "--instructions", () => "You are a helpful AI assistant. Respond naturally and conversationally. Keep your responses concise but engaging.", "System instructions for the AI assistant"); var useTokenCredentialOption = new Option<bool>( "--use-token-credential", "Use Azure token credential instead of API key"); var verboseOption = new Option<bool>( "--verbose", "Enable verbose logging"); rootCommand.AddOption(apiKeyOption); rootCommand.AddOption(endpointOption); rootCommand.AddOption(modelOption); rootCommand.AddOption(voiceOption); rootCommand.AddOption(instructionsOption); rootCommand.AddOption(useTokenCredentialOption); rootCommand.AddOption(verboseOption); rootCommand.SetHandler(async ( string? apiKey, string endpoint, string model, string voice, string instructions, bool useTokenCredential, bool verbose) => { await RunVoiceAssistantAsync(apiKey, endpoint, model, voice, instructions, useTokenCredential, verbose).ConfigureAwait(false); }, apiKeyOption, endpointOption, modelOption, voiceOption, instructionsOption, useTokenCredentialOption, verboseOption); return rootCommand; } private static async Task RunVoiceAssistantAsync( string? apiKey, string endpoint, string model, string voice, string instructions, bool useTokenCredential, bool verbose) { // Setup configuration var configuration = new ConfigurationBuilder() .AddJsonFile("appsettings.json", optional: true) .AddEnvironmentVariables() .Build(); // Override with command line values if provided apiKey ??= configuration["VoiceLive:ApiKey"] ?? Environment.GetEnvironmentVariable("AZURE_VOICELIVE_API_KEY"); endpoint = configuration["VoiceLive:Endpoint"] ?? endpoint; model = configuration["VoiceLive:Model"] ?? model; voice = configuration["VoiceLive:Voice"] ?? voice; instructions = configuration["VoiceLive:Instructions"] ?? instructions; // Setup logging using var loggerFactory = LoggerFactory.Create(builder => { builder.AddConsole(); if (verbose) { builder.SetMinimumLevel(LogLevel.Debug); } else { builder.SetMinimumLevel(LogLevel.Information); } }); var logger = loggerFactory.CreateLogger<Program>(); // Validate credentials if (string.IsNullOrEmpty(apiKey) && !useTokenCredential) { Console.WriteLine("❌ Error: No authentication provided"); Console.WriteLine("Please provide an API key using --api-key or set AZURE_VOICELIVE_API_KEY environment variable,"); Console.WriteLine("or use --use-token-credential for Azure authentication."); return; } // Check audio system before starting if (!CheckAudioSystem(logger)) { return; } try { // Create client with appropriate credential VoiceLiveClient client; if (useTokenCredential) { var tokenCredential = new DefaultAzureCredential(); client = new VoiceLiveClient(new Uri(endpoint), tokenCredential, new VoiceLiveClientOptions()); logger.LogInformation("Using Azure token credential"); } else { var keyCredential = new Azure.AzureKeyCredential(apiKey!); client = new VoiceLiveClient(new Uri(endpoint), keyCredential, new VoiceLiveClientOptions()); logger.LogInformation("Using API key credential"); } // Create and start voice assistant using var assistant = new BasicVoiceAssistant( client, model, voice, instructions, loggerFactory); // Setup cancellation token for graceful shutdown using var cancellationTokenSource = new CancellationTokenSource(); Console.CancelKeyPress += (sender, e) => { e.Cancel = true; logger.LogInformation("Received shutdown signal"); cancellationTokenSource.Cancel(); }; // Start the assistant await assistant.StartAsync(cancellationTokenSource.Token).ConfigureAwait(false); } catch (OperationCanceledException) { Console.WriteLine("\n👋 Voice assistant shut down. Goodbye!"); } catch (Exception ex) { logger.LogError(ex, "Fatal error"); Console.WriteLine($"❌ Error: {ex.Message}"); } } private static bool CheckAudioSystem(ILogger logger) { try { // Try input (default device) using (var waveIn = new WaveInEvent { WaveFormat = new WaveFormat(24000, 16, 1), BufferMilliseconds = 50 }) { // Start/Stop to force initialization and surface any device errors waveIn.DataAvailable += (_, __) => { }; waveIn.StartRecording(); waveIn.StopRecording(); } // Try output (default device) var buffer = new BufferedWaveProvider(new WaveFormat(24000, 16, 1)) { BufferDuration = TimeSpan.FromMilliseconds(200) }; using (var waveOut = new WaveOutEvent { DesiredLatency = 100 }) { waveOut.Init(buffer); // Playing isn't strictly required to validate a device, but it's safe waveOut.Play(); waveOut.Stop(); } logger.LogInformation("Audio system check passed (default input/output initialized)."); return true; } catch (Exception ex) { Console.WriteLine($"❌ Audio system check failed: {ex.Message}"); return false; } } } /// <summary> /// Basic voice assistant implementing the VoiceLive SDK patterns. ///</summary> /// <remarks> /// This sample now demonstrates some of the new convenience methods added to the VoiceLive SDK: /// - ClearStreamingAudioAsync() - Clears all input audio currently being streamed /// - CancelResponseAsync() - Cancels the current response generation (existing method) /// - ConfigureSessionAsync() - Configures session options (existing method) /// /// Additional convenience methods available but not shown in this sample: /// - StartAudioTurnAsync() / EndAudioTurnAsync() / CancelAudioTurnAsync() - Audio turn management /// - AppendAudioToTurnAsync() - Append audio data to an ongoing turn /// - ConnectAvatarAsync() - Connect avatar with SDP for media negotiation /// /// These methods provide a more developer-friendly API similar to the OpenAI SDK, /// eliminating the need to manually construct and populate ClientEvent classes. /// </remarks> public class BasicVoiceAssistant : IDisposable { private readonly VoiceLiveClient _client; private readonly string _model; private readonly string _voice; private readonly string _instructions; private readonly ILogger<BasicVoiceAssistant> _logger; private readonly ILoggerFactory _loggerFactory; private VoiceLiveSession? _session; private AudioProcessor? _audioProcessor; private bool _disposed; // Tracks whether an assistant response is currently active (created and not yet completed) private bool _responseActive; // Tracks whether the assistant can still cancel the current response (between ResponseCreated and ResponseDone) private bool _canCancelResponse; /// <summary> /// Initializes a new instance of the BasicVoiceAssistant class. /// </summary> /// <param name="client">The VoiceLive client.</param> /// <param name="model">The model to use.</param> /// <param name="voice">The voice to use.</param> /// <param name="instructions">The system instructions.</param> /// <param name="loggerFactory">Logger factory for creating loggers.</param> public BasicVoiceAssistant( VoiceLiveClient client, string model, string voice, string instructions, ILoggerFactory loggerFactory) { _client = client ?? throw new ArgumentNullException(nameof(client)); _model = model ?? throw new ArgumentNullException(nameof(model)); _voice = voice ?? throw new ArgumentNullException(nameof(voice)); _instructions = instructions ?? throw new ArgumentNullException(nameof(instructions)); _loggerFactory = loggerFactory ?? throw new ArgumentNullException(nameof(loggerFactory)); _logger = loggerFactory.CreateLogger<BasicVoiceAssistant>(); } /// <summary> /// Start the voice assistant session. /// </summary> /// <param name="cancellationToken">Cancellation token for stopping the session.</param> public async Task StartAsync(CancellationToken cancellationToken = default) { try { _logger.LogInformation("Connecting to VoiceLive API with model {Model}", _model); // Start VoiceLive session _session = await _client.StartSessionAsync(_model, cancellationToken).ConfigureAwait(false); // Initialize audio processor _audioProcessor = new AudioProcessor(_session, _loggerFactory.CreateLogger<AudioProcessor>()); // Configure session for voice conversation await SetupSessionAsync(cancellationToken).ConfigureAwait(false); // Start audio systems await _audioProcessor.StartPlaybackAsync().ConfigureAwait(false); await _audioProcessor.StartCaptureAsync().ConfigureAwait(false); _logger.LogInformation("Voice assistant ready! Start speaking..."); Console.WriteLine(); Console.WriteLine("=" + new string('=', 59)); Console.WriteLine("🎤 VOICE ASSISTANT READY"); Console.WriteLine("Start speaking to begin conversation"); Console.WriteLine("Press Ctrl+C to exit"); Console.WriteLine("=" + new string('=', 59)); Console.WriteLine(); // Process events await ProcessEventsAsync(cancellationToken).ConfigureAwait(false); } catch (OperationCanceledException) { _logger.LogInformation("Received cancellation signal, shutting down..."); } catch (Exception ex) { _logger.LogError(ex, "Connection error"); throw; } finally { // Cleanup if (_audioProcessor != null) { await _audioProcessor.CleanupAsync().ConfigureAwait(false); } } } /// <summary> /// Configure the VoiceLive session for audio conversation. /// </summary> private async Task SetupSessionAsync(CancellationToken cancellationToken) { _logger.LogInformation("Setting up voice conversation session..."); // Azure voice var azureVoice = new AzureStandardVoice(_voice); // Create strongly typed turn detection configuration var turnDetectionConfig = new ServerVadTurnDetection { Threshold = 0.5f, PrefixPadding = TimeSpan.FromMilliseconds(400), SilenceDuration = TimeSpan.FromMilliseconds(500) }; // Create conversation session options var sessionOptions = new VoiceLiveSessionOptions { InputAudioEchoCancellation = new AudioEchoCancellation(), Model = _model, Instructions = _instructions, Voice = azureVoice, InputAudioFormat = InputAudioFormat.Pcm16, OutputAudioFormat = OutputAudioFormat.Pcm16, TurnDetection = turnDetectionConfig }; // Ensure modalities include audio sessionOptions.Modalities.Clear(); sessionOptions.Modalities.Add(InteractionModality.Text); sessionOptions.Modalities.Add(InteractionModality.Audio); await _session!.ConfigureSessionAsync(sessionOptions, cancellationToken).ConfigureAwait(false); _logger.LogInformation("Session configuration sent"); } /// <summary> /// Process events from the VoiceLive session. /// </summary> private async Task ProcessEventsAsync(CancellationToken cancellationToken) { try { await foreach (SessionUpdate serverEvent in _session!.GetUpdatesAsync(cancellationToken).ConfigureAwait(false)) { await HandleSessionUpdateAsync(serverEvent, cancellationToken).ConfigureAwait(false); } } catch (OperationCanceledException) { _logger.LogInformation("Event processing cancelled"); } catch (Exception ex) { _logger.LogError(ex, "Error processing events"); throw; } } /// <summary> /// Handle different types of server events from VoiceLive. /// </summary> private async Task HandleSessionUpdateAsync(SessionUpdate serverEvent, CancellationToken cancellationToken) { _logger.LogDebug("Received event: {EventType}", serverEvent.GetType().Name); switch (serverEvent) { case SessionUpdateSessionCreated sessionCreated: await HandleSessionCreatedAsync(sessionCreated, cancellationToken).ConfigureAwait(false); break; case SessionUpdateSessionUpdated sessionUpdated: _logger.LogInformation("Session updated successfully"); // Start audio capture once session is ready if (_audioProcessor != null) { await _audioProcessor.StartCaptureAsync().ConfigureAwait(false); } break; case SessionUpdateInputAudioBufferSpeechStarted speechStarted: _logger.LogInformation("🎤 User started speaking - stopping playback"); Console.WriteLine("🎤 Listening..."); // Stop current assistant audio playback (interruption handling) if (_audioProcessor != null) { await _audioProcessor.StopPlaybackAsync().ConfigureAwait(false); } // Only attempt cancellation / clearing if a response is active and cancellable if (_responseActive && _canCancelResponse) { // Cancel any ongoing response try { await _session!.CancelResponseAsync(cancellationToken).ConfigureAwait(false); _logger.LogInformation("🛑 Active response cancelled due to user barge-in"); } catch (Exception ex) { if (ex.Message.Contains("no active response", StringComparison.OrdinalIgnoreCase)) { _logger.LogDebug("Cancellation benign: response already completed"); } else { _logger.LogWarning(ex, "Response cancellation failed during barge-in"); } } // Clear any streaming audio still in transit try { await _session!.ClearStreamingAudioAsync(cancellationToken).ConfigureAwait(false); _logger.LogInformation("✨ Cleared streaming audio after cancellation"); } catch (Exception ex) { _logger.LogDebug(ex, "ClearStreamingAudio call failed (may not be supported in all scenarios)"); } } else { _logger.LogDebug("No active/cancellable response during barge-in; skipping cancellation"); } break; case SessionUpdateInputAudioBufferSpeechStopped speechStopped: _logger.LogInformation("🎤 User stopped speaking"); Console.WriteLine("🤔 Processing..."); // Restart playback system for response if (_audioProcessor != null) { await _audioProcessor.StartPlaybackAsync().ConfigureAwait(false); } break; case SessionUpdateResponseCreated responseCreated: _logger.LogInformation("🤖 Assistant response created"); _responseActive = true; _canCancelResponse = true; break; case SessionUpdateResponseAudioDelta audioDelta: // Stream audio response to speakers _logger.LogDebug("Received audio delta"); if (audioDelta.Delta != null && _audioProcessor != null) { byte[] audioData = audioDelta.Delta.ToArray(); await _audioProcessor.QueueAudioAsync(audioData).ConfigureAwait(false); } break; case SessionUpdateResponseAudioDone audioDone: _logger.LogInformation("🤖 Assistant finished speaking"); Console.WriteLine("🎤 Ready for next input..."); break; case SessionUpdateResponseDone responseDone: _logger.LogInformation("✅ Response complete"); _responseActive = false; _canCancelResponse = false; break; case SessionUpdateError errorEvent: _logger.LogError("❌ VoiceLive error: {ErrorMessage}", errorEvent.Error?.Message); Console.WriteLine($"Error: {errorEvent.Error?.Message}"); _responseActive = false; _canCancelResponse = false; break; default: _logger.LogDebug("Unhandled event type: {EventType}", serverEvent.GetType().Name); break; } } /// <summary> /// Handle session created event. /// </summary> private async Task HandleSessionCreatedAsync(SessionUpdateSessionCreated sessionCreated, CancellationToken cancellationToken) { _logger.LogInformation("Session ready: {SessionId}", sessionCreated.Session?.Id); // Start audio capture once session is ready if (_audioProcessor != null) { await _audioProcessor.StartCaptureAsync().ConfigureAwait(false); } } /// <summary> /// Dispose of resources. /// </summary> public void Dispose() { if (_disposed) return; _audioProcessor?.Dispose(); _session?.Dispose(); _disposed = true; } } /// <summary> /// Handles real-time audio capture and playback for the voice assistant. /// /// This processor demonstrates some of the new VoiceLive SDK convenience methods: /// - Uses existing SendInputAudioAsync() method for audio streaming /// - Shows how convenience methods simplify audio operations /// /// Additional convenience methods available in the SDK: /// - StartAudioTurnAsync() / AppendAudioToTurnAsync() / EndAudioTurnAsync() - Audio turn management /// - ClearStreamingAudioAsync() - Clear all streaming audio /// - ConnectAvatarAsync() - Avatar connection with SDP /// /// Threading Architecture: /// - Main thread: Event loop and UI /// - Capture thread: NAudio input stream reading /// - Send thread: Async audio data transmission to VoiceLive /// - Playback thread: NAudio output stream writing /// </summary> public class AudioProcessor : IDisposable { private readonly VoiceLiveSession _session; private readonly ILogger<AudioProcessor> _logger; // Audio configuration - PCM16, 24kHz, mono as specified private const int SampleRate = 24000; private const int Channels = 1; private const int BitsPerSample = 16; // NAudio components private WaveInEvent? _waveIn; private WaveOutEvent? _waveOut; private BufferedWaveProvider? _playbackBuffer; // Audio capture and playback state private bool _isCapturing; private bool _isPlaying; // Audio streaming channels private readonly Channel<byte[]> _audioSendChannel; private readonly Channel<byte[]> _audioPlaybackChannel; private readonly ChannelWriter<byte[]> _audioSendWriter; private readonly ChannelReader<byte[]> _audioSendReader; private readonly ChannelWriter<byte[]> _audioPlaybackWriter; private readonly ChannelReader<byte[]> _audioPlaybackReader; // Background tasks private Task? _audioSendTask; private Task? _audioPlaybackTask; private readonly CancellationTokenSource _cancellationTokenSource; private CancellationTokenSource _playbackCancellationTokenSource; /// <summary> /// Initializes a new instance of the AudioProcessor class. /// </summary> /// <param name="session">The VoiceLive session for audio communication.</param> /// <param name="logger">Logger for diagnostic information.</param> public AudioProcessor(VoiceLiveSession session, ILogger<AudioProcessor> logger) { _session = session ?? throw new ArgumentNullException(nameof(session)); _logger = logger ?? throw new ArgumentNullException(nameof(logger)); // Create unbounded channels for audio data _audioSendChannel = Channel.CreateUnbounded<byte[]>(); _audioSendWriter = _audioSendChannel.Writer; _audioSendReader = _audioSendChannel.Reader; _audioPlaybackChannel = Channel.CreateUnbounded<byte[]>(); _audioPlaybackWriter = _audioPlaybackChannel.Writer; _audioPlaybackReader = _audioPlaybackChannel.Reader; _cancellationTokenSource = new CancellationTokenSource(); _playbackCancellationTokenSource = new CancellationTokenSource(); _logger.LogInformation("AudioProcessor initialized with {SampleRate}Hz PCM16 mono audio", SampleRate); } /// <summary> /// Start capturing audio from microphone. /// </summary> public Task StartCaptureAsync() { if (_isCapturing) return Task.CompletedTask; _isCapturing = true; try { _waveIn = new WaveInEvent { WaveFormat = new WaveFormat(SampleRate, BitsPerSample, Channels), BufferMilliseconds = 50 // 50ms buffer for low latency }; _waveIn.DataAvailable += OnAudioDataAvailable; _waveIn.RecordingStopped += OnRecordingStopped; _waveIn.DeviceNumber = 0; _waveIn.StartRecording(); // Start audio send task _audioSendTask = ProcessAudioSendAsync(_cancellationTokenSource.Token); _logger.LogInformation("Started audio capture"); return Task.CompletedTask; } catch (Exception ex) { _logger.LogError(ex, "Failed to start audio capture"); _isCapturing = false; throw; } } /// <summary> /// Stop capturing audio. /// </summary> public async Task StopCaptureAsync() { if (!_isCapturing) return; _isCapturing = false; if (_waveIn != null) { _waveIn.StopRecording(); _waveIn.DataAvailable -= OnAudioDataAvailable; _waveIn.RecordingStopped -= OnRecordingStopped; _waveIn.Dispose(); _waveIn = null; } // Complete the send channel and wait for the send task _audioSendWriter.TryComplete(); if (_audioSendTask != null) { await _audioSendTask.ConfigureAwait(false); _audioSendTask = null; } _logger.LogInformation("Stopped audio capture"); } /// <summary> /// Initialize audio playback system. /// </summary> public Task StartPlaybackAsync() { if (_isPlaying) return Task.CompletedTask; _isPlaying = true; try { _waveOut = new WaveOutEvent { DesiredLatency = 100 // 100ms latency }; _playbackBuffer = new BufferedWaveProvider(new WaveFormat(SampleRate, BitsPerSample, Channels)) { BufferDuration = TimeSpan.FromSeconds(10), // 10 second buffer DiscardOnBufferOverflow = true }; _waveOut.Init(_playbackBuffer); _waveOut.Play(); _playbackCancellationTokenSource = new CancellationTokenSource(); // Start audio playback task _audioPlaybackTask = ProcessAudioPlaybackAsync(); _logger.LogInformation("Audio playback system ready"); return Task.CompletedTask; } catch (Exception ex) { _logger.LogError(ex, "Failed to initialize audio playback"); _isPlaying = false; throw; } } /// <summary> /// Stop audio playback and clear buffer. /// </summary> public async Task StopPlaybackAsync() { if (!_isPlaying) return; _isPlaying = false; // Clear the playback channel while (_audioPlaybackReader.TryRead(out _)) { } if (_playbackBuffer != null) { _playbackBuffer.ClearBuffer(); } if (_waveOut != null) { _waveOut.Stop(); _waveOut.Dispose(); _waveOut = null; } _playbackBuffer = null; // Complete the playback channel and wait for the playback task _playbackCancellationTokenSource.Cancel(); if (_audioPlaybackTask != null) { await _audioPlaybackTask.ConfigureAwait(false); _audioPlaybackTask = null; } _logger.LogInformation("Stopped audio playback"); } /// <summary> /// Queue audio data for playback. /// </summary> /// <param name="audioData">The audio data to queue.</param> public async Task QueueAudioAsync(byte[] audioData) { if (_isPlaying && audioData.Length > 0) { await _audioPlaybackWriter.WriteAsync(audioData).ConfigureAwait(false); } } /// <summary> /// Event handler for audio data available from microphone. /// </summary> private void OnAudioDataAvailable(object? sender, WaveInEventArgs e) { if (_isCapturing && e.BytesRecorded > 0) { byte[] audioData = new byte[e.BytesRecorded]; Array.Copy(e.Buffer, 0, audioData, 0, e.BytesRecorded); // Queue audio data for sending (non-blocking) if (!_audioSendWriter.TryWrite(audioData)) { _logger.LogWarning("Failed to queue audio data for sending - channel may be full"); } } } /// <summary> /// Event handler for recording stopped. /// </summary> private void OnRecordingStopped(object? sender, StoppedEventArgs e) { if (e.Exception != null) { _logger.LogError(e.Exception, "Audio recording stopped due to error"); } } /// <summary> /// Background task to process audio data and send to VoiceLive service. /// </summary> private async Task ProcessAudioSendAsync(CancellationToken cancellationToken) { try { await foreach (byte[] audioData in _audioSendReader.ReadAllAsync(cancellationToken).ConfigureAwait(false)) { if (cancellationToken.IsCancellationRequested) break; try { // Send audio data directly to the session using the convenience method // This demonstrates the existing SendInputAudioAsync convenience method // Other available methods: StartAudioTurnAsync, AppendAudioToTurnAsync, EndAudioTurnAsync await _session.SendInputAudioAsync(audioData, cancellationToken).ConfigureAwait(false); } catch (Exception ex) { _logger.LogError(ex, "Error sending audio data to VoiceLive"); // Continue processing other audio data } } } catch (OperationCanceledException) { // Expected when cancellation is requested } catch (Exception ex) { _logger.LogError(ex, "Error in audio send processing"); } } /// <summary> /// Background task to process audio playback. /// </summary> private async Task ProcessAudioPlaybackAsync() { try { CancellationTokenSource combinedTokenSource = CancellationTokenSource.CreateLinkedTokenSource(_playbackCancellationTokenSource.Token, _cancellationTokenSource.Token); var cancellationToken = combinedTokenSource.Token; await foreach (byte[] audioData in _audioPlaybackReader.ReadAllAsync(cancellationToken).ConfigureAwait(false)) { if (cancellationToken.IsCancellationRequested) break; try { if (_playbackBuffer != null && _isPlaying) { _playbackBuffer.AddSamples(audioData, 0, audioData.Length); } } catch (Exception ex) { _logger.LogError(ex, "Error in audio playback"); // Continue processing other audio data } } } catch (OperationCanceledException) { // Expected when cancellation is requested } catch (Exception ex) { _logger.LogError(ex, "Error in audio playback processing"); } } /// <summary> /// Clean up audio resources. /// </summary> public async Task CleanupAsync() { await StopCaptureAsync().ConfigureAwait(false); await StopPlaybackAsync().ConfigureAwait(false); _cancellationTokenSource.Cancel(); // Wait for background tasks to complete var tasks = new List<Task>(); if (_audioSendTask != null) tasks.Add(_audioSendTask); if (_audioPlaybackTask != null) tasks.Add(_audioPlaybackTask); if (tasks.Count > 0) { await Task.WhenAll(tasks).ConfigureAwait(false); } _logger.LogInformation("Audio processor cleaned up"); } /// <summary> /// Dispose of resources. /// </summary> public void Dispose() { CleanupAsync().Wait(); _cancellationTokenSource.Dispose(); } } }執行您的主控台應用程式以開始即時交談:
dotnet run --use-token-credential
輸出
腳本的輸出會列印至主控台。 您會看到訊息,指出連線、音訊串流和播放的狀態。 音訊會透過喇叭或耳機播放。
info: Azure.AI.VoiceLive.Samples.Program[0]
      Audio system check passed (default input/output initialized).
info: Azure.AI.VoiceLive.Samples.Program[0]
      Using Azure token credential
info: Azure.AI.VoiceLive.Samples.BasicVoiceAssistant[0]
      Connecting to VoiceLive API with model gpt-realtime
info: Azure.AI.VoiceLive.Samples.AudioProcessor[0]
      AudioProcessor initialized with 24000Hz PCM16 mono audio
info: Azure.AI.VoiceLive.Samples.BasicVoiceAssistant[0]
      Setting up voice conversation session...
info: Azure.AI.VoiceLive.Samples.BasicVoiceAssistant[0]
      Session configuration sent
info: Azure.AI.VoiceLive.Samples.AudioProcessor[0]
      Audio playback system ready
info: Azure.AI.VoiceLive.Samples.AudioProcessor[0]
      Started audio capture
info: Azure.AI.VoiceLive.Samples.BasicVoiceAssistant[0]
      Voice assistant ready! Start speaking...

============================================================
🎤 VOICE ASSISTANT READY
Start speaking to begin conversation
Press Ctrl+C to exit
============================================================

info: Azure.AI.VoiceLive.Samples.BasicVoiceAssistant[0]
      Session ready: sess_CVnpwfxxxxxACIzrrr7
info: Azure.AI.VoiceLive.Samples.BasicVoiceAssistant[0]
      Session updated successfully
🎤 Listening...
info: Azure.AI.VoiceLive.Samples.BasicVoiceAssistant[0]
      🎤 User started speaking - stopping playback
info: Azure.AI.VoiceLive.Samples.AudioProcessor[0]
      Stopped audio playback
info: Azure.AI.VoiceLive.Samples.BasicVoiceAssistant[0]
      ✨ Used ClearStreamingAudioAsync convenience method
🤔 Processing...
info: Azure.AI.VoiceLive.Samples.BasicVoiceAssistant[0]
      🎤 User stopped speaking
info: Azure.AI.VoiceLive.Samples.AudioProcessor[0]
      Audio playback system ready
info: Azure.AI.VoiceLive.Samples.BasicVoiceAssistant[0]
      🤖 Assistant response created
🎤 Ready for next input...
info: Azure.AI.VoiceLive.Samples.BasicVoiceAssistant[0]
      🤖 Assistant finished speaking
info: Azure.AI.VoiceLive.Samples.BasicVoiceAssistant[0]
      ✅ Response complete
info: Azure.AI.VoiceLive.Samples.Program[0]
      Received shutdown signal
info: Azure.AI.VoiceLive.Samples.BasicVoiceAssistant[0]
      Event processing cancelled
info: Azure.AI.VoiceLive.Samples.AudioProcessor[0]
      Stopped audio capture
info: Azure.AI.VoiceLive.Samples.AudioProcessor[0]
      Stopped audio playback
info: Azure.AI.VoiceLive.Samples.AudioProcessor[0]
      Audio processor cleaned up
info: Azure.AI.VoiceLive.Samples.AudioProcessor[0]
      Audio processor cleaned up
在本文中,您將學習如何使用 JavaScript 的 VoiceLive SDK 與 Microsoft Foundry 模型來操作 Voice Live。
您會建立並執行應用程式,藉此將內含生成式 AI 模型的 Voice Live 直接使用於即時語音代理程式。
使用模型直接允許為每個會話指定自定義指示(提示),為動態或實驗使用案例提供更多彈性。
當您想要更精細地控制會話參數,或需要經常調整提示或設定,而不需在入口網站中更新代理程式時,最好使用模型。
模型型會話的程式代碼在某些方面比較簡單,因為它不需要管理代理程式標識碼或代理程式特定的設定。
直接模型使用適用於不需要代理程式層級抽象或內建邏輯的案例。
若想改用 Voice Live API 搭配代理,請參閱 Voice Live API 代理快速入門。
備註
JavaScript 語音直播 SDK 專為內建 WebSocket 與 Web Audio 支援的瀏覽器應用程式設計。 此快速入門使用 Node.js,搭配 node-record-lpcm16 與 speaker,提供主控台體驗。
先決條件
- 一個 Azure 訂閱。 免費創建一個。
- Node.js 18 或更新版本。
- 您的系統需安裝 SoX ( 麥克風擷取時
node-record-lpcm16需要)。 - Microsoft Foundry 資源 在支援區域之一建立。 如需區域可用性的詳細資訊,請參閱 區域支援。
小提示
要使用 Voice Live,你不需要用 Microsoft Foundry 資源部署音訊模型。 Voice Live 是完全管理的,模型會自動為您部署。 欲了解更多模型可用性資訊,請參閱 Voice Live 總覽文件。
Microsoft Entra ID 先決條件
建議使用 Microsoft Entra ID 進行無鑰匙認證,您需要:
- 安裝Azure CLI,用於與 Microsoft Entra ID 的無金鑰認證。
- 將
Cognitive Services User角色指派給您的使用者帳戶。 你可以在Azure入口網站的 存取控制(IAM)>新增角色分配下分配角色。
設定
建立新的資料夾
voice-live-quickstart,並使用下列命令移至快速入門資料夾:mkdir voice-live-quickstart && cd voice-live-quickstart建立一個包含以下內容的 package.json 檔案:
{
  "name": "voice-live-quickstart",
  "version": "1.0.0",
  "type": "module",
  "dependencies": {
    "@azure/ai-voicelive": "^1.0.0",
    "@azure/core-auth": "^1.0.0",
    "@azure/identity": "^4.0.0",
    "dotenv": "^16.0.0",
    "node-record-lpcm16": "^1.0.1",
    "speaker": "^0.5.5"
  }
}
備註
node-record-lpcm16與speaker套件是麥克風輸入與音訊播放的選配音訊套件。 它們需要 SoX 和原生建置工具。 如果你想在沒有音訊硬體的情況下連線,執行取樣時就用這個--no-audio旗標。安裝依賴項:
npm install
擷取資源資訊
在您要執行程式代碼的資料夾中,建立名為 .env 的新檔案。
在 檔案中 .env ,新增下列環境變數以進行驗證:
AZURE_VOICELIVE_ENDPOINT=<your_endpoint>
AZURE_VOICELIVE_MODEL=<your_model>
AZURE_VOICELIVE_API_VERSION=2026-04-10
AZURE_VOICELIVE_API_KEY=<your_api_key> # Only required if using API key authentication
將預設值取代為您的實際端點、模型、API 版本和 API 金鑰。
| 變數名稱 | 價值觀 |
|---|---|
AZURE_VOICELIVE_ENDPOINT |
此值可在Azure入口檢視資源時,Keys 與 Endpoint 區塊中找到。 |
AZURE_VOICELIVE_MODEL |
您想要使用的模型。 例如,gpt-4o 或 gpt-realtime-mini。 如需模型可用性的詳細資訊,請參閱 語音即時 API 概觀檔。 |
AZURE_VOICELIVE_API_VERSION |
您想要使用的 API 版本。 例如: 2026-04-10 。 |
開始交談
本快速入門中的範例程式碼支援 Microsoft Entra ID 與 API 金鑰認證。 如果你偏好無鑰匙認證,旗 --use-token-credential 幟就會切換到 DefaultAzureCredential 。
範例連接 Voice Live,並以以下欄位配置會話:
-
model: 調用的模型部署名稱(例如,gpt-realtime。 -
voice:用來回應音訊的聲音。 支援 Azure 標準語音及 OpenAI 語音。 -
modalities:會議所支持的模式。["text", "audio"]用於語音對話。 -
instructions:系統層級指令,用來配置助理的行為。 -
inputAudioFormat:輸入音訊串流的格式。 請使用pcm16來處理原始 PCM 音訊。
請用以下程式碼建立 model-quickstart.js 檔案:
// Copyright (c) Microsoft Corporation. All rights reserved.
// Licensed under the MIT License.

import "dotenv/config";
import { VoiceLiveClient } from "@azure/ai-voicelive";
import { AzureKeyCredential } from "@azure/core-auth";
import { DefaultAzureCredential } from "@azure/identity";
import { spawn } from "node:child_process";
import { existsSync, mkdirSync, appendFileSync } from "node:fs";
import { join, dirname } from "node:path";
import { fileURLToPath } from "node:url";

const __dirname = dirname(fileURLToPath(import.meta.url));

const logsDir = join(__dirname, "logs");
if (!existsSync(logsDir)) mkdirSync(logsDir, { recursive: true });

const timestamp = new Date()
  .toISOString()
  .replace(/[:.]/g, "-")
  .replace("T", "_")
  .slice(0, 19);
const conversationLogFile = join(logsDir, `conversation_${timestamp}.log`);

function writeConversationLog(message) {
  appendFileSync(conversationLogFile, message + "\n", "utf-8");
}

function printUsage() {
  console.log("Usage: node model-quickstart.js [options]");
  console.log("");
  console.log("Options:");
  console.log("  --api-key <key>             VoiceLive API key");
  console.log("  --endpoint <url>            VoiceLive endpoint URL");
  console.log("  --model <name>              Model to use (default: gpt-realtime)");
  console.log(
    "  --voice <name>              Voice (default: en-US-Ava:DragonHDLatestNeural)",
  );
  console.log("  --instructions <text>       System instructions for the assistant");
  console.log("  --audio-input-device <name> Explicit SoX input device name (Windows)");
  console.log("  --list-audio-devices        List available audio input devices and exit");
  console.log("  --greeting-text <text>      Send a pre-defined greeting instead of LLM-generated");
  console.log("  --use-token-credential      Use Azure credential instead of API key");
  console.log("  --no-audio                  Connect and configure session without mic/speaker");
  console.log("  -h, --help                  Show this help text");
}

function parseArguments(argv) {
  const parsed = {
    apiKey: process.env.AZURE_VOICELIVE_API_KEY,
    endpoint: process.env.AZURE_VOICELIVE_ENDPOINT,
    model: process.env.AZURE_VOICELIVE_MODEL ?? "gpt-realtime",
    voice:
      process.env.AZURE_VOICELIVE_VOICE ?? "en-US-Ava:DragonHDLatestNeural",
    instructions:
      process.env.AZURE_VOICELIVE_INSTRUCTIONS ??
      "You are a helpful AI assistant. Respond naturally and conversationally. Keep your responses concise but engaging.",
    audioInputDevice: process.env.AUDIO_INPUT_DEVICE,
    listAudioDevices: false,
    greetingText: undefined,
    useTokenCredential: false,
    noAudio: false,
    help: false,
  };

  for (let i = 0; i < argv.length; i++) {
    const arg = argv[i];
    switch (arg) {
      case "--api-key":
        parsed.apiKey = argv[++i];
        break;
      case "--endpoint":
        parsed.endpoint = argv[++i];
        break;
      case "--model":
        parsed.model = argv[++i];
        break;
      case "--voice":
        parsed.voice = argv[++i];
        break;
      case "--instructions":
        parsed.instructions = argv[++i];
        break;
      case "--audio-input-device":
        parsed.audioInputDevice = argv[++i];
        break;
      case "--list-audio-devices":
        parsed.listAudioDevices = true;
        break;
      case "--greeting-text":
        parsed.greetingText = argv[++i];
        break;
      case "--use-token-credential":
        parsed.useTokenCredential = true;
        break;
      case "--no-audio":
        parsed.noAudio = true;
        break;
      case "--help":
      case "-h":
        parsed.help = true;
        break;
      default:
        if (arg?.startsWith("-")) {
          throw new Error(`Unknown option: ${arg}`);
        }
        break;
    }
  }

  return parsed;
}

/**
 * List available audio input devices on Windows (AudioEndpoint via WMI).
 * Falls back to a note on non-Windows platforms.
 */
async function listAudioDevices() {
  if (process.platform !== "win32") {
    console.log("Device listing is currently supported on Windows only.");
    console.log("On macOS/Linux, run: sox -V6 -n -t coreaudio -n trim 0 0  (or similar)");
    return;
  }

  const { execSync } = await import("node:child_process");
  try {
    const output = execSync(
      'powershell -NoProfile -Command "Get-CimInstance Win32_PnPEntity | Where-Object { $_.PNPClass -eq \'AudioEndpoint\' } | Select-Object -ExpandProperty Name"',
      { encoding: "utf-8", timeout: 10000 },
    ).trim();

    if (!output) {
      console.log("No audio endpoint devices found.");
      return;
    }

    console.log("Available audio endpoint devices:");
    console.log("");
    for (const line of output.split(/\r?\n/)) {
      const name = line.trim();
      if (name) console.log(`  ${name}`);
    }
    console.log("");
    console.log("Use the device name (or a unique substring) with --audio-input-device.");
    console.log('Example: node model-quickstart.js --audio-input-device "Microphone"');
  } catch (err) {
    console.error("Failed to query audio devices:", err.message);
  }
}

function resolveVoiceConfig(voiceName) {
  const looksLikeAzureVoice = voiceName.includes("-") || voiceName.includes(":");
  if (looksLikeAzureVoice) {
    return {
      type: "azure-standard",
      name: voiceName,
    };
  }

  return {
    type: "openai",
    name: voiceName,
  };
}

class AudioProcessor {
  constructor(enableAudio = true, inputDevice = undefined) {
    this._enableAudio = enableAudio;
    this._inputDevice = inputDevice;
    this._recorder = null;
    this._soxProcess = null;
    this._speaker = null;
    this._skipSeq = 0;
    this._nextSeq = 0;
    this._recordModule = null;
    this._speakerCtor = null;
  }

  async _ensureAudioModulesLoaded() {
    if (!this._enableAudio) return;
    if (this._recordModule && this._speakerCtor) return;

    try {
      const recordModule = await import("node-record-lpcm16");
      const speakerModule = await import("speaker");
      this._recordModule = recordModule.default;
      this._speakerCtor = speakerModule.default;
    } catch {
      throw new Error(
        "Audio dependencies are unavailable. Install optional packages (node-record-lpcm16, speaker) and required native build tools, or run with --no-audio for connectivity-only validation.",
      );
    }
  }

  async startCapture(session) {
    if (!this._enableAudio) {
      console.log("[audio] --no-audio enabled: microphone capture skipped");
      return;
    }
    if (this._recorder || this._soxProcess) return;

    if (this._inputDevice) {
      console.log(`[audio] Using explicit input device: ${this._inputDevice}`);
      const soxArgs = [
        "-q", "-t", "waveaudio", this._inputDevice,
        "-r", "24000", "-c", "1",
        "-e", "signed-integer", "-b", "16",
        "-t", "raw", "-",
      ];

      this._soxProcess = spawn("sox", soxArgs, {
        stdio: ["ignore", "pipe", "pipe"],
      });

      this._soxProcess.stdout.on("data", (chunk) => {
        if (session.isConnected) {
          session.sendAudio(new Uint8Array(chunk)).catch(() => {
            // Ignore send errors during disconnect
          });
        }
      });

      this._soxProcess.stderr.on("data", (data) => {
        const msg = data.toString().trim();
        if (msg) {
          console.error(`[audio] sox stderr: ${msg}`);
        }
      });

      this._soxProcess.on("error", (error) => {
        console.error(`[audio] SoX process error: ${error?.message ?? error}`);
      });

      this._soxProcess.on("close", (code) => {
        if (code !== 0) {
          console.error(`[audio] SoX exited with code ${code}`);
        }
        this._soxProcess = null;
      });

      console.log("[audio] Microphone capture started");
      return;
    }

    await this._ensureAudioModulesLoaded();

    const recorderOptions = {
      sampleRate: 24000,
      channels: 1,
      audioType: "raw",
      recorder: "sox",
      encoding: "signed-integer",
      bitwidth: 16,
    };

    this._recorder = this._recordModule.record(recorderOptions);
    const recorderStream = this._recorder.stream();

    recorderStream.on("data", (chunk) => {
      if (session.isConnected) {
        session.sendAudio(new Uint8Array(chunk)).catch(() => {
          // Ignore send errors during disconnect
        });
      }
    });

    recorderStream.on("error", (error) => {
      console.error(`[audio] Recorder stream error: ${error?.message ?? error}`);
      console.error(
        "[audio] SoX capture failed. Check microphone permissions/device and run with DEBUG=record for details.",
      );
    });

    console.log("[audio] Microphone capture started");
  }

  async startPlayback() {
    if (!this._enableAudio) {
      console.log("[audio] --no-audio enabled: speaker playback skipped");
      return;
    }
    if (this._speaker) return;
    await this._resetSpeaker();
    console.log("[audio] Playback ready");
  }

  queueAudio(base64Delta) {
    const seq = this._nextSeq++;
    if (seq < this._skipSeq) return;
    const chunk = Buffer.from(base64Delta, "base64");
    if (this._speaker && !this._speaker.destroyed) {
      this._speaker.write(chunk);
    }
  }

  skipPendingAudio() {
    if (!this._enableAudio) return;
    this._skipSeq = this._nextSeq++;
    this._resetSpeaker().catch(() => {
      // best-effort reset
    });
  }

  shutdown() {
    if (this._soxProcess) {
      try {
        this._soxProcess.kill();
      } catch {
        // no-op
      }
      this._soxProcess = null;
    }

    if (this._recorder) {
      this._recorder.stop();
      this._recorder = null;
    }

    if (this._speaker) {
      this._speaker.end();
      this._speaker = null;
    }

    console.log("[audio] Audio processor shut down");
  }

  async _resetSpeaker() {
    await this._ensureAudioModulesLoaded();

    if (this._speaker && !this._speaker.destroyed) {
      try {
        this._speaker.end();
      } catch {
        // no-op
      }
    }

    this._speaker = new this._speakerCtor({
      channels: 1,
      bitDepth: 16,
      sampleRate: 24000,
      signed: true,
    });

    this._speaker.on("error", () => {
      // Swallow transient audio device errors
    });
  }
}

class BasicModelVoiceAssistant {
  constructor(options) {
    this.endpoint = options.endpoint;
    this.credential = options.credential;
    this.model = options.model;
    this.voice = options.voice;
    this.instructions = options.instructions;
    this.audioInputDevice = options.audioInputDevice;
    this.greetingText = options.greetingText;
    this.noAudio = options.noAudio;

    this._session = null;
    this._subscription = null;
    this._audio = new AudioProcessor(!options.noAudio, options.audioInputDevice);
    this._activeResponse = false;
    this._responseApiDone = false;
    this._greetingSent = false;
  }

  async start() {
    const client = new VoiceLiveClient(this.endpoint, this.credential);
    const session = client.createSession({ model: this.model });
    this._session = session;

    console.log(
      `[init] Connecting to VoiceLive with model "${this.model}" at "${this.endpoint}" ...`,
    );

    this._subscription = session.subscribe({
      onSessionUpdated: async (event, context) => {
        const s = event.session;
        const model = s?.model;
        const voice = s?.voice;

        console.log(`[session] Session ready: ${context.sessionId}`);
        writeConversationLog(
          [
            `SessionID: ${context.sessionId}`,
            `Model: ${typeof model === "string" ? model : model?.toString?.() ?? ""}`,
            `Voice Name: ${voice?.name ?? ""}`,
            `Voice Type: ${voice?.type ?? ""}`,
            "",
          ].join("\n"),
        );

        if (!this._greetingSent) {
          this._greetingSent = true;
        }
      },

      onConversationItemInputAudioTranscriptionCompleted: async (event) => {
        const transcript = event.transcript ?? "";
        console.log(`👤 You said:\t${transcript}`);
        writeConversationLog(`User Input:\t${transcript}`);
      },

      onResponseTextDone: async (event) => {
        const text = event.text ?? "";
        console.log(`🤖 Assistant text:\t${text}`);
        writeConversationLog(`Assistant Text Response:\t${text}`);
      },

      onResponseAudioTranscriptDone: async (event) => {
        const transcript = event.transcript ?? "";
        console.log(`🤖 Assistant audio transcript:\t${transcript}`);
        writeConversationLog(`Assistant Audio Response:\t${transcript}`);
      },

      onInputAudioBufferSpeechStarted: async () => {
        console.log("🎤 Listening...");
        this._audio.skipPendingAudio();

        if (this._activeResponse && !this._responseApiDone) {
          try {
            await session.sendEvent({ type: "response.cancel" });
          } catch (err) {
            const msg = err?.message ?? "";
            if (!msg.toLowerCase().includes("no active response")) {
              console.warn("[barge-in] Cancel failed:", msg);
            }
          }
        }
      },

      onInputAudioBufferSpeechStopped: async () => {
        console.log("🤔 Processing...");
      },

      onResponseCreated: async () => {
        this._activeResponse = true;
        this._responseApiDone = false;
      },

      onResponseAudioDelta: async (event) => {
        if (event.delta) {
          this._audio.queueAudio(event.delta);
        }
      },

      onResponseAudioDone: async () => {
        console.log("🎤 Ready for next input...");
      },

      onResponseDone: async () => {
        console.log("✅ Response complete");
        this._activeResponse = false;
        this._responseApiDone = true;
      },

      onServerError: async (event) => {
        const msg = event.error?.message ?? "";
        if (msg.includes("Cancellation failed: no active response")) {
          return;
        }
        console.error(`❌ VoiceLive error: ${msg}`);
      },

      onConversationItemCreated: async (event) => {
        console.log(`[event] Conversation item created: ${event.item?.id ?? ""}`);
      },
    });

    await session.connect();
    console.log("[init] Connected to VoiceLive session websocket");

    await this._setupSession();

    if (!this._greetingSent) {
      this._greetingSent = true;
      await this._sendProactiveGreeting();
    }

    await this._audio.startPlayback();
    await this._audio.startCapture(session);

    console.log("\n" + "=".repeat(60));
    console.log("🎤 VOICE ASSISTANT READY");
    console.log("Start speaking to begin conversation");
    console.log("Press Ctrl+C to exit");
    console.log("=".repeat(60) + "\n");

    if (this.noAudio) {
      setTimeout(() => {
        process.emit("SIGINT");
      }, 6000);
    }

    await new Promise((resolve) => {
      const onSignal = () => resolve();
      process.once("SIGINT", onSignal);
      process.once("SIGTERM", onSignal);

      const poll = setInterval(() => {
        if (!session.isConnected) {
          clearInterval(poll);
          resolve();
        }
      }, 500);
    });

    await this.shutdown();
  }

  /**
   * Send a proactive greeting when the session starts.
   * Supports pre-defined (--greeting-text) or LLM-generated (default).
   */
  async _sendProactiveGreeting() {
    const session = this._session;

    if (this.greetingText) {
      console.log("[session] Sending pre-generated greeting ...");
      try {
        await session.sendEvent({
          type: "response.create",
          response: {
            preGeneratedAssistantMessage: {
              content: [{ type: "text", text: this.greetingText }],
            },
          },
        });
      } catch (err) {
        console.error("[session] Failed to send pre-generated greeting:", err.message);
      }
    } else {
      console.log("[session] Sending proactive greeting ...");
      try {
        await session.addConversationItem({
          type: "message",
          role: "system",
          content: [
            {
              type: "input_text",
              text: "Say something to welcome the user in English.",
            },
          ],
        });
        await session.sendEvent({ type: "response.create" });
      } catch (err) {
        console.error("[session] Failed to send greeting:", err.message);
      }
    }
  }

  async _setupSession() {
    console.log("[session] Configuring session ...");

    await this._session.updateSession({
      model: this.model,
      modalities: ["text", "audio"],
      instructions: this.instructions,
      voice: resolveVoiceConfig(this.voice),
      inputAudioFormat: "pcm16",
      outputAudioFormat: "pcm16",
      turnDetection: {
        type: "server_vad",
        threshold: 0.5,
        prefixPaddingInMs: 400,
        silenceDurationInMs: 500,
      },
      inputAudioEchoCancellation: { type: "server_echo_cancellation" },
      inputAudioNoiseReduction: { type: "azure_deep_noise_suppression" },
      inputAudioTranscription: { model: "azure-speech" },
    });

    console.log("[session] Session configuration sent");
  }

  async shutdown() {
    if (this._subscription) {
      await this._subscription.close();
      this._subscription = null;
    }

    if (this._session) {
      try {
        await this._session.disconnect();
      } catch {
        // ignore disconnect errors during shutdown
      }

      this._audio.shutdown();

      try {
        await this._session.dispose();
      } catch {
        // ignore dispose errors during shutdown
      }

      this._session = null;
    }
  }
}

async function main() {
  let args;
  try {
    args = parseArguments(process.argv.slice(2));
  } catch (err) {
    console.error(`❌ ${err.message}`);
    printUsage();
    process.exit(1);
  }

  if (args.help) {
    printUsage();
    return;
  }

  if (args.listAudioDevices) {
    await listAudioDevices();
    return;
  }

  if (!args.endpoint) {
    console.error(
      "❌ Missing endpoint. Set AZURE_VOICELIVE_ENDPOINT or pass --endpoint.",
    );
    process.exit(1);
  }

  if (!args.apiKey && !args.useTokenCredential) {
    console.error("❌ No authentication provided.");
    console.error(
      "Provide --api-key / AZURE_VOICELIVE_API_KEY or use --use-token-credential.",
    );
    process.exit(1);
  }

  const credential = args.useTokenCredential
    ? new DefaultAzureCredential()
    : new AzureKeyCredential(args.apiKey);

  console.log("Configuration:");
  console.log(`  AZURE_VOICELIVE_ENDPOINT: ${args.endpoint}`);
  console.log(`  AZURE_VOICELIVE_MODEL: ${args.model}`);
  console.log(`  AZURE_VOICELIVE_VOICE: ${args.voice}`);
  console.log(`  AUDIO_INPUT_DEVICE: ${args.audioInputDevice ?? "(not set)"}`);
  if (args.greetingText) {
    console.log(`  Proactive greeting: pre-defined`);
  } else {
    console.log(`  Proactive greeting: LLM-generated (default)`);
  }
  console.log(`  No audio mode: ${args.noAudio ? "enabled" : "disabled"}`);
  console.log(
    `  Authentication: ${args.useTokenCredential ? "DefaultAzureCredential" : "API Key"}`,
  );

  const assistant = new BasicModelVoiceAssistant({
    endpoint: args.endpoint,
    credential,
    model: args.model,
    voice: args.voice,
    instructions: args.instructions,
    audioInputDevice: args.audioInputDevice,
    greetingText: args.greetingText,
    noAudio: args.noAudio,
  });

  try {
    await assistant.start();
  } catch (err) {
    if (err?.code === "ERR_USE_AFTER_CLOSE") return;
    console.error("Fatal error:", err);
    process.exit(1);
  }
}

console.log("🎙️  Basic Voice Assistant with Azure VoiceLive SDK (Model Mode)");
console.log("=".repeat(60));
main().then(
  () => console.log("\n👋 Voice assistant shut down. Goodbye!"),
  (err) => {
    console.error("Unhandled error:", err);
    process.exit(1);
  },
);
啟動語音助理:
node model-quickstart.js若要使用 Microsoft Entra ID 認證取代 API 金鑰,請先登入並新增
--use-token-credential標誌:az login node model-quickstart.js --use-token-credential開始和模特兒對話,聽聽他們的回應。 您可以藉由說話來中斷模型。 輸入“Ctrl+C”退出對話。
輸出
腳本的輸出會列印至主控台。 您會看到訊息,指出連線、音訊串流和播放的狀態。 音訊會透過喇叭或耳機播放。
🎙️  Basic Voice Assistant with Azure VoiceLive SDK (Model Mode)
============================================================

Configuration:
  AZURE_VOICELIVE_ENDPOINT: https://<your-resource>.cognitiveservices.azure.com/
  AZURE_VOICELIVE_MODEL: gpt-realtime
  AZURE_VOICELIVE_VOICE: en-US-Ava:DragonHDLatestNeural
  AUDIO_INPUT_DEVICE: (not set)
  Proactive greeting: LLM-generated (default)
  No audio mode: disabled
  Authentication: API Key

============================================================
🎤 VOICE ASSISTANT READY
Start speaking to begin conversation
Press Ctrl+C to exit
============================================================

🎤 Listening...
🤔 Processing...
👤 You said:	Hello.
🎤 Ready for next input...
🤖 Assistant text:	Hello! How can I assist you today?
🎤 Listening...
🤔 Processing...
👤 You said:	What's the capital/major city of France?
🎤 Ready for next input...
🤖 Assistant text:	The capital/major city of France is Paris. It's one of the most visited cities in the world, known for landmarks like the Eiffel Tower, the Louvre museum, and Notre-Dame Cathedral. Is there anything else you'd like to know?

👋 Voice assistant shut down. Goodbye!
在名為 logs的資料夾中建立conversation_YYYYMMDD_HHmmss.log一個對話日誌檔案。 此檔案包含會話中繼資料及對話逐字稿。
SessionID: sess_2n3aSMKTRqkKqacFPzRqUM
Model: gpt-realtime
Voice Name: en-US-Ava:DragonHDLatestNeural
Voice Type: azure-standard

User Input:	Hello.
Assistant Text Response:	Hello! How can I assist you today?
User Input:	What's the capital/major city of France?
Assistant Text Response:	The capital of France is Paris...
| 層面 | 交談記錄檔 | 技術記錄檔 |
|---|---|---|
| 觀眾 | 商務用戶、內容檢閱者 | 開發人員、IT 作業 |
| Content | 交談中說了什麼 | 系統的運作方式 |
| 等級 | 應用程式/交談層級 | 系統/基礎結構層級 |
| Troubleshooting | 「模特兒怎麼說?」 | 「為什麼連線失敗? |
舉例來說:如果你的助理沒有回應,你會檢查:
- 主控台日誌 →「WebSocket 連線失敗」或「音訊串流錯誤」
- 對話紀錄 →「使用者真的有說什麼嗎?」
這兩種日誌是互補的——對話日誌用於對話分析與測試,技術日誌用於系統診斷。
技術記錄檔
目的:技術偵錯和系統監視
內容:
- WebSocket 連線事件
- 音訊串流狀態
- 錯誤訊息和堆疊痕跡
- 系統層級事件 (session.created、response.done 等)
- 網路連線問題
- 音訊處理診斷
格式:帶有括號前綴的主控台輸出(例如 [session], , [audio], [init])
使用案例:
- 偵錯連線問題
- 監視系統效能
- 針對音訊問題進行疑難排解
- 開發人員/作業分析
交談記錄
目的:交談文字記錄和用戶體驗追蹤
內容:
- 模型與會話識別
- 會話設定詳細數據
- 用戶逐字稿:「今天天氣如何?」、「停止」
- 模型回應:完整回應文字
- 交談流程和互動
格式:純文本、人類可讀取的交談格式
使用案例:
- 分析交談品質
- 回顧實際的發言
- 理解使用者互動與模型回應
- 商務/內容分析
在本文中,您將學習如何使用適用於 Java 的 VoiceLive SDK 來搭配 Microsoft Foundry 模型 使用 Voice Live。
您會建立並執行應用程式,藉此將內含生成式 AI 模型的 Voice Live 直接使用於即時語音代理程式。
使用模型直接允許為每個會話指定自定義指示(提示),為動態或實驗使用案例提供更多彈性。
當您想要更精細地控制會話參數,或需要經常調整提示或設定,而不需在入口網站中更新代理程式時,最好使用模型。
模型型會話的程式代碼在某些方面比較簡單,因為它不需要管理代理程式標識碼或代理程式特定的設定。
直接模型使用適用於不需要代理程式層級抽象或內建邏輯的案例。
若想改用 Voice Live API 搭配代理,請參閱 Voice Live API 代理快速入門。
先決條件
- 一個 Azure 訂閱。 免費創建一個。
- Java 開發套件(JDK)11 或更新版本。
- Apache Maven 用於依賴管理和建置專案。
- 在其中一個支援的區域中建立的 Foundry 資源。 如需區域可用性的詳細資訊,請參閱 區域支援。
- API 金鑰或 Azure CLI 用於認證。
- 麥克風和喇叭(或耳機)連接到你的電腦。 取樣會從麥克風擷取現場音訊,並透過喇叭播放回應。 為了在不使用音訊硬體的情況下測試,取樣支援
--no-audio僅用於文字互動的旗標。
小提示
要使用 Voice Live,你不需要用 Foundry 資源部署音訊模型。 Voice Live 是完全管理的,模型會自動為您部署。 欲了解更多模型可用性資訊,請參閱 Voice Live 總覽文件。
備註
為了使用 Microsoft Entra ID 進行無鑰匙認證,安裝 Azure CLI,並將 Cognitive Services User 角色指派給你的使用者帳號。 你可以在Azure入口網站的 存取控制(IAM)>新增角色分配下分配角色。
設定
建立新的資料夾
voice-live-quickstart,並使用下列命令移至快速入門資料夾:mkdir voice-live-quickstart && cd voice-live-quickstart在專案目錄根目錄建立
pom.xml一個包含以下內容的檔案:<?xml version="1.0" encoding="UTF-8"?> <project xmlns="http://maven.apache.org/POM/4.0.0" xmlns:xsi="http://www.w3.org/2001/XMLSchema-instance" xsi:schemaLocation="http://maven.apache.org/POM/4.0.0 http://maven.apache.org/xsd/maven-4.0.0.xsd"> <modelVersion>4.0.0</modelVersion> <groupId>com.azure.ai.voicelive</groupId> <artifactId>model-quickstart</artifactId> <version>1.0.0</version> <packaging>jar</packaging> <name>Azure VoiceLive Model Quickstart</name> <description>Model quickstart sample for Azure AI VoiceLive SDK</description> <properties> <maven.compiler.source>11</maven.compiler.source> <maven.compiler.target>11</maven.compiler.target> <project.build.sourceEncoding>UTF-8</project.build.sourceEncoding> </properties> <dependencies> <!-- Azure VoiceLive SDK --> <dependency> <groupId>com.azure</groupId> <artifactId>azure-ai-voicelive</artifactId> <version>1.0.0</version> </dependency> <!-- Azure Core --> <dependency> <groupId>com.azure</groupId> <artifactId>azure-core</artifactId> <version>1.53.0</version> </dependency> <!-- Azure Identity for authentication --> <dependency> <groupId>com.azure</groupId> <artifactId>azure-identity</artifactId> <version>1.11.0</version> </dependency> <!-- Reactor Core for reactive programming --> <dependency> <groupId>io.projectreactor</groupId> <artifactId>reactor-core</artifactId> <version>3.5.11</version> </dependency> <!-- SLF4J for logging --> <dependency> <groupId>org.slf4j</groupId> <artifactId>slf4j-api</artifactId> <version>2.0.9</version> </dependency> <dependency> <groupId>org.slf4j</groupId> <artifactId>slf4j-simple</artifactId> <version>2.0.9</version> </dependency> </dependencies> <build> <sourceDirectory>.</sourceDirectory> <plugins> <plugin> <groupId>org.apache.maven.plugins</groupId> <artifactId>maven-compiler-plugin</artifactId> <version>3.11.0</version> <configuration> <source>11</source> <target>11</target> </configuration> </plugin> <plugin> <groupId>org.codehaus.mojo</groupId> <artifactId>exec-maven-plugin</artifactId> <version>3.1.0</version> <configuration> <mainClass>ModelQuickstart</mainClass> </configuration> </plugin> </plugins> </build> </project>備註
<sourceDirectory>.</sourceDirectory>設定會告訴 Maven 在目前目錄中尋找Java原始碼檔案,而非預設的src/main/java結構。 這使得專案結構更為簡單。安裝依賴項:
mvn clean install設定認證 - 將 複製到
application.properties.sample,然後更新為你的數值:cp application.properties.sample application.properties編輯
application.properties:azure.voicelive.endpoint=https://your-resource-name.services.ai.azure.com/ azure.voicelive.api-key=your-api-key azure.voicelive.api-version=2026-04-10備註
你也可以用環境變數代替
application.properties。 集合AZURE_VOICELIVE_ENDPOINT和AZURE_VOICELIVE_API_KEY。 應用程式會先檢查application.properties,然後回退到環境變數。執行範例:
mvn exec:java要使用 Azure 憑證認證取代 API 金鑰:
az login
mvn exec:java -Dexec.args="--use-token-credential"
備註
在某些終端如 PowerShell 中,你可能需要逸出引數。 請在 PowerShell 中使用
mvn exec:java `"-Dexec.args=--use-token-credential`"
擷取資源資訊
在您要執行程式代碼的資料夾中,建立名為 .env 的新檔案。
在 檔案中 .env ,新增下列環境變數以進行驗證:
AZURE_VOICELIVE_ENDPOINT=<your_endpoint>
AZURE_VOICELIVE_MODEL=<your_model>
AZURE_VOICELIVE_API_VERSION=2026-04-10
AZURE_VOICELIVE_API_KEY=<your_api_key> # Only required if using API key authentication
將預設值取代為您的實際端點、模型、API 版本和 API 金鑰。
| 變數名稱 | 價值觀 |
|---|---|
AZURE_VOICELIVE_ENDPOINT |
此值可在Azure入口檢視資源時,Keys 與 Endpoint 區塊中找到。 |
AZURE_VOICELIVE_MODEL |
您想要使用的模型。 例如,gpt-4o 或 gpt-realtime-mini。 如需模型可用性的詳細資訊,請參閱 語音即時 API 概觀檔。 |
AZURE_VOICELIVE_API_VERSION |
您想要使用的 API 版本。 例如: 2026-04-10 。 |
新增範例程式碼
使用下列程式代碼,建立 ModelQuickstart.java 檔案。
// Copyright (c) Microsoft Corporation. All rights reserved.
// Licensed under the MIT License.
import com.azure.ai.voicelive.VoiceLiveAsyncClient;
import com.azure.ai.voicelive.VoiceLiveClientBuilder;
import com.azure.ai.voicelive.VoiceLiveServiceVersion;
import com.azure.ai.voicelive.VoiceLiveSessionAsyncClient;
import com.azure.ai.voicelive.models.AudioEchoCancellation;
import com.azure.ai.voicelive.models.AudioInputTranscriptionOptions;
import com.azure.ai.voicelive.models.AudioInputTranscriptionOptionsModel;
import com.azure.ai.voicelive.models.AudioNoiseReduction;
import com.azure.ai.voicelive.models.AudioNoiseReductionType;
import com.azure.ai.voicelive.models.ClientEventSessionUpdate;
import com.azure.ai.voicelive.models.InputAudioFormat;
import com.azure.ai.voicelive.models.InteractionModality;
import com.azure.ai.voicelive.models.AzureStandardVoice;
import com.azure.ai.voicelive.models.OutputAudioFormat;
import com.azure.ai.voicelive.models.ServerEventType;
import com.azure.ai.voicelive.models.ServerVadTurnDetection;
import com.azure.ai.voicelive.models.SessionUpdate;
import com.azure.ai.voicelive.models.SessionUpdateError;
import com.azure.ai.voicelive.models.SessionUpdateResponseAudioDelta;
import com.azure.ai.voicelive.models.SessionUpdateSessionUpdated;
import com.azure.ai.voicelive.models.VoiceLiveSessionOptions;
import com.azure.core.credential.KeyCredential;
import com.azure.core.credential.TokenCredential;
import com.azure.core.util.BinaryData;
import com.azure.identity.AzureCliCredentialBuilder;
import reactor.core.publisher.Mono;
import reactor.core.scheduler.Schedulers;
import javax.sound.sampled.AudioFormat;
import javax.sound.sampled.AudioSystem;
import javax.sound.sampled.DataLine;
import javax.sound.sampled.LineUnavailableException;
import javax.sound.sampled.SourceDataLine;
import javax.sound.sampled.TargetDataLine;
import java.io.FileInputStream;
import java.io.IOException;
import java.io.InputStream;
import java.util.Arrays;
import java.util.Properties;
import java.util.concurrent.BlockingQueue;
import java.util.concurrent.LinkedBlockingQueue;
import java.util.concurrent.atomic.AtomicBoolean;
import java.util.concurrent.atomic.AtomicInteger;
import java.util.concurrent.atomic.AtomicReference;
/**
* Complete voice assistant sample demonstrating full-featured real-time voice conversation.
*
* <p><strong>NOTE:</strong> This is a comprehensive sample showing all features together.
* For easier understanding, see these focused samples:</p>
* <ul>
* <li>{@link BasicVoiceConversationSample} - Minimal setup and session management</li>
* <li>{@link MicrophoneInputSample} - Audio capture from microphone</li>
* <li>{@link AudioPlaybackSample} - Audio playback to speakers</li>
* <li>{@link AuthenticationMethodsSample} - Different authentication methods</li>
* </ul>
*
* <p>This sample demonstrates:</p>
* <ul>
* <li>Real-time microphone audio capture</li>
* <li>Streaming audio to VoiceLive service</li>
* <li>Receiving and playing audio responses</li>
* <li>Voice Activity Detection (VAD) with interruption handling</li>
* <li>Multi-threaded audio processing</li>
* <li>Audio transcription with Whisper</li>
* <li>Noise reduction and echo cancellation</li>
* <li>Dual authentication support (API key and token credential)</li>
* </ul>
*
* <p><strong>Environment Variables Required:</strong></p>
* <ul>
* <li>AZURE_VOICELIVE_ENDPOINT - The VoiceLive service endpoint URL</li>
* <li>AZURE_VOICELIVE_API_KEY - The API key (required if not using --use-token-credential)</li>
* </ul>
*
* <p><strong>Audio Requirements:</strong></p>
* The sample requires a working microphone and speakers/headphones.
* Audio format is 24kHz, 16-bit PCM, mono as required by the VoiceLive service.
*
* <p><strong>How to Run:</strong></p>
* <pre>{@code
* # With API Key (default):
* mvn exec:java -Dexec.mainClass="com.azure.ai.voicelive.VoiceAssistantSample" -Dexec.classpathScope=test
*
* # With Token Credential:
* mvn exec:java -Dexec.mainClass="ModelQuickstart" -Dexec.classpathScope=test -Dexec.args="--use-token-credential"
* }</pre>
*/
public final class ModelQuickstart {
// Service configuration constants
private static final String DEFAULT_API_VERSION = "2025-10-01";
private static final String DEFAULT_MODEL = "gpt-realtime";
private static final String DEFAULT_VOICE = "en-US-Ava:DragonHDLatestNeural";
private static final String DEFAULT_INSTRUCTIONS = "You are a helpful AI voice assistant. Respond naturally and conversationally. Keep your responses concise but engaging. Speak as if having a real conversation.";
// Environment variable names
private static final String ENV_ENDPOINT = "AZURE_VOICELIVE_ENDPOINT";
private static final String ENV_API_KEY = "AZURE_VOICELIVE_API_KEY";
// Audio format constants (VoiceLive requirements)
private static final int SAMPLE_RATE = 24000; // 24kHz as required by VoiceLive
private static final int CHANNELS = 1; // Mono
private static final int SAMPLE_SIZE_BITS = 16; // 16-bit PCM
private static final int CHUNK_SIZE = 1200; // 50ms chunks (24000 * 0.05)
private static final int AUDIO_BUFFER_SIZE_MULTIPLIER = 4;
// Private constructor to prevent instantiation
private ModelQuickstart() {
throw new UnsupportedOperationException("Utility class cannot be instantiated");
}
/**
* Audio packet for playback queue management.
* Uses sequence numbers to support interruption handling.
*/
private static class AudioPlaybackPacket {
final int sequenceNumber;
final byte[] audioData;
AudioPlaybackPacket(int sequenceNumber, byte[] audioData) {
this.sequenceNumber = sequenceNumber;
this.audioData = audioData;
}
}
/**
* Handles real-time audio capture from microphone and playback to speakers.
*
* <p>This class manages two separate threads:</p>
* <ul>
* <li>Capture thread: Continuously reads audio from microphone and sends to VoiceLive service</li>
* <li>Playback thread: Receives audio responses and plays them through speakers</li>
* </ul>
*
* <p>Supports interruption handling where user speech can cancel ongoing assistant responses.</p>
*/
private static class AudioProcessor {
private final VoiceLiveSessionAsyncClient session;
private final AudioFormat audioFormat;
// Audio capture components
private TargetDataLine microphone;
private final AtomicBoolean isCapturing = new AtomicBoolean(false);
// Audio playback components
private SourceDataLine speaker;
private final BlockingQueue<AudioPlaybackPacket> playbackQueue = new LinkedBlockingQueue<>();
private final AtomicBoolean isPlaying = new AtomicBoolean(false);
private final AtomicInteger nextSequenceNumber = new AtomicInteger(0);
private final AtomicInteger playbackBase = new AtomicInteger(0);
AudioProcessor(VoiceLiveSessionAsyncClient session) {
this.session = session;
this.audioFormat = new AudioFormat(
AudioFormat.Encoding.PCM_SIGNED,
SAMPLE_RATE,
SAMPLE_SIZE_BITS,
CHANNELS,
CHANNELS * SAMPLE_SIZE_BITS / 8, // frameSize
SAMPLE_RATE,
false // bigEndian
);
}
/**
* Start capturing audio from microphone
*/
void startCapture() {
if (isCapturing.get()) {
return;
}
try {
DataLine.Info micInfo = new DataLine.Info(TargetDataLine.class, audioFormat);
if (!AudioSystem.isLineSupported(micInfo)) {
throw new UnsupportedOperationException("Microphone not supported with required format");
}
microphone = (TargetDataLine) AudioSystem.getLine(micInfo);
microphone.open(audioFormat, CHUNK_SIZE * AUDIO_BUFFER_SIZE_MULTIPLIER);
microphone.start();
isCapturing.set(true);
// Start capture thread
Thread captureThread = new Thread(this::captureAudioLoop, "VoiceLive-AudioCapture");
captureThread.setDaemon(true);
captureThread.start();
System.out.println("🎤 Microphone capture started");
} catch (LineUnavailableException e) {
System.err.println("❌ Failed to start microphone: " + e.getMessage());
throw new RuntimeException("Failed to initialize microphone", e);
}
}
/**
* Starts audio playback system.
*/
void startPlayback() {
if (isPlaying.get()) {
return;
}
try {
DataLine.Info speakerInfo = new DataLine.Info(SourceDataLine.class, audioFormat);
if (!AudioSystem.isLineSupported(speakerInfo)) {
throw new UnsupportedOperationException("Speaker not supported with required format");
}
speaker = (SourceDataLine) AudioSystem.getLine(speakerInfo);
speaker.open(audioFormat, CHUNK_SIZE * AUDIO_BUFFER_SIZE_MULTIPLIER);
speaker.start();
isPlaying.set(true);
// Start playback thread
Thread playbackThread = new Thread(this::playbackAudioLoop, "VoiceLive-AudioPlayback");
playbackThread.setDaemon(true);
playbackThread.start();
System.out.println("🔊 Audio playback started");
} catch (LineUnavailableException e) {
System.err.println("❌ Failed to start speaker: " + e.getMessage());
throw new RuntimeException("Failed to initialize speaker", e);
}
}
/**
* Audio capture loop - runs in separate thread
*/
private void captureAudioLoop() {
byte[] buffer = new byte[CHUNK_SIZE * 2]; // 16-bit samples
System.out.println("🎤 Audio capture loop started");
while (isCapturing.get() && microphone != null) {
try {
int bytesRead = microphone.read(buffer, 0, buffer.length);
if (bytesRead > 0) {
// Send audio to VoiceLive service
byte[] audioChunk = Arrays.copyOf(buffer, bytesRead);
// Send audio asynchronously using the session's audio buffer append
session.sendInputAudio(BinaryData.fromBytes(audioChunk))
.subscribeOn(Schedulers.boundedElastic())
.subscribe(
v -> {}, // onNext
error -> {
// Only log non-interruption errors
if (!error.getMessage().contains("cancelled")) {
System.err.println("❌ Error sending audio: " + error.getMessage());
}
}
);
}
} catch (Exception e) {
if (isCapturing.get()) {
System.err.println("❌ Error in audio capture: " + e.getMessage());
}
break;
}
}
System.out.println("🎤 Audio capture loop ended");
}
/**
* Audio playback loop - runs in separate thread
*/
private void playbackAudioLoop() {
while (isPlaying.get()) {
try {
AudioPlaybackPacket packet = playbackQueue.take(); // Blocking wait
if (packet.audioData == null) {
// Shutdown signal
break;
}
// Check if packet should be skipped (interrupted)
int currentBase = playbackBase.get();
if (packet.sequenceNumber < currentBase) {
// Skip interrupted audio
continue;
}
// Play the audio
if (speaker != null && speaker.isOpen()) {
speaker.write(packet.audioData, 0, packet.audioData.length);
}
} catch (InterruptedException e) {
Thread.currentThread().interrupt();
break;
} catch (Exception e) {
System.err.println("❌ Error in audio playback: " + e.getMessage());
}
}
}
/**
* Queue audio data for playback
*/
void queueAudio(byte[] audioData) {
if (audioData != null && audioData.length > 0) {
int seqNum = nextSequenceNumber.getAndIncrement();
playbackQueue.offer(new AudioPlaybackPacket(seqNum, audioData));
}
}
/**
* Skip pending audio (for interruption handling)
*/
void skipPendingAudio() {
playbackBase.set(nextSequenceNumber.get());
playbackQueue.clear();
// Also drain the speaker buffer to stop playback immediately
if (speaker != null && speaker.isOpen()) {
speaker.flush();
}
}
/**
* Stop capture and playback
*/
void shutdown() {
// Stop capture
isCapturing.set(false);
if (microphone != null) {
microphone.stop();
microphone.close();
microphone = null;
}
System.out.println("🎤 Microphone capture stopped");
// Stop playback
isPlaying.set(false);
playbackQueue.offer(new AudioPlaybackPacket(-1, null)); // Shutdown signal
if (speaker != null) {
speaker.stop();
speaker.close();
speaker = null;
}
System.out.println("🔊 Audio playback stopped");
}
}
/**
* Configuration class to hold application settings.
*/
private static class Config {
String endpoint;
String apiKey;
String model = DEFAULT_MODEL;
String voice = DEFAULT_VOICE;
String instructions = DEFAULT_INSTRUCTIONS;
boolean useTokenCredential = false;
static Config load(String[] args) {
Config config = new Config();
// 1. Load from application.properties first
Properties props = loadProperties();
if (props != null) {
config.endpoint = props.getProperty("azure.voicelive.endpoint");
config.apiKey = props.getProperty("azure.voicelive.api-key");
config.model = props.getProperty("azure.voicelive.model", DEFAULT_MODEL);
config.voice = props.getProperty("azure.voicelive.voice", DEFAULT_VOICE);
config.instructions = props.getProperty("azure.voicelive.instructions", DEFAULT_INSTRUCTIONS);
}
// 2. Override with environment variables if present
if (System.getenv(ENV_ENDPOINT) != null) {
config.endpoint = System.getenv(ENV_ENDPOINT);
}
if (System.getenv(ENV_API_KEY) != null) {
config.apiKey = System.getenv(ENV_API_KEY);
}
if (System.getenv("AZURE_VOICELIVE_MODEL") != null) {
config.model = System.getenv("AZURE_VOICELIVE_MODEL");
}
if (System.getenv("AZURE_VOICELIVE_VOICE") != null) {
config.voice = System.getenv("AZURE_VOICELIVE_VOICE");
}
if (System.getenv("AZURE_VOICELIVE_INSTRUCTIONS") != null) {
config.instructions = System.getenv("AZURE_VOICELIVE_INSTRUCTIONS");
}
// 3. Parse command line arguments (highest priority)
for (int i = 0; i < args.length; i++) {
switch (args[i]) {
case "--endpoint":
if (i + 1 < args.length) config.endpoint = args[++i];
break;
case "--api-key":
if (i + 1 < args.length) config.apiKey = args[++i];
break;
case "--model":
if (i + 1 < args.length) config.model = args[++i];
break;
case "--voice":
if (i + 1 < args.length) config.voice = args[++i];
break;
case "--instructions":
if (i + 1 < args.length) config.instructions = args[++i];
break;
case "--use-token-credential":
config.useTokenCredential = true;
break;
}
}
return config;
}
}
/**
* Load configuration from application.properties file.
*/
private static Properties loadProperties() {
Properties props = new Properties();
try (InputStream input = new FileInputStream("application.properties")) {
props.load(input);
System.out.println("✓ Loaded configuration from application.properties");
return props;
} catch (IOException e) {
// File not found or cannot be read - this is OK, will use env vars
return null;
}
}
/**
* Main method to run the voice assistant sample.
*
* <p>Configuration priority (highest to lowest):</p>
* <ol>
* <li>Command line arguments</li>
* <li>Environment variables</li>
* <li>application.properties file</li>
* </ol>
*
* <p>Supported command line arguments:</p>
* <ul>
* <li>--endpoint <url> - VoiceLive endpoint URL</li>
* <li>--api-key <key> - API key for authentication</li>
* <li>--model <model> - Model to use (default: gpt-realtime)</li>
* <li>--voice <voice> - Voice name (e.g., en-US-Ava:DragonHDLatestNeural)</li>
* <li>--instructions <text> - Custom system instructions</li>
* <li>--use-token-credential - Use Azure CLI authentication instead of API key</li>
* </ul>
*
* @param args Command line arguments
*/
public static void main(String[] args) {
// Load configuration
Config config = Config.load(args);
// Validate configuration
if (config.endpoint == null) {
printUsage();
return;
}
if (!config.useTokenCredential && config.apiKey == null) {
System.err.println("❌ API key is required when not using --use-token-credential");
System.err.println(" Set it via:");
System.err.println(" - application.properties: azure.voicelive.api-key=<your-key>");
System.err.println(" - Environment variable: AZURE_VOICELIVE_API_KEY=<your-key>");
System.err.println(" - Command line: --api-key <your-key>");
printUsage();
return;
}
// Check audio system availability
if (!checkAudioSystem()) {
System.err.println("❌ Audio system check failed. Please ensure microphone and speakers are available.");
return;
}
System.out.println("🎙️ Starting Voice Assistant...");
System.out.println(" Model: " + config.model);
if (config.voice != null) {
System.out.println(" Voice: " + config.voice);
}
try {
if (config.useTokenCredential) {
// Use token credential authentication (Azure CLI)
System.out.println("🔑 Using Token Credential authentication (Azure CLI)");
System.out.println(" Make sure you have run 'az login' before running this sample");
TokenCredential credential = new AzureCliCredentialBuilder().build();
runVoiceAssistant(config, credential);
} else {
// Use API Key authentication
System.out.println("🔑 Using API Key authentication");
runVoiceAssistant(config, new KeyCredential(config.apiKey));
}
System.out.println("✓ Voice Assistant completed successfully");
} catch (Exception e) {
System.err.println("❌ Voice Assistant failed: " + e.getMessage());
e.printStackTrace();
}
}
/**
* Check if audio system is available
*/
private static boolean checkAudioSystem() {
try {
AudioFormat format = new AudioFormat(SAMPLE_RATE, SAMPLE_SIZE_BITS, CHANNELS, true, false);
// Check microphone
DataLine.Info micInfo = new DataLine.Info(TargetDataLine.class, format);
if (!AudioSystem.isLineSupported(micInfo)) {
System.err.println("❌ No compatible microphone found");
return false;
}
// Check speaker
DataLine.Info speakerInfo = new DataLine.Info(SourceDataLine.class, format);
if (!AudioSystem.isLineSupported(speakerInfo)) {
System.err.println("❌ No compatible speaker found");
return false;
}
System.out.println("✓ Audio system check passed");
return true;
} catch (Exception e) {
System.err.println("❌ Audio system check failed: " + e.getMessage());
return false;
}
}
/**
* Prints usage instructions for setting up environment variables.
*/
private static void printUsage() {
System.err.println("\n═══════════════════════════════════════════════════════════════");
System.err.println("Usage: mvn exec:java [options]");
System.err.println("═══════════════════════════════════════════════════════════════");
System.err.println("\nConfiguration (in priority order):");
System.err.println(" 1. Command line arguments (--endpoint, --api-key, etc.)");
System.err.println(" 2. Environment variables (AZURE_VOICELIVE_ENDPOINT, etc.)");
System.err.println(" 3. application.properties file");
System.err.println("\nCommand Line Options:");
System.err.println(" --endpoint <url> VoiceLive endpoint URL");
System.err.println(" --api-key <key> API key for authentication");
System.err.println(" --model <model> Model to use (default: gpt-realtime)");
System.err.println(" --voice <voice> Voice name (e.g., en-US-Ava:DragonHDLatestNeural)");
System.err.println(" --instructions <text> Custom system instructions");
System.err.println(" --use-token-credential Use Azure CLI authentication");
System.err.println("\nExamples:");
System.err.println(" # Using application.properties:");
System.err.println(" mvn exec:java");
System.err.println("\n # Using command line arguments:");
System.err.println(" mvn exec:java -Dexec.args=\"--endpoint https://... --api-key <key>\"");
System.err.println("\n # Using Azure CLI authentication:");
System.err.println(" mvn exec:java -Dexec.args=\"--use-token-credential\"");
System.err.println("\n # With custom model and voice:");
System.err.println(" mvn exec:java -Dexec.args=\"--model gpt-4.1 --voice en-US-JennyNeural\"");
System.err.println("═══════════════════════════════════════════════════════════════\n");
}
/**
* Run the voice assistant with API key authentication.
*
* @param config The configuration object
* @param credential The API key credential
*/
private static void runVoiceAssistant(Config config, KeyCredential credential) {
System.out.println("🔧 Initializing VoiceLive client:");
System.out.println(" Endpoint: " + config.endpoint);
// Create the VoiceLive client
VoiceLiveAsyncClient client = new VoiceLiveClientBuilder()
.endpoint(config.endpoint)
.credential(credential)
.serviceVersion(VoiceLiveServiceVersion.V2025_10_01)
.buildAsyncClient();
runVoiceAssistantWithClient(client, config);
}
/**
* Run the voice assistant with Azure AD authentication.
*
* @param config The configuration object
* @param credential The token credential
*/
private static void runVoiceAssistant(Config config, TokenCredential credential) {
System.out.println("🔧 Initializing VoiceLive client:");
System.out.println(" Endpoint: " + config.endpoint);
// Create the VoiceLive client
VoiceLiveAsyncClient client = new VoiceLiveClientBuilder()
.endpoint(config.endpoint)
.credential(credential)
.serviceVersion(VoiceLiveServiceVersion.V2025_10_01)
.buildAsyncClient();
runVoiceAssistantWithClient(client, config);
}
/**
* Run the voice assistant with the configured client.
*
* @param client The VoiceLive async client
* @param config The configuration object
*/
private static void runVoiceAssistantWithClient(VoiceLiveAsyncClient client, Config config) {
System.out.println("✓ VoiceLive client created");
// Configure session options for voice conversation
VoiceLiveSessionOptions sessionOptions = createVoiceSessionOptions(config);
AtomicReference<AudioProcessor> audioProcessorRef = new AtomicReference<>();
// Execute the reactive workflow - start with the configured model
client.startSession(config.model)
.flatMap(session -> {
System.out.println("✓ Session started successfully");
// Create audio processor
AudioProcessor audioProcessor = new AudioProcessor(session);
audioProcessorRef.set(audioProcessor);
// Subscribe to receive server events asynchronously
session.receiveEvents()
.doOnSubscribe(subscription -> System.out.println("🔗 Subscribed to event stream"))
.doOnComplete(() -> System.out.println("⚠️ Event stream completed (this might indicate a connection issue)"))
.doOnError(error -> System.out.println("❌ Event stream error: " + error.getMessage()))
.subscribe(
event -> handleServerEvent(event, audioProcessor),
error -> System.err.println("❌ Error receiving events: " + error.getMessage()),
() -> System.out.println("✓ Event stream completed")
);
System.out.println("📤 Sending session.update configuration...");
ClientEventSessionUpdate updateEvent = new ClientEventSessionUpdate(sessionOptions);
session.sendEvent(updateEvent)
.doOnSuccess(v -> System.out.println("✓ Session configuration sent"))
.doOnError(error -> System.err.println("❌ Failed to send session.update: " + error.getMessage()))
.subscribe();
// Start audio systems
audioProcessor.startPlayback();
System.out.println("🎤 VOICE ASSISTANT READY");
System.out.println("Start speaking to begin conversation");
System.out.println("Press Ctrl+C to exit");
// Install shutdown hook for graceful cleanup
Runtime.getRuntime().addShutdownHook(new Thread(() -> {
System.out.println("\n🛑 Shutting down gracefully...");
audioProcessor.shutdown();
}));
// Keep the reactive chain alive to continue processing events
// Mono.never() prevents the chain from completing, allowing the event stream to run
// The shutdown hook above handles cleanup when the JVM exits (Ctrl+C)
// Note: In production, use a proper signal mechanism (e.g., CountDownLatch, CompletableFuture)
return Mono.never();
})
.doOnError(error -> System.err.println("❌ Error: " + error.getMessage()))
.doFinally(signalType -> {
// Cleanup audio processor
AudioProcessor audioProcessor = audioProcessorRef.get();
if (audioProcessor != null) {
audioProcessor.shutdown();
}
})
.block(); // Block only for demo purposes; use reactive patterns in production
}
/**
* Create session configuration for voice conversation
*/
private static VoiceLiveSessionOptions createVoiceSessionOptions(Config config) {
System.out.println("🔧 Creating session configuration:");
// Create server VAD configuration similar to Python sample
ServerVadTurnDetection turnDetection = new ServerVadTurnDetection()
.setThreshold(0.5)
.setPrefixPaddingMs(400)
.setSilenceDurationMs(500)
.setInterruptResponse(true)
.setAutoTruncate(true)
.setCreateResponse(true);
// Create audio input transcription configuration
AudioInputTranscriptionOptions transcriptionOptions = new AudioInputTranscriptionOptions(AudioInputTranscriptionOptionsModel.WHISPER_1);
VoiceLiveSessionOptions options = new VoiceLiveSessionOptions()
.setInstructions(config.instructions)
// Voice: AzureStandardVoice for Azure TTS voices (e.g., en-US-Ava:DragonHDLatestNeural)
.setVoice(BinaryData.fromObject(new AzureStandardVoice(config.voice)))
.setModalities(Arrays.asList(InteractionModality.TEXT, InteractionModality.AUDIO))
.setInputAudioFormat(InputAudioFormat.PCM16)
.setOutputAudioFormat(OutputAudioFormat.PCM16)
.setInputAudioSamplingRate(SAMPLE_RATE)
.setInputAudioNoiseReduction(new AudioNoiseReduction(AudioNoiseReductionType.NEAR_FIELD))
.setInputAudioEchoCancellation(new AudioEchoCancellation())
.setInputAudioTranscription(transcriptionOptions)
.setTurnDetection(turnDetection);
System.out.println("✓ Session configuration created");
return options;
}
/**
* Handle incoming server events
*/
private static void handleServerEvent(SessionUpdate event, AudioProcessor audioProcessor) {
ServerEventType eventType = event.getType();
try {
if (eventType == ServerEventType.SESSION_CREATED) {
System.out.println("✓ Session created - initializing...");
} else if (eventType == ServerEventType.SESSION_UPDATED) {
System.out.println("✓ Session updated - starting microphone");
// Now that bufferObject() bug is fixed in generated code, we can access the typed class
if (event instanceof SessionUpdateSessionUpdated) {
SessionUpdateSessionUpdated sessionUpdated = (SessionUpdateSessionUpdated) event;
// Print the full JSON representation
System.out.println("📄 Session Updated Event (Full JSON):");
String eventJson = BinaryData.fromObject(sessionUpdated).toString();
System.out.println(eventJson);
}
audioProcessor.startCapture();
} else if (eventType == ServerEventType.INPUT_AUDIO_BUFFER_SPEECH_STARTED) {
System.out.println("🎤 Speech detected");
// Server handles interruption automatically with interruptResponse=true
// Just clear any pending audio in the playback queue
audioProcessor.skipPendingAudio();
} else if (eventType == ServerEventType.INPUT_AUDIO_BUFFER_SPEECH_STOPPED) {
System.out.println("🤔 Speech ended - processing...");
} else if (eventType == ServerEventType.RESPONSE_AUDIO_DELTA) {
// Handle audio response - extract and queue for playback
if (event instanceof SessionUpdateResponseAudioDelta) {
SessionUpdateResponseAudioDelta audioEvent = (SessionUpdateResponseAudioDelta) event;
byte[] audioData = audioEvent.getDelta();
if (audioData != null && audioData.length > 0) {
audioProcessor.queueAudio(audioData);
}
}
} else if (eventType == ServerEventType.RESPONSE_AUDIO_DONE) {
System.out.println("🎤 Ready for next input...");
} else if (eventType == ServerEventType.RESPONSE_DONE) {
System.out.println("✅ Response complete");
} else if (eventType == ServerEventType.ERROR) {
if (event instanceof SessionUpdateError) {
SessionUpdateError errorEvent = (SessionUpdateError) event;
System.out.println("❌ VoiceLive error: " + errorEvent.getError().getMessage());
} else {
System.out.println("❌ VoiceLive error occurred");
}
}
} catch (Exception e) {
System.err.println("❌ Error handling event: " + e.getMessage());
e.printStackTrace();
}
}
}
語音即時 API 會以模型的初始響應開始傳回音訊。 您可以藉由說話來中斷模型。 輸入“Ctrl+C”退出對話。
輸出
應用程式的輸出會印到主控台。 你會看到顯示系統狀態的訊息:
[INFO] Scanning for projects...
[INFO]
[INFO] --------------< com.azure.ai.voicelive:model-quickstart >---------------
[INFO] Building Azure VoiceLive Model Quickstart 1.0.0
[INFO]   from pom.xml
[INFO] --------------------------------[ jar ]---------------------------------
[INFO]
[INFO] --- exec:3.1.0:java (default-cli) @ model-quickstart ---
? Loaded configuration from application.properties
? Audio system check passed
?? Starting Voice Assistant...
   Model: gpt-realtime
   Voice: en-US-Ava:DragonHDLatestNeural
? Using API Key authentication
? Initializing VoiceLive client:
   Endpoint: https://jagoerge-voicelive-weu-resource.services.ai.azure.com/
? VoiceLive client created
? Creating session configuration:
? Session configuration created
[ModelQuickstart.main()] INFO com.azure.ai.voicelive.VoiceLiveSessionAsyncClient - WebSocket connection parameters -> endpoint: wss://my-resource.services.ai.azure.com/voice-live/realtime?api-version=2026-04-10&model=gpt-realtime headers: api-key=0XxX...x0xX
[reactor-http-nio-2] INFO com.azure.ai.voicelive.VoiceLiveSessionAsyncClient - WebSocket connection established
[reactor-http-nio-2] INFO com.azure.ai.voicelive.VoiceLiveSessionAsyncClient - Receive flux subscribed
[reactor-http-nio-2] INFO com.azure.ai.voicelive.VoiceLiveSessionAsyncClient - Send stream subscribed
[reactor-http-nio-2] INFO com.azure.ai.voicelive.VoiceLiveSessionAsyncClient - WebSocket session ready
? Session started successfully
? Subscribed to event stream
? Sending session.update configuration...
? Session configuration sent
? Audio playback started
? VOICE ASSISTANT READY
Start speaking to begin conversation
Press Ctrl+C to exit
? Session created - initializing...
? Session updated - starting microphone
? Session Updated Event (Full JSON):
{"event_id":"event_7VOMH1ALSp5A0Fa17nSZKM","session":{"model":"gpt-realtime","modalities":["audio","text"],"voice":{"name":"en-US-Ava:DragonHDLatestNeural","type":"azure-standard"},"instructions":"You are a helpful AI voice assistant. Respond naturally and conversationally. Keep your responses concise but engaging. Speak as if having a real conversation.","input_audio_sampling_rate":24000,"input_audio_format":"pcm16","output_audio_format":"pcm16","turn_detection":{"type":"server_vad","threshold":0.5,"prefix_padding_ms":400,"silence_duration_ms":500,"auto_truncate":true,"create_response":true,"interrupt_response":true},"input_audio_noise_reduction":{"type":"near_field"},"input_audio_echo_cancellation":{"type":"server_echo_cancellation"},"input_audio_transcription":{"model":"azure-speech","language":""},"tools":[],"tool_choice":"auto","temperature":0.8,"max_response_output_tokens":"inf","id":"sess_7cMSK58ShfrUY1RKnZ6Eoy"},"type":"session.updated"}
? Microphone capture started
? Audio capture loop started
? Speech detected
? Speech ended - processing...
? Ready for next input...
? Response complete
? Speech detected
? Speech ended - processing...
? Ready for next input...
? Response complete
? Speech detected
? Speech ended - processing...
? Ready for next input...
? Speech detected
? Response complete
? Speech ended - processing...

? Shutting down gracefully...
? Audio capture loop ended
? Microphone capture stopped
? Audio playback stopped
記錄設定
範例使用 SLF4J 進行日誌記錄。 預設情況下,日誌等級設為 INFO。 你可以在專案根目錄(與 simplelogger.properties: 的資料夾)建立pom.xml檔案來設定日誌記錄。
# SLF4J Simple Logger Configuration
org.slf4j.simpleLogger.defaultLogLevel=info
org.slf4j.simpleLogger.showDateTime=true
org.slf4j.simpleLogger.dateTimeFormat=yyyy-MM-dd HH:mm:ss:SSS

# Set log level for VoiceLive SDK
org.slf4j.simpleLogger.log.com.azure.ai.voicelive=debug

# Set log level for Azure Core
org.slf4j.simpleLogger.log.com.azure.core=info
要啟用除錯日誌,請將日誌層級改為 debug:
org.slf4j.simpleLogger.defaultLogLevel=debug
清理資源
完成快速入門後,你可以刪除你建立的資源:
rm -rf voice-live-quickstart
相關內容
- 試試 Voice Live 客服人員的快速啟動功能
- 了解更多如何使用 Voice Live API
- 請參閱 Voice Live API 參考資料