Σημείωμα
Η πρόσβαση σε αυτήν τη σελίδα απαιτεί εξουσιοδότηση. Μπορείτε να δοκιμάσετε να εισέλθετε ή να αλλάξετε καταλόγους.
Η πρόσβαση σε αυτήν τη σελίδα απαιτεί εξουσιοδότηση. Μπορείτε να δοκιμάσετε να αλλάξετε καταλόγους.
You can use Classification to classify your documents into predefined categories with AI.
Examples of classification include:
- Classifying customer call transcripts by intent
- Classifying documents by content type
- Classifying product reviews by sentiment
Classification is available through the Agent Bricks UI, in SQL, with the REST API, and with the Asynchronous API (Beta).
Create a classification agent in the UI
Requirements
- A workspace that includes the following:
- Serverless compute enabled. See Serverless compute requirements.
- Unity Catalog enabled. See Enable a workspace for Unity Catalog.
- Access to a serverless usage policy with a nonzero budget.
- This function is only available in some regions, see AI function availability.
- For workspaces with the Enhanced Security and Compliance add-on,
- See regional support for
ai_classifyfor the appropriate compliance standard. - See Manage Azure Databricks previews for how to enable it on your workspace.
- See regional support for
- Ability to use the
ai_classifySQL function. - Unstructured data that you want to classify. The data must be in a Unity Catalog volume or table.
- To build your agent, you need at least 1 unlabeled document in your Unity Catalog volume or 1 row in your table.
Go to  Agents in the left navigation pane of your workspace. Click Create Agent, and select Text Classification.
Step 1. Select your source data
Use Classification to classify your documents.
Select your source data. You can select a volume with documents or a table with text data.
Click Create Agent.
Step 2. Configure classification labels
After Classification processes your data, configure and refine your classification labels.
To add classification labels manually:
- Click + Add label to add a classification label.
- Enter the label name and optional description, then click Add label.
- Repeat 1-2 for each label you want to add.
- (Optional) Enable Multiple labels if you want the agent to return more than one label.
To import labels from a table:
- Click Import from table.
- Select the table and click Next.
- Select the label column, description column, and SQL warehouse.
- Click Preview to see the labels that are imported.
- If you're happy with the labels, click Import and replace labels.
You must have at least two labels defined to run classification. After you've finished adding your labels, click Save and run classification.
To configure additional options, click the options toggle  next to Save and run classification, then enable one or more of the following options:
- Confidence scores: Shows confidence levels for predicted labels.
- Rationales: Shows justification for predicted labels.
Classification classifies up to 5 documents and rows and displays the results. You can add more as well.
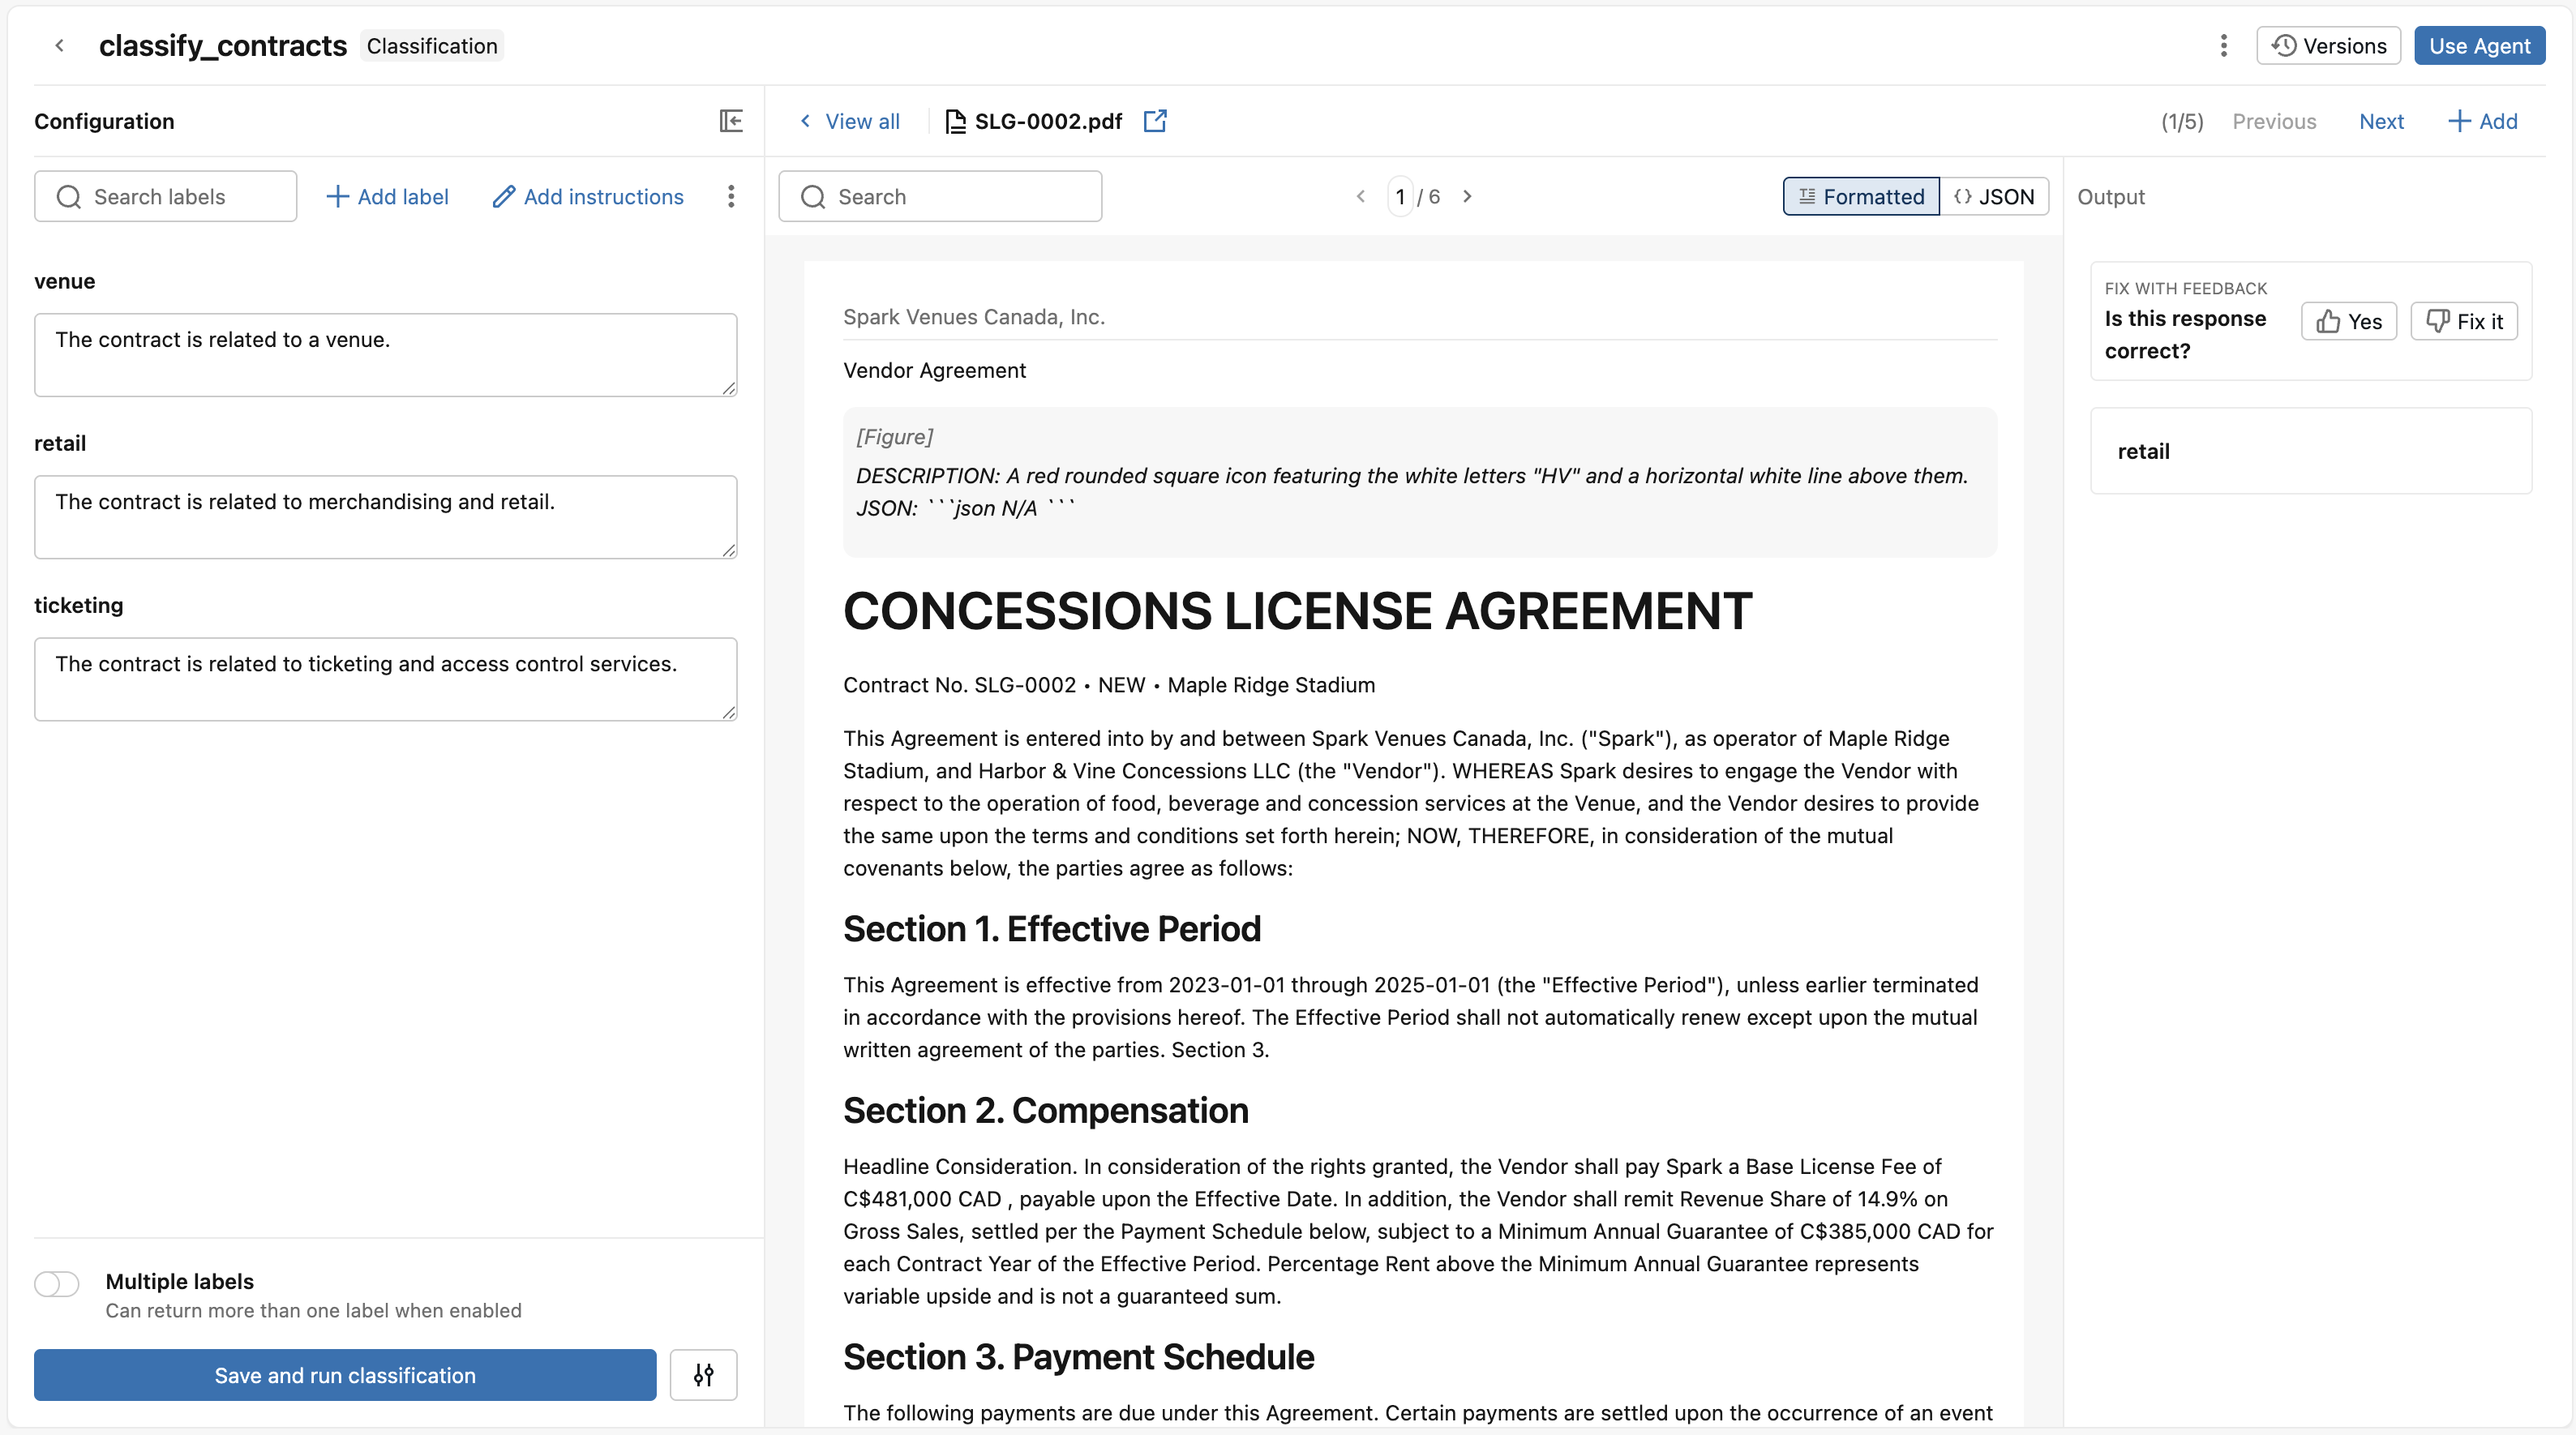
Step 3. Review and improve classification responses
Review the classification responses and give feedback to improve the agent.
Review the document and classification response:
- If the response is correct, give it a thumbs up.
- If the response is incorrect, give it a thumbs down. Help Classification fix the response by selecting the correct label. Click Save.
To improve the agent's responses, adjust the classification label descriptions.
Compare versions to optimize the agent's performance. Click Versions. Next to a previous version, click Compare to compare the classification label descriptions of a previous version with the current version. Click Restore to restore a previous version.
Step 4. Use the classification agent
If you're happy with the responses, start using the agent for classification at scale.
Click Use Agent in the upper-right. You can choose either:
- Run in SQL to use the agent to classify your entire volume or table. This opens a SQL query that uses
ai_classifyusing the classification labels you defined. For more information on usingai_classifyin SQL queries, seeai_classifyfunction. - Create a Lakeflow pipeline that runs on scheduled intervals to invoke your agent on new data. This creates a Lakeflow pipeline that updates a streaming table with your classified data. You can configure the pipeline's schedule so that it runs when new data arrives. For more information on Lakeflow pipelines, see Spark Declarative Pipelines on Lakeflow.
Classify documents in SQL
Call ai_classify in SQL to classify documents at scale:
SELECT ai_classify(
  'My password is leaked.',
  '["urgent", "not_urgent"]',
  MAP('version', '2.1')
);
See the ai_classify SQL reference.
Classify documents with the REST API
Use the REST API to classify documents from applications, services, and automation workflows. See the REST API docs for reference.
The default rate limit for ai_classify REST API requests is 1,200 requests per minute per workspace. Contact your Databricks account team to request a higher limit.
The following example classifies a customer support message:
curl -X POST "$DATABRICKS_HOST/api/2.0/ai-functions/ai-classify" \
     -H "Authorization: Bearer $DATABRICKS_TOKEN" \
     -H "Content-Type: application/json" \
     -d '{
  "content": "My password is leaked.",
  "labels": ["urgent", "not_urgent"],
  "options": {
    "instructions": "Classify the support request by urgency."
  }
}'
Classify documents with the Asynchronous API (Beta)
Use the AI Functions Asynchronous API (Beta) to classify many texts in one batch. For the request and response fields, and for the requests to cancel and list batches, see the Asynchronous API reference. A workspace admin must turn on the AI Functions Asynchronous API preview on the Previews page.
Note
To classify the rows of a Unity Catalog table in a job, you can use an ai_classify task (Beta) instead. The task reads from and writes to Unity Catalog tables for you, and each run processes only the rows that are new or changed.
To classify texts with the Asynchronous API:
Create a JSONL input file with one line for each text. Each line has a unique
custom_idand the text inbody.text:{"custom_id": "ticket-001", "body": {"text": "My password is leaked."}} {"custom_id": "ticket-002", "body": {"text": "How do I change my billing address?"}}Upload the input file to a Unity Catalog volume, for example with the Files API.
Create a batch that runs
ai_classifyon the input file. Thelabelsandoptionsinparamsapply to every line, andoutput_refis the volume directory for the results:curl -X POST "$DATABRICKS_HOST/api/2.0/ai-functions/batches" \ -H "Authorization: Bearer $DATABRICKS_TOKEN" \ -H "Content-Type: application/json" \ -d '{ "endpoint": "ai_classify", "input_ref": "/Volumes/my_catalog/my_schema/my_volume/requests.jsonl", "params": { "labels": ["urgent", "not_urgent"], "options": { "instructions": "Classify the support request by urgency." } }, "output_ref": "/Volumes/my_catalog/my_schema/my_volume/output/" }'The response contains the batch
name. Use it in place of<batch-name>in the next steps.Check the status of the batch. The batch is finished when
statusisCOMPLETED,CANCELLED, orFAILED:curl -X GET "$DATABRICKS_HOST/api/2.0/ai-functions/batches/<batch-name>" \ -H "Authorization: Bearer $DATABRICKS_TOKEN"When the output file is ready,
output_refin the response contains its path.Download the output file with the Files API:
curl -X GET "$DATABRICKS_HOST/api/2.0/fs/files/Volumes/my_catalog/my_schema/my_volume/output/<batch-name>_output.jsonl" \
     -H "Authorization: Bearer $DATABRICKS_TOKEN" \
     -o output.jsonl
The output file has one line for each line of the input file. The lines are in the same order as the input file. Each line has the custom_id of its request and one of the following fields:
response: The result of the request. It has the same fields as the AI Classify REST API response.error: Thetypeandmessageof the error, if the request failed.
The following example shows a line for a request that succeeded and a line for a request that failed:
{"custom_id": "ticket-001", "response": {...}}
{"custom_id": "ticket-002", "error": {"type": "request_failed", "message": "..."}}
Limitations
See Limitations