Note
Access to this page requires authorization. You can try signing in or changing directories.
Access to this page requires authorization. You can try changing directories.
The Microsoft Discovery resource provider introduces several new Azure Resource Manager (ARM) object types within your subscription. These resources provide the foundation for Microsoft Discovery's user experience, agentic AI, and computational layers, and can be deployed and managed like any other Azure resource in your subscription.
Architecture layers
Microsoft Discovery is organized into three functional layers, each backed by dedicated ARM resource types:
User experience layer - Workspaces serve as the primary entry point for both web-based interaction through Discovery Studio and programmatic access through APIs and Azure CLI.
Agentic AI layer - Projects organize agents, investigations, and shared sessions. Agents reference shared knowledge bases. Chat Models provide the foundational language model deployments that agents use for reasoning. Bookshelves supply proprietary knowledge graphs that ground agent reasoning in customer data.
Computational layer - Supercomputers provide the high-performance compute platform where Tools are executed. Storage Containers and Storage Assets manage the input and output data that flows through tool execution and agent workflows.
Resource model
The following diagram shows the Microsoft Discovery resource model and the relationships between resource types. Relationships include references to shared resources, not just ARM parent-child relationships. Projects and chat model deployments are workspace children. Supercomputers, bookshelves, tools, and storage containers are separate resource-group-level resources.
Agents, investigations, shared sessions, and tasks are project-owned data-plane resources, not additional ARM resource types. For the ARM types and API versions, see the Microsoft Discovery resource reference.
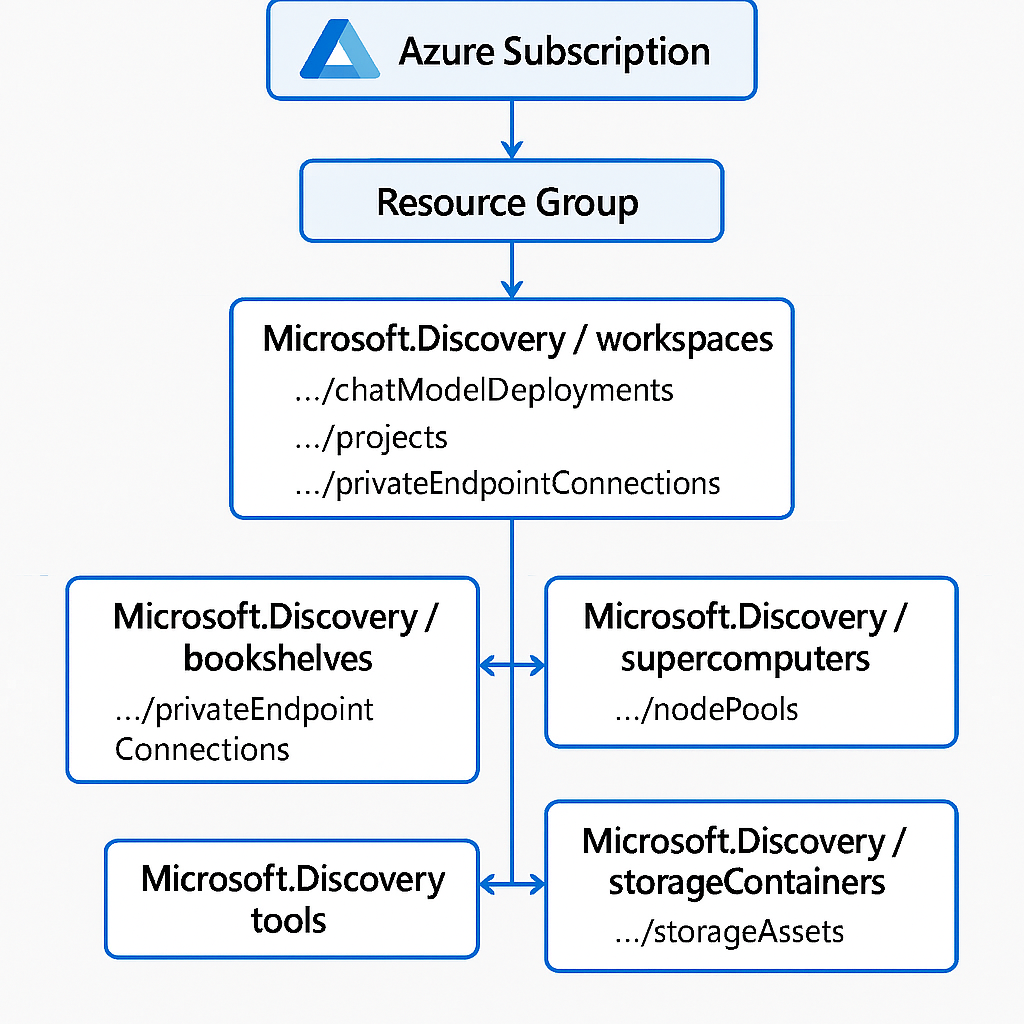
Resource descriptions
| Resource | Description |
|---|---|
| Workspace | The primary entry point for web-based (Discovery Studio) and programmatic interaction with Microsoft Discovery. Provides shared networking, compute, and model infrastructure for all projects. |
| Supercomputer | The high-performance computational platform for Microsoft Discovery, built on Azure Kubernetes Service. Executes tool workloads on behalf of agents. |
| Project | The research organizational and access boundary within a workspace. Contains project-owned agents, investigations, shared sessions, and tasks, and references shared resources. |
| Tool | A computational workload definition referenced by agents. Container images used by the definition are stored in a registry accessible to the supercomputer. |
| Chat Model | A workspace-level deployment of a foundational language model used by agents for reasoning, planning, and task execution. |
| Storage Container | A resource-group-level ARM resource that references a storage backend, such as an Azure Storage account, and groups storage assets. |
| Storage Asset | A child ARM resource of a storage container that references a path in the backing storage. |
| Bookshelf | Holds a customer's collection of curated proprietary data, indexed into knowledge graphs known as Knowledge Bases (KBs) using GraphRAG algorithms. |
Resource details
Workspace
A workspace is a top-level ARM resource in Microsoft Discovery. It acts as the shared infrastructure boundary for its projects, providing:
- The networking configuration (virtual network and subnets) for workspace services
- References to supercomputers and workspace-level chat model deployments used by projects
- The access control layer for platform administrators
You interact with a workspace through Discovery Studio or programmatically via the Microsoft Discovery API, Azure CLI, or Bicep templates.
Supercomputer
The Supercomputer is the computational engine of Microsoft Discovery. Built on Azure Kubernetes Service (AKS), it provides the managed execution environment where tool workloads run. Key characteristics:
- Associated with a workspace by reference and available to its projects
- Executes containerized tool workloads on behalf of agents
- Supports node pool configuration for different compute SKUs and workload types
- Managed independently from project resources, allowing platform administrators to scale compute without disrupting research workflows
For management details, see Manage Supercomputer & Nodepools.
Project
A project is the primary organizational unit for scientific research within a workspace. It defines an access boundary for project-owned resources. Projects:
- Consume workspace-level infrastructure (supercomputer, chat models, networking)
- Contain agents, investigations, shared sessions, and tasks
- Reference storage containers through
storageContainerIds; agents reference approved tools and knowledge bases outside project scope - Can't share agents directly with other projects, though agents can be cloned between projects
Project access doesn't automatically grant access to shared resources or their backing data. For ownership and reference relationships, see Projects and shared sessions. For companion roles and inherited permissions, see Project-level access control.
Tool
Tools enable agents to perform specific, repeatable tasks such as running simulations, processing scientific data, or executing complex algorithms. The two tool authoring types are:
- Action-based tools - packaged as Docker containers in Azure Container Registry, used for commercial or complex software packages
- Code-environment based tools - enable agents to dynamically generate and execute code
A hybrid tool combines these approaches. It isn't a third authoring type. Model integration patterns such as OpenAPI and MCP describe how an agent reaches a model or service, rather than additional Discovery tool types.
Tool definitions are resource-group-level ARM resources and can be shared across projects. For details, see Discovery Tool concepts.
Chat Model
Chat models are workspace-level ARM resources that represent deployments of foundational language models (such as GPT-5) from Microsoft Foundry or Azure OpenAI. Agents reference these shared deployments. Consider the following information about chat models:
- Deployments are created at the workspace level and referenced by agents using the deployment name
- Multiple models can be deployed within a single workspace, allowing agents to use different models for different tasks
- Model selection affects both cost and reasoning capability for agent workflows
For guidance on choosing models, see Select models for agents.
Storage Container
A storage container is a resource-group-level ARM resource that registers a reference to a storage backend. For Azure Blob Storage, the reference identifies the storage account, and storage assets identify paths within it. Registration doesn't move or copy the underlying data. Storage containers:
- Exist outside project scope and can be referenced by projects for investigation inputs and outputs
- Provide the input and output storage selected when creating a project in Discovery Studio
- Back the file-based data that agents and tools read from and write to
For details, see Storage containers and storage assets.
Storage Asset
A storage asset is an ARM child resource of a storage container that references a path in the backing storage. Storage assets:
- Enable agents to reference and operate on specific data objects within an investigation
- Support various file formats used in scientific research workflows
- Are the output targets for tool execution within the Discovery platform
Bookshelf
The Bookshelf is a Microsoft Discovery service that converts customer data into curated knowledge graphs known as Knowledge Bases (KBs). Bookshelves use GraphRAG (Graph Retrieval-Augmented Generation), a technique developed by Microsoft Research, to index data into both a vector database and a knowledge graph. Key Bookshelf characteristics:
- Supports a wide range of unstructured file formats (PDF, DOCX, TXT, XLSX, and more)
- Knowledge Bases are used by agents as grounding sources for reasoning and hypothesis generation
- Best suited for curated, thematically focused proprietary data directly applicable to a research workflow
For details, see Bookshelf & Knowledge Bases.