在本文中,您將學習如何使用 Apache Spark
本教學課程涵蓋了下列步驟:
- 設定筆記本並匯入項目
- 載入並取樣紐約市計程車資料
- 準備及設計功能
- 編碼類別型特徵
- 列車邏輯迴歸模型
- 評估並視覺化結果
核心 SparkML 和 MLlib SparkMLlib 程式庫提供許多可用於機器學習工作的工具。 這些公用程式適用於:
- 分類
- 叢集
- 假設測試和計算範例統計資料
- 迴歸
- 奇異值分解 (SVD) 和主體元件分析 (PCA)
- 主題模型化
先決條件
取得 Microsoft Fabric 訂用帳戶。 或註冊免費的 Microsoft Fabric 試用版。
登入 Microsoft Fabric。
使用首頁左下角的體驗切換器切換到 Fabric。
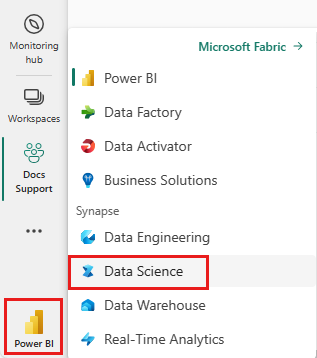
- 如果有需要,請依照Create a lakehouse in Microsoft Fabric中所述,在 Microsoft Fabric 中建立湖屋。
- 在您的工作區中,選取 +,然後選取 筆記本,以建立新的筆記本。 欲了解更多資訊,請參閱 建立筆記本。
了解分類和邏輯迴歸
分類是常見的機器學習工作,涉及將輸入資料依類別排序。 分類演算法會找出如何為所提供輸入資料指派 標籤 的方法。 例如,機器學習演算法可以接受股票資訊作為輸入,並將股票分為兩類:應該賣出的股票和應該保留的股票。
邏輯斯迴歸演算法對分類非常有用。 Spark 的羅吉斯迴歸 API 可用於二元分類,將輸入資料歸類到兩個群組之一。 如需有關羅吉斯迴歸的詳細資訊,請參閱 Wikipedia。
邏輯斯迴歸會產生一個 logistic 函數,用來預測輸入向量屬於兩個群組其中一組的機率。
紐約市計程車資料的預測性分析範例
此資料可透過 Azure 開放資料集資源取得。 此資料集子集裝載黃色計程車車程的相關資訊,包括開始時間、結束時間、開始位置、結束位置、車程成本和其他屬性。
本教學使用 Apache Spark 分析紐約市計程車小費資料,並建立模型來預測特定行程是否包含小費。
建立 Apache Spark 機器學習模型
建立 PySpark 筆記本。 欲了解更多資訊,請參閱 建立筆記本。
建立筆記本後,在左側面板選擇 「新增湖屋 」,將其附加到湖屋上。
匯入此筆記本所需的型別。 把以下程式碼貼到第一個儲存格並執行。
import matplotlib.pyplot as plt from pyspark.sql.functions import unix_timestamp, date_format, col, when from pyspark.ml import Pipeline from pyspark.ml.feature import RFormula from pyspark.ml.feature import OneHotEncoder, StringIndexer from pyspark.ml.classification import LogisticRegression from pyspark.ml.evaluation import BinaryClassificationEvaluator驗證:該單元在沒有
ImportError的情況下完備。 如果你看到錯誤,請確認你的筆記本是否使用 PySpark 執行時。使用 MLflow 來追蹤你的機器學習實驗和相應的執行。 如果已啟用 Microsoft Fabric 自動記錄,系統會自動擷取對應的計量和參數。
import mlflow驗證:儲存格完整且無錯誤。 執行
print(mlflow.__version__)以確認 MLflow 可用。
建立輸入的 DataFrame
此範例將 Azure 開放資料集 儲存的資料載入 Apache Spark DataFrame。 接著,你要用 Spark 操作來清理和篩選資料集。
將以下程式碼貼到新儲存格,執行以建立 Spark DataFrame。 此步驟可取得篩選至2018年5月的紐約市黃色計程車資料。
blob_account_name = "azureopendatastorage" blob_container_name = "nyctlc" blob_relative_path = "yellow" wasbs_path = f"wasbs://{blob_container_name}@{blob_account_name}.blob.core.windows.net/{blob_relative_path}" nyc_tlc_df = spark.read.parquet(wasbs_path) \ .filter((col("tpepPickupDateTime") >= "2018-05-01") & (col("tpepPickupDateTime") < "2018-06-01")) \ .repartition(20)驗證:執行以下儲存格以確認資料載入成功。
print(f"Loaded {nyc_tlc_df.count()} rows")
# Expected output: Loaded approximately 9,000,000+ rows
取樣資料集以加快開發與訓練。
# Sample without replacement to avoid duplicates sampled_taxi_df = nyc_tlc_df.sample(False, 0.001, seed=1234)驗證:確認樣本量是否可管理。
print(f"Sampled {sampled_taxi_df.count()} rows")
# Expected output: Sampled approximately 9,000-10,000 rows
使用內建
display()指令瀏覽資料樣本。display(sampled_taxi_df.limit(10))驗證:會出現一個有 10 列的表格,顯示欄位如
tpepPickupDateTime、fareAmount、tipAmounttripDistance、 和 。
準備資料
資料準備是機器學習程序中的重要步驟。 它涉及清理、轉換並組織原始資料,使其適合分析與建模。 在本節中,執行數個資料準備步驟:
- 過濾資料集以移除異常值和錯誤值。
- 移除不需要用於模型訓練的欄位。
- 從原始資料建立新的欄位。
- 產生標籤來判斷某趟計程車是否包含小費。
執行以下程式碼以選擇相關欄位、計算衍生特徵,並過濾離群值:
taxi_df = sampled_taxi_df.select('totalAmount', 'fareAmount', 'tipAmount', 'paymentType', 'rateCodeId', 'passengerCount',
                    'tripDistance', 'tpepPickupDateTime', 'tpepDropoffDateTime',
                    date_format('tpepPickupDateTime', 'HH').cast('integer').alias('pickupHour'),
                    date_format('tpepPickupDateTime', 'EEEE').alias('weekdayString'),
                    (unix_timestamp(col('tpepDropoffDateTime')) - unix_timestamp(col('tpepPickupDateTime'))).alias('tripTimeSecs'),
                    (when(col('tipAmount') > 0, 1).otherwise(0)).alias('tipped')
                    ) \
            .filter((sampled_taxi_df.passengerCount > 0) & (sampled_taxi_df.passengerCount < 8)
                    & (sampled_taxi_df.tipAmount >= 0) & (sampled_taxi_df.tipAmount <= 25)
                    & (sampled_taxi_df.fareAmount >= 1) & (sampled_taxi_df.fareAmount <= 250)
                    & (sampled_taxi_df.tipAmount < sampled_taxi_df.fareAmount)
                    & (sampled_taxi_df.tripDistance > 0) & (sampled_taxi_df.tripDistance <= 100)
                    & (sampled_taxi_df.rateCodeId <= 5)
                    & (sampled_taxi_df.paymentType.isin({"1", "2"}))
                    )
Important
該 date_format 函數使用模式 'HH' (24小時格式,值0-23)而非 'hh' (12小時格式,值1-12)。 24 小時格式是後續時間分區邏輯所必需的。
接著,根據一天中的時段加入交通時間箱功能:
taxi_featurised_df = taxi_df.select('totalAmount', 'fareAmount', 'tipAmount', 'paymentType', 'passengerCount',
                                    'tripDistance', 'weekdayString', 'pickupHour', 'tripTimeSecs', 'tipped',
                                    when((col('pickupHour') <= 6) | (col('pickupHour') >= 20), "Night")
                                    .when((col('pickupHour') >= 7) & (col('pickupHour') <= 10), "AMRush")
                                    .when((col('pickupHour') >= 11) & (col('pickupHour') <= 15), "Afternoon")
                                    .when((col('pickupHour') >= 16) & (col('pickupHour') <= 19), "PMRush")
                                    .otherwise("Other").alias('trafficTimeBins')
                                    ) \
                            .filter((taxi_df.tripTimeSecs >= 30) & (taxi_df.tripTimeSecs <= 7200))
驗證:確認流量時間區塊分配正確。
taxi_featurised_df.groupBy('trafficTimeBins').count().show()
# Expected output: Shows counts for Night, AMRush, Afternoon, PMRush categories
建立羅吉斯迴歸模型
最終工作會將標示的資料轉換成羅吉斯迴歸可以處理的格式。 羅吉斯迴歸演算法的輸入必須具有標籤/特徵向量組結構,其中特徵向量是代表輸入點的數字向量。
將類別欄位 trafficTimeBins 和 weekdayString 轉換為整數表示,方法是:OneHotEncoder
# Convert categorical features into numeric representations
sI1 = StringIndexer(inputCol="trafficTimeBins", outputCol="trafficTimeBinsIndex")
en1 = OneHotEncoder(inputCol="trafficTimeBinsIndex", outputCol="trafficTimeBinsVec")
sI2 = StringIndexer(inputCol="weekdayString", outputCol="weekdayIndex")
en2 = OneHotEncoder(inputCol="weekdayIndex", outputCol="weekdayVec")

# Apply the encodings to create a new DataFrame
encoded_final_df = Pipeline(stages=[sI1, en1, sI2, en2]).fit(taxi_featurised_df).transform(taxi_featurised_df)
驗證:確認編碼後的資料框架是否具備預期的新欄位。
print("Columns:", encoded_final_df.columns)
print(f"Row count: {encoded_final_df.count()}")
# Expected output: Columns list includes 'trafficTimeBinsVec' and 'weekdayVec'
訓練羅吉斯迴歸模型
將資料集拆分為訓練集(70 個%)和一個測試集(30%):
# Split the DataFrame into training and test sets
trainingFraction = 0.7
testingFraction = (1 - trainingFraction)
seed = 1234

train_data_df, test_data_df = encoded_final_df.randomSplit([trainingFraction, testingFraction], seed=seed)
確認:確認分拆產生的尺寸是否合理。
print(f"Training rows: {train_data_df.count()}, Test rows: {test_data_df.count()}")
# Expected output: Approximately 70%/30% split of the encoded data
建立模型公式,訓練邏輯迴歸模型,並利用 ROC(接收者操作特徵)曲線下的面積來評估:
# Create a logistic regression model
logReg = LogisticRegression(maxIter=10, regParam=0.3, labelCol='label')

# Define the formula: 'tipped' is the response variable, right-hand side are predictors
classFormula = RFormula(formula="tipped ~ pickupHour + weekdayVec + passengerCount + tripTimeSecs + tripDistance + fareAmount + paymentType + trafficTimeBinsVec")

# Train the model using a pipeline
lrModel = Pipeline(stages=[classFormula, logReg]).fit(train_data_df)

# Generate predictions on the test dataset
predictions = lrModel.transform(test_data_df)

# Evaluate using Area Under ROC
evaluator = BinaryClassificationEvaluator(rawPredictionCol="rawPrediction", metricName="areaUnderROC")
auc = evaluator.evaluate(predictions)
print(f"Area under ROC = {auc}")
驗證:輸出顯示 AUC 值。 一個表現良好的模型會產生接近 1.0 的數值。
Area under ROC = 0.97 (approximately)
Note
具體的AUC值會依資料樣本而異。 值高於 0.90 表示該資料集的預測表現良好。
建立預測的視覺表示法
建立最終的視覺化以解讀模型結果。 ROC曲線呈現真陽性率與假陽性率之間的權衡。
# Plot the ROC curve from the model training summary
modelSummary = lrModel.stages[-1].summary

# Extract FPR and TPR values as plain lists
roc_data = modelSummary.roc.select('FPR', 'TPR').toPandas()

plt.figure(figsize=(8, 6))
plt.plot([0, 1], [0, 1], 'r--', label='Random classifier')
plt.plot(roc_data['FPR'], roc_data['TPR'], label=f'Logistic Regression (AUC = {auc:.4f})')
plt.xlabel('False Positive Rate')
plt.ylabel('True Positive Rate')
plt.title('ROC Curve - NYC Taxi Tip Prediction')
plt.legend(loc='lower right')
plt.show()
驗證:顯示紅色虛線對角線上方的 ROC 曲線圖。 曲線應向左上角彎曲,顯示出優異的分類表現。

清理資源
完成這個教學後,刪除筆記本和 Lakehouse 以釋放工作空間容量:
- 在你的工作區裡,右鍵點選筆記本並選擇 刪除。
- 如果你是特地為本教學建立此湖屋,請以滑鼠右鍵按一下它,然後選取 刪除。
為了保留訓練好的模型以備未來使用,請在清理前加入以下程式碼:
# Save the model to the lakehouse
model_path = "abfss://<your-workspace>@onelake.dfs.fabric.microsoft.com/<your-lakehouse>.Lakehouse/Files/models/taxi_tip_model"
lrModel.write().overwrite().save(model_path)
print(f"Model saved to: {model_path}")
Troubleshooting
| Issue | 原因 | 解決方法 |
|---|---|---|
Py4JJavaError 讀 Parquet 時 |
Azure Blob 儲存體的網路連線 | 確認你的 Fabric 工作區有外接網路。 試著重新啟動 Spark session。 |
AnalysisException: cannot resolve column |
欄位名稱的錯字或結構不符 | 跑 nyc_tlc_df.printSchema() 去檢查可用的欄位。 紐約市計程車資料集架構可能在不同年份之間有所變動。 |
| 篩選後的空資料框 | 過濾條件對資料視窗來說過於限制 | 在篩選前請擴大日期範圍或檢查 sampled_taxi_df.count() 。 |
IllegalArgumentException 位於 StringIndexer 中 |
轉換過程中看不見的標籤 | 將 handleInvalid="skip" 加入您的 StringIndexer 呼叫中:StringIndexer(inputCol="...", outputCol="...", handleInvalid="skip") |
| 低AUC(低於0.6) | 資料不足或特徵工程錯誤 | 提高樣本比例(例如, 0.01 取代 0.001),並驗證 trafficTimeBins 類別是否平衡。 |
OutOfMemoryError |
資料集容量過大,無法滿足可用容量 | 減少樣本比例或提升你的 Fabric 容量等級。 |
| ROC 圖未顯示 | 筆記本中的 Matplotlib 後端問題 | 在筆記本頂端加上 %matplotlib inline 。 |