SparkR 是一個 R 套件,提供輕量級前端,讓 R 的 Apache Spark 使用。SparkR 提供分散式資料框架實作,支援選擇、過濾、聚合等操作。 SparkR 也支援使用 MLlib 進行分散式機器學習。
透過 Spark 批次工作定義或互動式 Microsoft Fabric 筆記本使用 SparkR。
R 支援僅在 Spark 3.1 或更新版本中提供。 Spark 2.4 裡的 R 不支援。
必要條件
訂閱Microsoft Fabric。 或者,註冊免費的Microsoft Fabric試用。
使用首頁左下角的體驗切換器切換到 Fabric。
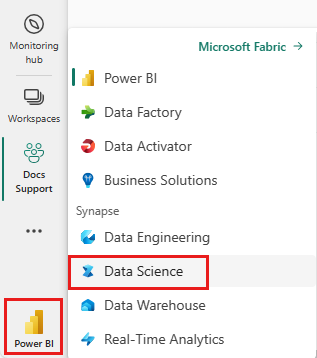
開啟或建立筆記本。 想了解如何使用,請參見如何使用Microsoft Fabric筆記本。
將語言選項設定為 SparkR (R),以變更主要語言。
將筆記本連結至 Lakehouse。 在左側選取 [新增] 以新增現有的 Lakehouse 或建立 Lakehouse。
讀取和寫入 SparkR DataFrame
從本地 R 的 data.frame 讀取 SparkR DataFrame
建立 DataFrame 的最簡單方法是將本機 R data.frame 轉換為 Spark DataFrame。
# load SparkR package
library(SparkR)

# read a SparkR DataFrame from a local R data.frame
df <- createDataFrame(faithful)

# displays the content of the DataFrame
display(df)
從 Lakehouse 讀取和寫入 SparkR DataFrame
你可以將資料儲存在叢集節點的本地檔案系統中。 若要從 Lakehouse 讀取及寫入 SparkR DataFrame,請使用 read.df 和 write.df 方法。 這些方法採用要載入的檔案的路徑以及資料來源的類型。 SparkR 支援原生讀取 CSV、JSON、文字及 Parquet 檔案。
要讀取和寫入 Lakehouse,請先將其新增至您的工作階段。 在筆記本左側,選取 [新增],以新增現有的 Lakehouse 或建立 Lakehouse。
注意
若要使用 Spark 套件(如 read.df 或 write.df)存取 Lakehouse 檔案,請使用 ABFS 路徑 或 Spark 的相對路徑。 在 Lakehouse 檔案總管中,右鍵點擊你想存取的檔案或資料夾,然後從快捷鍵選單複製它的 ABFS 路徑 或 Spark 的相對路徑 。
# write data in CSV using relative path for Spark
temp_csv_spark<-"Files/data/faithful.csv"
write.df(df, temp_csv_spark ,source="csv", mode = "overwrite", header = "true")

# read data in CSV using relative path for Spark
faithfulDF_csv <- read.df(temp_csv_spark, source= "csv", header = "true", inferSchema = "true")

# displays the content of the DataFrame
display(faithfulDF_csv)
# write data in parquet using an ABFS path
temp_parquet_spark<-"abfss://xxx/xxx/data/faithful.parquet"
write.df(df, temp_parquet_spark ,source="parquet", mode = "overwrite", header = "true")

# read data in parquet using an ABFS path
faithfulDF_pq <- read.df(temp_parquet_spark, source= "parquet", header = "true", inferSchema = "true")

# displays the content of the DataFrame
display(faithfulDF_pq)
Microsoft Fabric 已經預裝了 tidyverse。 你可以在熟悉的 R 套件中存取 Lakehouse 檔案,例如透過使用 readr::read_csv() 和 readr::write_csv()來讀寫 Lakehouse 檔案。
注意
要使用 R 套件存取 Lakehouse 檔案,你需要使用 File API 路徑。 在 Lakehouse 檔案總管中,右鍵點擊你想存取的檔案或資料夾,並從情境選單複製其 檔案 API 路徑 。
# read data in CSV using API path
# To find the path, navigate to the csv file, right click, and  Copy File API path.
temp_csv_api<-'/lakehouse/default/Files/data/faithful.csv/part-00000-d8e09a34-bd63-41bd-8cf8-f4ed2ef90e6c-c000.csv'
faithfulDF_API <- readr::read_csv(temp_csv_api)

# display the content of the R data.frame
head(faithfulDF_API)
你也可以使用 SparkSQL 查詢來讀取 Lakehouse 中的 SparkR DataFrame。
# Register earlier df as temp view
createOrReplaceTempView(df, "eruptions")

# Create a df using a SparkSQL query
waiting <- sql("SELECT * FROM eruptions")

head(waiting)
DataFrame 操作
SparkR DataFrame 支援透過多個函數來執行結構化資料處理。 以下是一些基本範例。 SparkR API 檔案中有完整的清單。
選取列和行
# Select only the "waiting" column
head(select(df,df$waiting))
# Pass in column name as strings
head(select(df, "waiting"))
# Filter to only retain rows with waiting times longer than 70 mins
head(filter(df, df$waiting > 70))
群組和彙總
SparkR 資料框架支援許多常用函數,以在分組之後彙總資料。 例如,你可以計算 faithful 資料集中等待時間的直方圖,如以下範例所示。
# we use the `n` operator to count the number of times each waiting time appears
head(summarize(groupBy(df, df$waiting), count = n(df$waiting)))
# we can also sort the output from the aggregation to get the most common waiting times
waiting_counts <- summarize(groupBy(df, df$waiting), count = n(df$waiting))
head(arrange(waiting_counts, desc(waiting_counts$count)))
欄位作業
SparkR 提供許多功能,可以直接套用到欄位進行資料處理與彙整。 下列範例顯示如何使用基本計算函數。
# convert waiting time from hours to seconds.
# you can assign this to a new column in the same DataFrame
df$waiting_secs <- df$waiting * 60
head(df)
套用使用者定義的函數
SparkR 支援多種使用者定義的函數:
在具有 dapply 或 dapplyCollect 的大型資料集上執行函數
dapply
將函數套用至 SparkDataFrame 的每個分割區。 套用到每個分割 SparkDataFrame 區的函數應該只有一個參數,對應每個分割區的 data.frame。 函數的輸出應該是 data.frame。 結構描述會指定產生的 SparkDataFrame 的資料列格式。 它必須與回傳值的資料 型態 相符。
# convert waiting time from hours to seconds
df <- createDataFrame(faithful)
schema <- structType(structField("eruptions", "double"), structField("waiting", "double"),
                     structField("waiting_secs", "double"))

# apply UDF to DataFrame
df1 <- dapply(df, function(x) { x <- cbind(x, x$waiting * 60) }, schema)
head(collect(df1))
dapplyCollect
如同 dapply,對 SparkDataFrame 的每個分區套用函數,並將結果收集回來。 函數的輸出應該是 data.frame。 但這次,你不需要通過圖式。 請注意,如果無法將在所有分割區上執行該函式所產生的輸出擷取到驅動程式,並放入驅動程式記憶體中,dapplyCollect 可能會失敗。
# convert waiting time from hours to seconds
# apply UDF to DataFrame and return a R's data.frame
ldf <- dapplyCollect(
         df,
         function(x) {
           x <- cbind(x, "waiting_secs" = x$waiting * 60)
         })
head(ldf, 3)
在依具有 gapply 或 gapplyCollect 的輸入資料行分組的大型資料集上執行函數
gapply
將函數套用至 SparkDataFrame 的每個组。 應用於每個群組 SparkDataFrame 的函數應該只有兩個參數:分組鍵和對應該鍵的 R data.frame 。 你可以從 SparkDataFrames 欄位中選擇群組。 函數的輸出應該是 data.frame。 結構描述會指定產生的 SparkDataFrame 的資料列格式。 它必須代表 R 函數從 Spark 資料型態的輸出結構。 你設定了返回 data.frame的欄位名稱。
# determine six waiting times with the largest eruption time in minutes.
schema <- structType(structField("waiting", "double"), structField("max_eruption", "double"))
result <- gapply(
    df,
    "waiting",
    function(key, x) {
        y <- data.frame(key, max(x$eruptions))
    },
    schema)
head(collect(arrange(result, "max_eruption", decreasing = TRUE)))
gapplyCollect
如同 gapply,對 SparkDataFrame 的每個群組套用函數,並將結果收集回 R 的 data.frame。 函數的輸出應該是 data.frame。 但你不需要通過 schema。 請注意,如果無法將在所有分割區上執行該函式所產生的輸出擷取到驅動程式,並放入驅動程式記憶體中,gapplyCollect 可能會失敗。
# determine six waiting times with the largest eruption time in minutes.
result <- gapplyCollect(
    df,
    "waiting",
    function(key, x) {
        y <- data.frame(key, max(x$eruptions))
        colnames(y) <- c("waiting", "max_eruption")
        y
    })
head(result[order(result$max_eruption, decreasing = TRUE), ])
執行透過 spark.lapply 散發的本地 R 函數
spark.lapply
與原生 R 中的 lapply 類似,spark.lapply 會對元素清單中的各個元素套用函式,並利用 Spark 分散運算。 它以類似 doParallel 或 lapply 類似於清單元素的方式套用函式。 所有計算的結果都應該可以容納在一台機器中。 如果這個條件不成立,你可以像 df <- createDataFrame(list) 這樣操作,然後使用 dapply。
# perform distributed training of multiple models with spark.lapply. Here, we pass
# a read-only list of arguments which specifies family the generalized linear model should be.
families <- c("gaussian", "poisson")
train <- function(family) {
  model <- glm(Sepal.Length ~ Sepal.Width + Species, iris, family = family)
  summary(model)
}
# return a list of model's summaries
model.summaries <- spark.lapply(families, train)

# print the summary of each model
print(model.summaries)
從 SparkR 執行 SQL 查詢
你可以將 SparkR DataFrame 註冊為暫存視圖,這樣就能對其資料執行 SQL 查詢。 此 sql 函式使應用程式能以程式方式執行 SQL 查詢,並將結果以 SparkR DataFrame 回傳。
# Register earlier df as temp view
createOrReplaceTempView(df, "eruptions")

# Create a df using a SparkSQL query
waiting <- sql("SELECT waiting FROM eruptions where waiting>70 ")

head(waiting)
機器學習服務
SparkR 公開了大多數 MLLib 演算法。 在內部運作機制中,SparkR 使用 MLlib 訓練模型。
下列範例示範如何使用 SparkR 建置 Gaussian GLM 模型。 若要執行線性迴歸,請將系列設定為 "gaussian"。 若要執行邏輯迴歸,請將系列設定為 "binomial"。 使用 SparkML GLM 時,SparkR 會自動執行分類特徵的單熱編碼,讓你不必手動完成。 除了字串與雙字型功能外,你也可以套用 MLlib 向量功能,以與其他 MLlib 元件相容。
想了解更多支援哪些機器學習演算法,請造訪 SparkR 和 MLlib 的文件。
# create the DataFrame
cars <- cbind(model = rownames(mtcars), mtcars)
carsDF <- createDataFrame(cars)

# fit a linear model over the dataset.
model <- spark.glm(carsDF, mpg ~ wt + cyl, family = "gaussian")

# model coefficients are returned in a similar format to R's native glm().
summary(model)